


Database Articles
SQL Window Functions: Practical Examples Every Analyst Needs
Microservices vs Monolith: Making the Right Architectural Choice
Get In Touch For Details! Request More Information
What is Normalization in DBMS? An Informative Guide [2026]
Sep 24, 2026 8 Min Read 9084 Views
(Last Updated)
Ever opened a database table and found the same customer address typed out fifty different times, with a few of them spelled slightly differently? That mess is exactly what normalization exists to fix.
Normalization in DBMS is the process of organizing data so it’s stored efficiently, with little to no repeated information, by splitting large tables into smaller, connected ones. This guide covers what normalization is, all four major normal forms including BCNF, how to apply it step by step, and when denormalization is actually the smarter choice.
Table of contents
- TL;DR Summary
- What is Normalization?
- Why Should You Care About Normalization?
- How Does Normalization Work?
- The Steps of Normalization
- The Normal Forms
- First Normal Form (1NF)
- Second Normal Form (2NF)
- Third Normal Form (3NF)
- Boyce-Codd Normal Form (BCNF): Going Beyond 3NF
- 4NF and 5NF: Do You Need to Go That Far?
- Fourth Normal Form (4NF)
- Fifth Normal Form (5NF)
- Normal Forms at a Glance
- Why Bother Going Through All These Steps?
- Normalization vs Denormalization: When to Use Which
- Normalization in Real-World Database Design: A Complete Worked Example
- Implementing Normalization: A Step-by-Step Guide
- Step 1: Analyze Your Data
- Step 2: Define Primary Keys
- Step 3: Break Down Data into Related Tables
- Step 4: Eliminate Redundancy
- Step 5: Ensure Referential Integrity
- Step 6: Test and Validate Your Database
- Common Mistakes to Avoid With Normalization in DBMS
- Normalization Interview Questions You Should Be Ready For
- Conclusion
- FAQs
- Why is it important to have atomic values in a table?
- Can you achieve normalization without using primary keys?
- Why is it necessary to eliminate transitive dependencies in 3NF?
- What is denormalization, and when might it be used?
- Is normalization always beneficial for all types of databases?
TL;DR Summary
- What it is: organizing tables in a database so the same data isn’t stored more than once
- Core normal forms: 1NF, 2NF, 3NF, and BCNF, each one stricter than the last
- Why it matters: less wasted storage, fewer inconsistencies, and simpler updates
- The trade-off: more normalized tables mean more joins, which is why denormalization exists for read-heavy systems
- Where you’ll use it: designing any relational database, from a small app to a large enterprise system
Databases are the backbone of pretty much every app and business today. They collect, store, and retrieve data constantly. But if that data isn’t organized well, small problems (like a typo in an address) can quietly turn into big, messy ones. That’s where normalization in DBMS comes in.
What is Normalization?
Let us start with the basics. When you work with database management systems, you might have heard the term normalization quite a bit. But what exactly does it mean? Let’s break it down in simple terms.
Normalization is a process that helps you organize the data in your database more efficiently. Think of it like cleaning up a messy room. Instead of having things scattered all over the place, you put them in their right spots so you can easily find what you need and keep everything in order.
Why Should You Care About Normalization?
A few solid reasons to actually learn this instead of skipping it:
- Less repeated data. Storing the same information multiple times wastes space and invites mistakes. Normalization makes sure each fact lives in exactly one place.
- Better data integrity. Your data stays accurate and consistent, instead of having five slightly different versions of the same customer’s address floating around.
- Faster queries. A well-organized database generally runs queries more efficiently.
- Easier updates. Change something in one place, and it’s correct everywhere. No hunting down every copy.
Learn: Best MySQL Course Online with Certification
How Does Normalization Work?
The short version: you take one big table and split it into smaller, related ones.
Say you run a small online store and want to track orders, customers, and products. Without normalization, you might end up with one table like this:
| OrderID | CustomerName | CustomerAddress | ProductName | ProductPrice |
|---|---|---|---|---|
| 1 | John Doe | 123 Elm St | Widget A | 10 |
| 2 | Jane Smith | 456 Oak St | Widget B | 15 |
| 3 | John Doe | 123 Elm St | Widget C | 20 |
This has real problems: John’s address shows up twice, so if he moves, you’d need to update it in more than one place, and updating a product’s price means editing every order row that mentions it.
The fix: split this into three separate tables, similar to how you’d structure tables in a database system like MySQL.
Customers Table:
| CustomerID | CustomerName | CustomerAddress |
|---|---|---|
| 1 | John Doe | 123 Elm St |
| 2 | Jane Smith | 456 Oak St |
Products Table:
| ProductID | ProductName | ProductPrice |
|---|---|---|
| 1 | Widget A | 10 |
| 2 | Widget B | 15 |
| 3 | Widget C | 20 |
Orders Table:
| OrderID | CustomerID | ProductID |
|---|---|---|
| 1 | 1 | 1 |
| 2 | 2 | 2 |
| 3 | 1 | 3 |
Now John’s address only exists once. Moving means one update, not several. And changing a product’s price is a single edit, not a search-and-replace across every order.
The Steps of Normalization
Normalization typically follows a series of steps called normal forms, each building on the previous one:
- First Normal Form (1NF): every table gets a primary key, and every column holds a single, indivisible value. No lists crammed into one field.
- Second Normal Form (2NF): builds on 1NF; every non-key column must depend on the whole primary key, not just part of it.
- Third Normal Form (3NF): builds on 2NF; no non-key column should depend on another non-key column.
- Boyce-Codd Normal Form (BCNF): a stricter version of 3NF for a specific edge case involving overlapping candidate keys.
Normalization might seem like a technical and complex process, but it’s really about making your data easier to manage, more consistent, and more efficient. Let us understand more about this further!
Read More: Mastering Database Management: A Beginner’s Guide
The Normal Forms
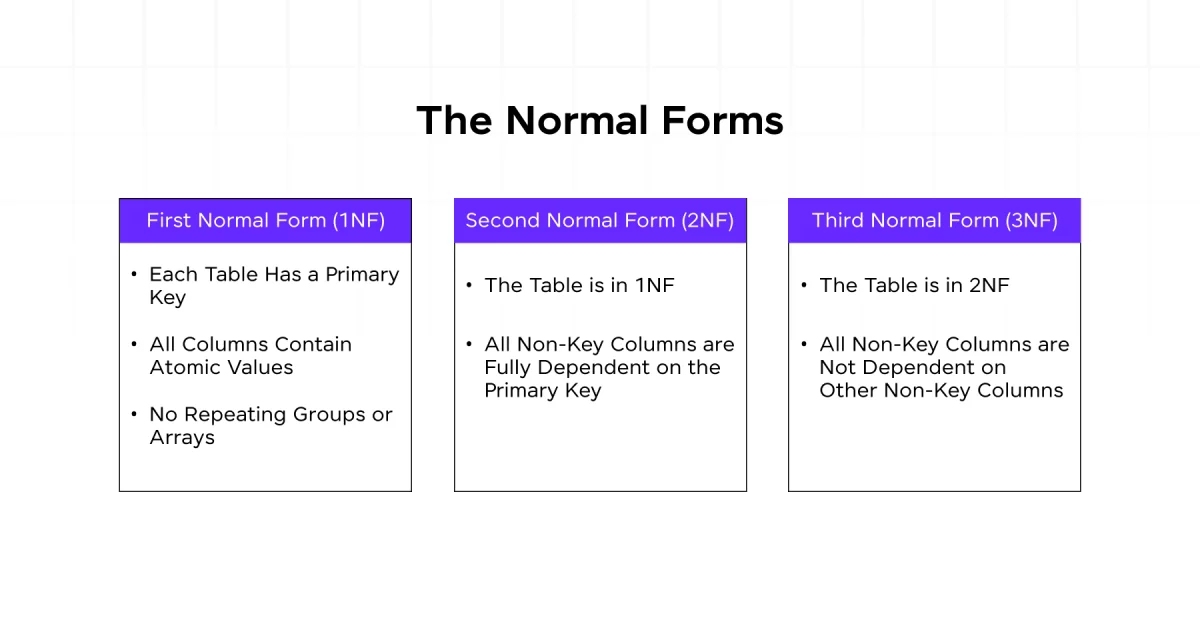
Now that you have a basic understanding of what normalization is and why it’s important, let’s dive into the details of the normal forms.
But before we go any further, it is important that you have a basic understanding of data science. If not, consider enrolling in a professionally certified online Data Science Course that teaches you everything about databases and helps you get started as a data scientist.
Additionally, if you want to explore SQL through a self-paced course, try HCL GUVI’s SQL Server self-paced course.
You have already seen a gist of normal forms in the previous section. Let us see about it in detail. Each normal form builds on the previous one to help you achieve a more structured and efficient database.
First Normal Form (1NF)
The First Normal Form (1NF) is the foundational step in the normalization process. To achieve 1NF, you need to ensure that your table meets the following criteria:
- Each Table Has a Primary Key: This is a unique identifier for each record in your table. Think of it as a way to uniquely tag every piece of data.
- All Columns Contain Atomic Values: This means that each column should hold only one piece of information. For example, instead of having a “PhoneNumbers” column that stores multiple numbers separated by commas, you should have a separate row for each phone number.
- No Repeating Groups or Arrays: You should not have columns that contain lists or sets of values.
Example:
Before 1NF:
| OrderID | CustomerName | ProductList |
|---|---|---|
| 1 | John Doe | Widget A, Widget B |
| 2 | Jane Smith | Widget C, Widget D |
After 1NF:
| OrderID | CustomerName | ProductName |
|---|---|---|
| 1 | John Doe | Widget A |
| 1 | John Doe | Widget B |
| 2 | Jane Smith | Widget C |
| 2 | Jane Smith | Widget D |
In this example, we’ve broken down the “ProductList” into individual rows, making the table comply with 1NF.
Second Normal Form (2NF)
The Second Normal Form (2NF) builds on the First Normal Form. To achieve 2NF, you need to ensure that your table meets the following criteria:
- The Table is in 1NF: This means you’ve already applied the rules of the First Normal Form.
- All Non-Key Columns are Fully Dependent on the Primary Key: This means that every non-key column should be directly related to the entire primary key, not just a part of it.
Example:
Before 2NF:
| OrderID | ProductID | CustomerName | ProductName | ProductPrice |
|---|---|---|---|---|
| 1 | 101 | John Doe | Widget A | 10 |
| 2 | 102 | Jane Smith | Widget B | 15 |
After 2NF: Orders Table:
| OrderID | ProductID | CustomerID |
|---|---|---|
| 1 | 101 | 1 |
| 2 | 102 | 2 |
Customers Table:
| CustomerID | CustomerName |
|---|---|
| 1 | John Doe |
| 2 | Jane Smith |
Products Table:
| ProductID | ProductName | ProductPrice |
|---|---|---|
| 101 | Widget A | 10 |
| 102 | Widget B | 15 |
In this example, we’ve separated the customer and product information into their own tables. The Orders table now only references these entities by their IDs.
Third Normal Form (3NF)
The Third Normal Form (3NF) takes normalization a step further. To achieve 3NF, you need to ensure that your table meets the following criteria:
- The Table is in 2NF: This means you’ve already applied the rules of the Second Normal Form.
- All Non-Key Columns are Not Dependent on Other Non-Key Columns: This means that non-key columns should depend only on the primary key and not on other non-key columns.
Example:
Before 3NF:
| OrderID | CustomerID | CustomerName | CustomerAddress |
|---|---|---|---|
| 1 | 1 | John Doe | 123 Elm St |
| 2 | 2 | Jane Smith | 456 Oak St |
After 3NF: Orders Table:
| OrderID | CustomerID |
|---|---|
| 1 | 1 |
| 2 | 2 |
Customers Table:
| CustomerID | CustomerName | CustomerAddress |
|---|---|---|
| 1 | John Doe | 123 Elm St |
| 2 | Jane Smith | 456 Oak St |
In this example, we’ve moved the “CustomerAddress” into the Customers table, ensuring that each piece of data is stored only once and is directly related to the primary key.
Boyce-Codd Normal Form (BCNF): Going Beyond 3NF
BCNF (Boyce-Codd Normal Form), sometimes called 3.5NF, is a stricter version of 3NF built for tables with overlapping candidate keys. A table satisfies BCNF when:
- It’s already in 3NF.
- Every determinant is a candidate key. For every functional dependency X → Y in the table, X must be a superkey, a column or combination of columns that can uniquely identify a row.
This second condition is what 3NF alone doesn’t catch. A table can pass every 3NF rule and still carry hidden redundancy if a non-key column determines part of a candidate key.
Example:
Before BCNF:
| StudentID | Subject | Instructor |
|---|---|---|
| 1 | Math | Mr. Smith |
| 1 | Physics | Mr. Jones |
| 2 | Math | Mr. Smith |
| 2 | Physics | Ms. Lee |
Here, each instructor teaches only one subject, so Instructor determines Subject. But Instructor isn’t a candidate key on its own, the candidate keys are {StudentID, Subject} and {StudentID, Instructor}.
Since Instructor determines Subject without being a superkey, this table fails BCNF even though it can satisfy 3NF.
After BCNF, split into two tables:
Instructor-Subject Table:
| Instructor | Subject |
|---|---|
| Mr. Smith | Math |
| Mr. Jones | Physics |
| Ms. Lee | Physics |
Student-Instructor Table:
| StudentID | Instructor |
|---|---|
| 1 | Mr. Smith |
| 1 | Mr. Jones |
| 2 | Mr. Smith |
| 2 | Ms. Lee |
Separating the instructor-subject relationship from the student-instructor relationship removes the redundancy and satisfies BCNF, since Instructor is now a proper key in its own table.
Should you always aim for BCNF? For most real applications, 3NF is enough, and pushing every table to BCNF can sometimes make your queries more complicated than the benefit is worth. It’s genuinely useful to know for interviews and for the specific edge case of overlapping candidate keys, but 3NF remains the practical default for everyday schema design.
4NF and 5NF: Do You Need to Go That Far?
BCNF isn’t actually the end of the line, two more normal forms exist beyond it. In practice, you’ll rarely need either, but they’re worth understanding conceptually.
Fourth Normal Form (4NF)
4NF eliminates multi-valued dependencies, cases where two independent, multi-valued facts about the same entity get crammed into one table, forcing every combination to be listed out.
Example: imagine a table tracking which courses a student takes and which hobbies they have, with both stored in the same table:
| StudentID | Course | Hobby |
|---|---|---|
| 1 | Math | Chess |
| 1 | Math | Painting |
| 1 | Physics | Chess |
| 1 | Physics | Painting |
Courses and hobbies have nothing to do with each other, but because they’re combined in one table, every course has to be paired with every hobby. With 3 courses and 4 hobbies, you’d need 12 rows instead of 7.
Splitting into a Student-Course table and a separate Student-Hobby table fixes this, each fact is recorded once, independently.
Fifth Normal Form (5NF)
5NF (also called Project-Join Normal Form) handles an even rarer case: tables that can only be correctly reconstructed by joining three or more smaller tables together, where no simpler dependency explains the constraint.
It typically shows up in complex many-to-many-to-many relationships, like which agents sell which products for which companies, where not every agent-company-product combination is actually valid.
The honest practical takeaway: 4NF and 5NF are genuinely rare to need in everyday application development. They matter most in academic contexts, database theory interviews, and a handful of complex enterprise schemas. For the vast majority of real projects, getting comfortable through 3NF or BCNF covers what you’ll actually use.

Normal Forms at a Glance
| Normal Form | Core Rule | What It Eliminates |
|---|---|---|
| 1NF | Atomic values, no repeating groups, needs a primary key | Multi-valued columns and repeating groups |
| 2NF | Must be in 1NF; non-key columns depend on the whole key | Partial dependency on a composite key |
| 3NF | Must be in 2NF; no non-key column depends on another | Transitive dependency |
| BCNF | Every determinant must be a candidate key | Redundancy from overlapping candidate keys |
Why Bother Going Through All These Steps?
A quick recap of what normalization in DBMS actually gets you for the effort:
- Fewer inconsistencies, since eliminating redundancy removes most of the ways data can contradict itself.
- Simpler maintenance, because a clear structure makes updates less error-prone.
- Better performance, since a normalized database generally handles queries more efficiently.
Related read: A Complete Guide To Become A Data Scientist In 3 Months
Normalization vs Denormalization: When to Use Which
Normalization in DBMS isn’t always the final answer. Sometimes going the other way makes more sense.
| Factor | Normalization | Denormalization |
|---|---|---|
| Main goal | Eliminate redundancy, keep data consistent | Improve read speed by cutting down on joins |
| Best for | Write-heavy systems, transactional data (OLTP) | Read-heavy systems, analytics and reporting (OLAP) |
| Trade-off | More tables, more joins needed | More storage used, higher risk of inconsistency |
| Common use case | Banking systems, order management | Data warehouses, dashboards, reporting tools |
A good rule of thumb: normalize first to get a clean design, then denormalize specific tables only once you’ve actually measured a performance problem, not as your starting point.
Normalization in Real-World Database Design: A Complete Worked Example
The examples so far each isolate one normal form. Here’s how it actually looks when you take one messy, real table all the way through the full process.
Scenario: a library wants to track book checkouts, storing everything in one giant spreadsheet-style table.
Unnormalized starting table:
| CheckoutID | MemberID | MemberName | BookISBN | BookTitle | CheckoutDate |
|---|---|---|---|---|---|
| 1 | 501 | Asha Rao | ISBN001 | Clean Code | 2026-01-05 |
| 2 | 501 | Asha Rao | ISBN002 | The Pragmatic Programmer | 2026-01-05 |
| 3 | 502 | Ben Lee | ISBN001 | Clean Code | 2026-01-06 |
Step 1, apply 1NF: every column already holds a single value, and CheckoutID works as a primary key, so this table already satisfies 1NF.
Step 2, check for 2NF: if we imagine the natural key here is {MemberID, BookISBN} instead of CheckoutID, MemberName depends only on MemberID, and BookTitle depends only on BookISBN, both partial dependencies, a 2NF violation.
Step 3, apply 3NF and split into related tables:
Members Table:
| MemberID | MemberName |
|---|---|
| 501 | Asha Rao |
| 502 | Ben Lee |
Books Table:
| BookISBN | BookTitle |
|---|---|
| ISBN001 | Clean Code |
| ISBN002 | The Pragmatic Programmer |
Checkouts Table:
| CheckoutID | MemberID | BookISBN | CheckoutDate |
|---|---|---|---|
| 1 | 501 | ISBN001 | 2026-01-05 |
| 2 | 501 | ISBN002 | 2026-01-05 |
| 3 | 502 | ISBN001 | 2026-01-06 |
Step 4, verify BCNF: the only non-trivial functional dependencies left are MemberID → MemberName and BookISBN → BookTitle, and in both cases the determinant (MemberID, BookISBN) is a candidate key of its own table, so this schema already satisfies BCNF.
The result: a member’s name is stored once, a book’s title is stored once, and adding a new checkout never requires re-typing information that already exists elsewhere.
Implementing Normalization: A Step-by-Step Guide
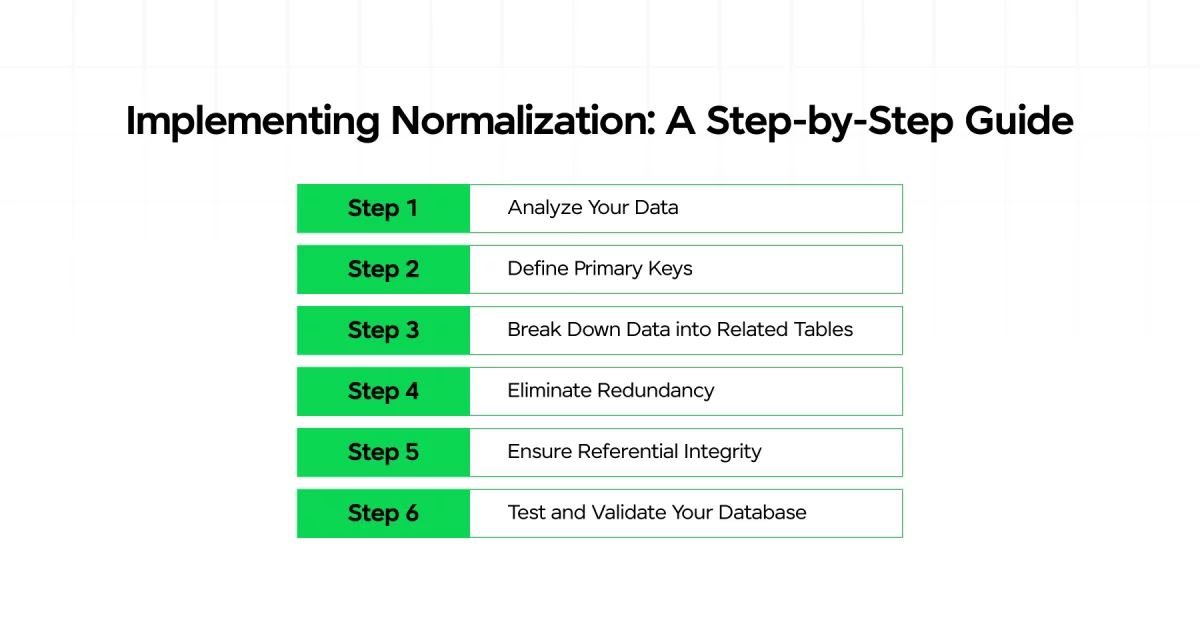
Now that you understand the concept and importance of normalization, let’s dive into how you can implement it in your database.
Implementing normalization might sound technical, but if you break it down into clear steps, it becomes much more manageable.
Step 1: Analyze Your Data
The first step in normalization is to thoroughly analyze your data. You need to understand the types of data you have and how they relate to each other. Start by asking yourself:
- What information do you need to store?
- How is this information currently organized?
- What are the relationships between different pieces of data?
Step 2: Define Primary Keys
Next, identify the primary keys for your tables. A primary key is a unique identifier for each record in a table. It helps you uniquely identify each row of data.
Step 3: Break Down Data into Related Tables
Start dividing your data into related tables based on the normal forms. This means creating separate tables for each type of entity (e.g., books, authors, sales).
Step 4: Eliminate Redundancy
After breaking down your data, review your tables to ensure there’s no redundant data. Each piece of information should be stored only once. If you find any data that repeats across tables, adjust your structure to eliminate it.
Step 5: Ensure Referential Integrity
Referential integrity means that relationships between tables are maintained correctly. Use foreign keys to link tables together. A foreign key in one table points to a primary key in another table, creating a relationship between the two.
Explore More: Best SQL Server Course Online with Certification
Step 6: Test and Validate Your Database
After organizing your data and establishing relationships, it’s crucial to test your database. Run various queries to ensure that the data retrieval works as expected. Check for:
- Data Integrity: Verify that data is consistent across tables.
- Query Performance: Ensure that queries run efficiently without unnecessary delays.
- Ease of Maintenance: Make sure that updating information in one place reflects correctly across the database.
This is how you can implement normalization in your database and experience the pleasure of cleaning up the messy data.
If you want to learn more about Normalization and Databases in data science, then consider enrolling in HCL GUVI’s Certified Data Science Career Program which not only gives you theoretical knowledge but also practical knowledge with the help of real-world projects.
Alternatively, if you would like to explore SQL through a Self-paced course, try
HCL GUVI’s SQL Server Self-Paced certification course.
Also Read: Is Data Science A Good Career Choice In 2026?
Common Mistakes to Avoid With Normalization in DBMS
- Over-normalizing small schemas. Pushing every table in a small app all the way to BCNF adds complexity without a real payoff.
- Mixing up normalization with indexing. They solve different problems, normalization is about structure and redundancy, while indexing is about query speed. You typically need both, not one instead of the other.
- Skipping the functional dependency analysis. Jumping straight into splitting tables without identifying dependencies first often produces a schema that looks normalized but still hides redundancy.
- Denormalizing before you have a proven problem. Adding denormalized tables before measuring an actual performance issue solves something you don’t have yet.
- Never revisiting the schema. A schema that was correctly normalized for the original requirements can quietly develop redundancy again as new features get added over time.
Normalization Interview Questions You Should Be Ready For
Since normalization comes up constantly in technical interviews, here are the questions worth having a solid, ready answer for.
1. What’s the difference between a partial dependency and a transitive dependency?
A partial dependency happens when a non-key column depends on only part of a composite primary key, this is what 2NF eliminates.
A transitive dependency happens when a non-key column depends on another non-key column instead of the primary key directly, this is what 3NF eliminates.
2. Can you give an example of a table that’s in 3NF but not BCNF?
Yes, the classic case is a table with overlapping candidate keys, like the Student-Subject-Instructor example above.
It satisfies every 3NF rule but still has redundancy because a non-key column (Instructor) determines part of a candidate key (Subject) without being a candidate key itself.
3. Why might you deliberately denormalize a database?
To improve read performance in analytics or reporting systems, where fewer joins mean faster queries, at the cost of some redundancy and more complex updates.
4. What’s the difference between a candidate key and a primary key?
A candidate key is any column or combination of columns that could uniquely identify a row. A table can have several candidate keys; the primary key is simply the one you choose to actually use as the main identifier.
5. Is a table with only two columns always automatically in BCNF?
Not necessarily, it depends on the functional dependencies, but two-column tables are far less likely to violate BCNF since there’s less room for a non-key column to determine part of a key.
6. What’s a practical downside of over-normalizing a schema?
More tables means more joins for every query, which can hurt performance and make the schema harder to reason about, especially in read-heavy systems where the redundancy normalization removes was never actually causing problems.
Conclusion
In conclusion, implementing normalization in your database might seem like a complex task, but by following these clear steps, you can achieve a well-organized, efficient, and scalable database.
Start by analyzing your data, defining primary keys, breaking down data into related tables, eliminating redundancy, ensuring referential integrity, and testing your database thoroughly.
Remember, normalization is an ongoing process that evolves with your database needs. By keeping your database well-structured, you ensure its longevity and reliability, making your data management tasks much easier in the long run.
FAQs
1. Why is it important to have atomic values in a table?
Atomic values ensure that each column contains only one piece of information, making the data easier to manage and query.
2. Can you achieve normalization without using primary keys?
No, primary keys are essential for normalization as they uniquely identify each record and establish relationships between tables.
3. Why is it necessary to eliminate transitive dependencies in 3NF?
Eliminating transitive dependencies ensures that non-key columns are only dependent on the primary key, which reduces redundancy and improves data integrity.
4. What is denormalization, and when might it be used?
Denormalization is the process of combining tables to reduce the complexity of queries and improve performance in certain scenarios, such as read-heavy applications.
5. Is normalization always beneficial for all types of databases?
While normalization is beneficial for ensuring data integrity and reducing redundancy, in some cases, such as read-heavy applications, denormalization might be preferred for performance reasons.
Success Stories

About the Author
Jebasta
I translate the language of data into stories that anyone can understand. As a writer with a data science background, I simplify analytics, AI, and decision-making so beginners and enthusiasts can confidently explore the world of data.
View all posts by Jebasta
Connect with me @






Did you enjoy this article?