


Interview Articles
InfyTQ Interview Experience 2026: Process, Questions, Preparation & Tips
Deloitte NLA Interview Experience 2026: Rounds, Questions and Preparation - Best Guide
Capgemini Exceller Interview Questions 2026: Coding, Technical, HR, and AI Prep - Best Guide
Wipro Elite NTH Interview Experience 2026: What Candidates Say
Get In Touch For Details! Request More Information
Top 30 Deep Learning Interview Questions and Answers
Sep 28, 2026 15 Min Read 5084 Views
(Last Updated)
Deep learning interviews test much more than definitions of neural networks or activation functions. Interviewers increasingly expect candidates to understand how models learn, why architectures behave differently, how training problems are diagnosed, and which techniques work for specific datasets and applications.
A beginner may be asked about artificial neural networks, epochs, activation functions, or loss functions. Intermediate candidates should be ready to explain CNNs, RNNs, LSTMs, optimizers, regularization, and transfer learning. Advanced interviews often move into Transformers, attention mechanisms, architecture selection, model optimization, domain shift, and scenario-based troubleshooting.
This guide covers 50 Deep Learning interview questions and answers, divided into beginner, intermediate, and advanced levels. It also includes practical scenarios to help you prepare for technical discussions rather than memorizing definitions.
Quick Answer
Deep Learning interviews generally evaluate five areas:
- Fundamentals: Neural networks, neurons, weights, biases, layers, epochs, batches, and iterations.
- Model Architectures: ANN, CNN, RNN, LSTM, GRU, autoencoders, GANs, and Transformers.
- Training and Optimization: Activation functions, loss functions, optimizers, learning rates, batch normalization, and backpropagation.
- Model Performance: Overfitting, underfitting, regularization, dropout, evaluation metrics, and hyperparameter tuning.
- Applied Deep Learning: Computer vision, NLP, transfer learning, fine-tuning, GPUs, domain shift, and real-world troubleshooting.
Table of contents
- What is Deep Learning?
- Important Deep Learning Concepts for Interviews
- Top 30 Deep Learning Interview Questions and Answers
- Beginner-Level Deep Learning Interview Questions
- Intermediate-Level Deep Learning Interview Questions
- Advanced Deep Learning Interview Questions
- Scenario-Based Interview Questions
- You are training a neural network and notice that training accuracy keeps increasing, but validation accuracy starts dropping. What would you do?
- You are building an image classification model, but you only have a small labeled dataset. How would you approach the problem?
- Your CNN performs well on training images but fails when users upload images under different lighting conditions. How would you improve it?
- You are training a deep learning model, but the loss fluctuates heavily and does not converge. What would you check first?
- You are building a sentiment analysis model, but it gives different predictions for sentences that mean almost the same thing. What could be wrong?
- Your LSTM performs well on short sequences but loses important information in very long sequences. What would you try?
- You have trained a highly accurate classification model, but one important minority class is rarely detected. What would you do?
- Your model worked well during development but performs poorly after deployment. How would you investigate the issue?
- You are working on a real-time application, but your deep learning model is too slow for production. How would you optimize it?
- You have access to a large pretrained model, but your company has limited computing resources. Would you train it from scratch?
- Your validation loss suddenly becomes NaN during training. How would you debug it?
- You are comparing two deep learning models. One has slightly higher accuracy but takes three times longer to make predictions. Which one would you choose?
- You are building a medical-image model where missing a positive case is more serious than generating a false alarm. Which metric would you prioritize?
- Your Transformer model gives strong results, but training requires too much GPU memory. What would you change?
- Your manager asks you to improve a deep learning model immediately. Would you start by adding more layers?
- Your model has excellent offline metrics, but users say its predictions are not useful. What would you investigate?
- Your model's performance varies significantly between different user groups. What would you do?
- You improve model accuracy after adding more features, but inference becomes slower and more expensive. How would you decide whether to keep them?
- Your model performs well today, but performance gradually declines over several months. What could be happening?
- You have several models with similar validation scores. How would you choose the final one?
- 💡 Did You Know?
- How to Prepare for a Deep Learning Interview
- What Deep Learning Topics Should Freshers Prioritize?
- What Should Experienced Candidates Prepare Differently?
- What Do Interviewers Look for in Deep Learning Candidates?
- How Should You Answer Deep Learning Scenario Questions in an Interview?
- Conclusion
- FAQs
- How should I prepare for a deep learning interview?
- What is the best way to answer deep learning interview questions?
- What are some quick tips to perform better in a deep learning interview?
- How can I handle scenario-based deep learning questions confidently?
- What mistakes should I avoid in a deep learning interview?
What is Deep Learning?
Deep learning is a specialized type of machine learning that uses multiple layers of artificial neural networks to train from large amounts of data to produce accurate results. Deep learning models try to imitate the human learning process. In general, deep learning models consist of three layers of nodes: the Input layer, the Hidden layers, and the Output layer. Between each connection of neurons, it has weight that adjusts as the network learns.
Important Deep Learning Concepts for Interviews
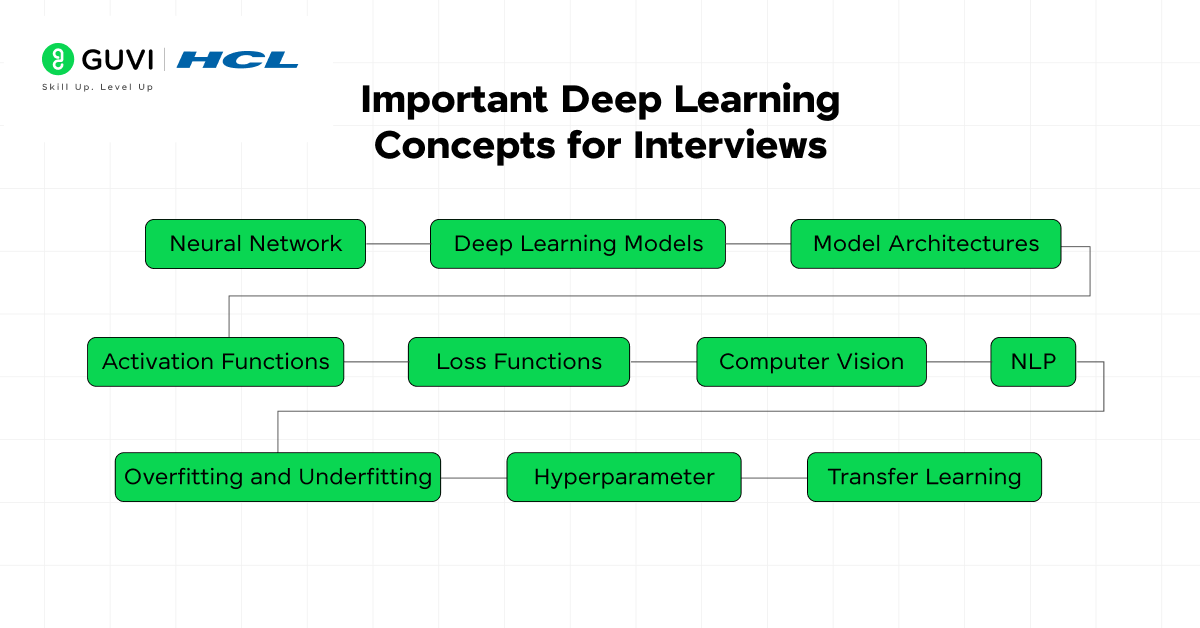
This section covers the important deep learning concepts that are essential for interviews. Since deep learning is a subset of machine learning and artificial intelligence, it consists of advanced learning methodologies along with AI.
- Neural Network: It is based on the working of the human brain, which consists of multiple layers of interconnected nodes.
- Deep Learning Models: Learning about different models, their use cases, advantages, and disadvantages helps in the efficient use of models.
- Model Architectures: Understanding the different model architectures, including the number and types of layers used, helps in choosing the best model for the problem statement.
- Activation Functions: It determine whether the node should be activated or not, helping to capture the nonlinear relationship between input and output.
- Loss Functions: It measures the model’s performance, prediction accuracy by comparing it with targeted values. It also provides feedback that is later used to update the model weight through optimization.
- Computer Vision: It is a field in deep learning that enables machines to understand information from visual data through videos.
- NLP: Natural language processing involves teaching machines to understand and generate human language.
- Overfitting and Underfitting: These concepts are used to understand the model’s training levels.
- Hyperparameter: These are external configurations that are set before training a model to increase the model’s performance and training efficiency.
- Transfer Learning: It is an advanced type of training that pre-trains a model and fine-tunes it for specific tasks.
Can’t wait to start your journey in deep learning? Start with HCL Guvi’s free E-book on Mastering Data Science that provides a detailed roadmap towards machine learning, data science, AI, and deep learning.
Top 30 Deep Learning Interview Questions and Answers
Beginner-Level Deep Learning Interview Questions
1. What is ANN?
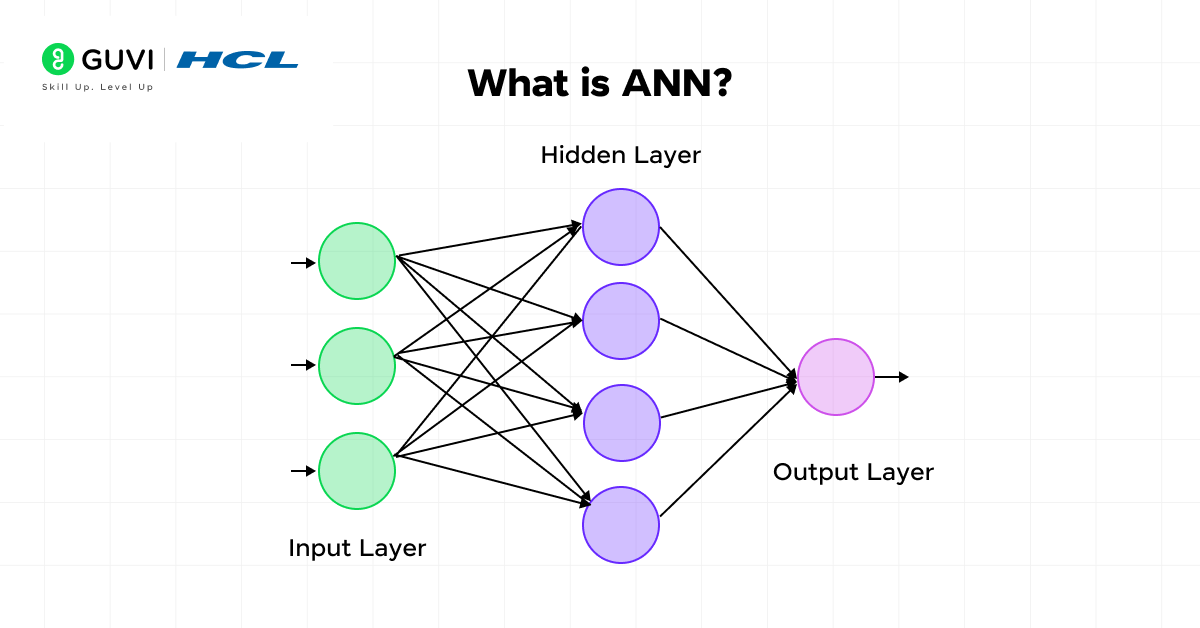
ANN stands for Artificial Neural Network. It is machine learning that is inspired by the structure and function of the human brain. The connected nodes between the layers of ANN are known as neurons that have weights to define the strong connections between neurons. These neurons process information, learn from data, and make predictions.
2. How would you choose the right deep learning model for your problem and data
There are certain factors, such as dataset types, problem structure, complexity, available resources, and performance goals, that you need to consider before choosing a deep learning model. For example:
- CNN is best for tasks based on images, RNNs for time series or sequential data, Multi-layer perceptron (MLP) for tabular data, and consider transfer learning with a pre-trained model for limited data.
- Perform lots of experiments and comparisons between the models using cross-validation and evaluation metrics to find the model that best fits the use case.
3. How would you evaluate the performance of deep learning models?
The performance of a deep learning model is evaluated using the machine learning model’s evaluation metrics. For classification models, metrics like accuracy, precision, F-1 score, and recall are used. For regression models, the MSE (Mean Squared Error) metric is used, and other metrics the confusion matrix, cross validation, provide a detailed overview between the actual and target values.
- What are the differences between single-layer and multilayer perceptrons?
A single-layer perceptron has only one layer of weights between the input and output layers. It can only solve linear problems.
A multilayer perceptron (MLP) has one or more hidden layers, which allows it to capture nonlinear patterns. It serves as a backbone for complex model architectures.
- What are Neural Networks? Give me its types.
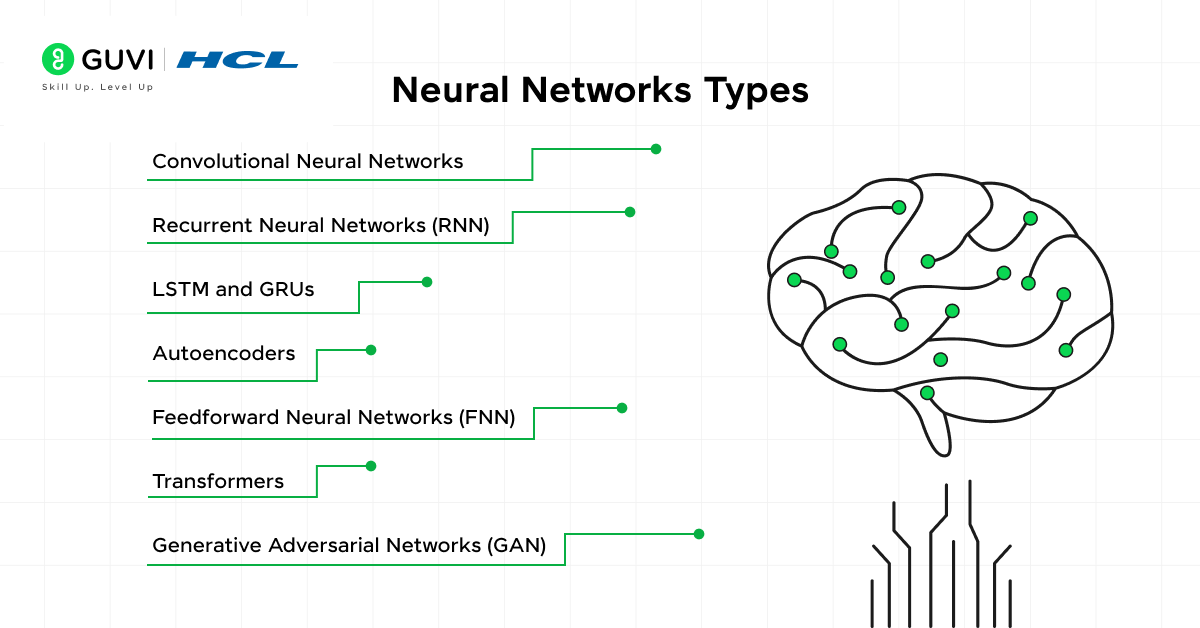
Neural networks are computer systems that imitate human nervous systems, working to learn from huge datasets to solve complex problems. There are many types of neural networks available, and people are working on creating new neural networks. Some of the common types are:
- Convolutional Neural Networks (CNN): It is used for tasks like object detection and image classification.
- Recurrent Neural Networks (RNN): Tasks include time series forecasting and text generation.
- LSTM and GRUs: These are used in speech synthesis, chatbots, and sentiment analysis.
- Autoencoders: Most of the tasks include dimensionality reduction, anomaly detection, and unsupervised learning.
- Feedforward Neural Networks (FNN): This is used for regression and classification tasks that have structured datasets.
- Generative Adversarial Networks (GAN): It is a recent model popular for generating images, styles, and synthetic data with super resolution.
- Transformers: It is suitable for natural language processing (NLP) tasks.
- What are the real-world applications of deep learning?
A wide range of industries use deep learning in the real world. Some of them are:
- Object detection for autonomous vehicles
- Customized chatbots for customer support
- Medical image diagnosis
- Predictive solutions in the retail industry for trend prediction
- You are using a deep neural network for a prediction task. After training your model, you notice that it is strongly overfitting the training set and that the performance on the test isn’t good. What can you do to reduce overfitting?
To reduce overfitting in a deep neural network, changes can be made in three places/stages: The input data to the network, the network architecture, and the training process.
- The input data to the network:
- Check if all the features are available and reliable
- Check if the training sample distribution is the same as the validation and test set distributions. Because if there is a difference in validation set distribution, then it is hard for the model to predict, as these complex patterns are unknown to the model.
- Check for train / valid data contamination (or leakage)
- The dataset size is enough; if not, try data augmentation to increase the data size
- The dataset is balanced
- Network architecture:
- Overfitting could be due to model complexity. Question each component:
- Can fully connected layers be replaced with convolutional + pooling layers?
- What is the justification for the number of layers and several neurons chosen? Given how hard it is to tune these, can a pre-trained model be used?
- Add regularization – lasso (l1), ridge (l2), elastic net (both)
- Add dropouts
- Add batch normalization
- How would you handle the overfitting in a deep learning model?
Overfitting occurs when the model is excessively trained and comfortable with the existing dataset; later, it will struggle to perform correct inference on any unseen data. The best way to handle deep learning model overfitting is by implementing regularization techniques such as L1 or L2 regularization with penalty terms that are added to the loss function. These strategies can then be combined with early stopping to finalize the training. Early stopping is the process of terminating the execution once the validation loss stops improving.
- When should you use deep learning over machine learning solutions?
Deep learning models are chosen when the dataset is large, unstructured, and to extract meaningful information from the irregular data. Understanding and experimenting with each deep learning model will help you choose the best model for specific use cases. Here are some of the problems that can be solved using deep learning solutions more efficiently.
- Image classification of animals and plants.
- Voice recognition, Translation, and other language-based tasks.
- Smart locks using face recognition in real-time images.
- Stock market predictions for the long term.
- What is CNN?
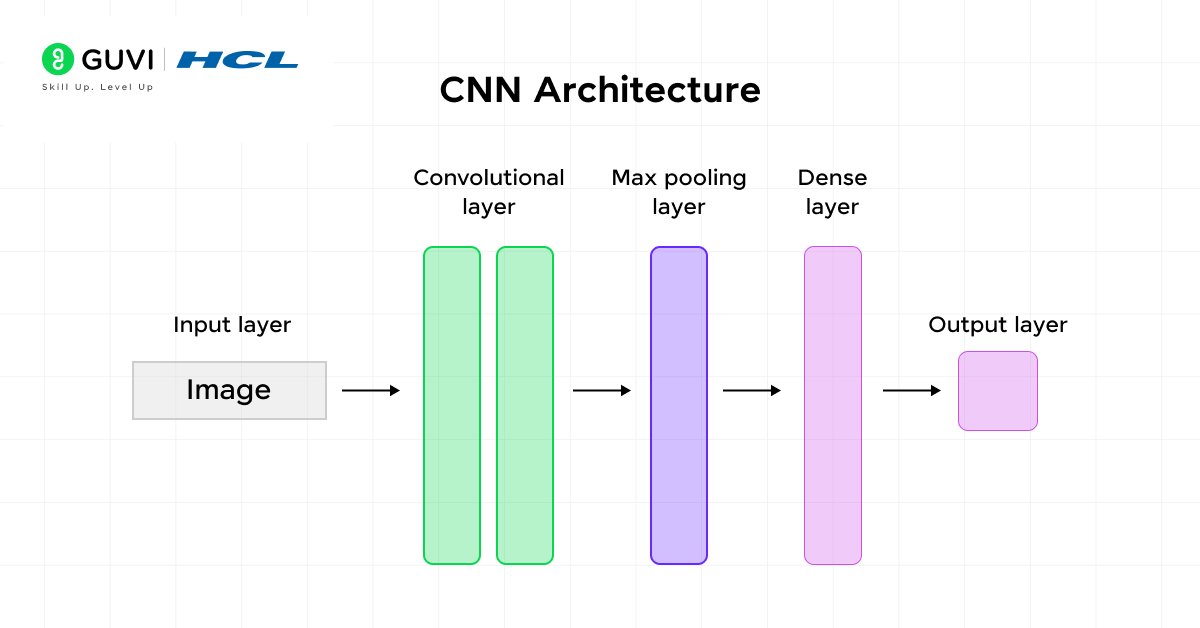
CNN is a type of neural network that stands for Convolutional Neural Network. It is mostly used for computer vision tasks that include real-time object detection, image classification, image processing, and segmentation. With the help of mathematical operations, it detects texture, structure, patterns, and edges from the images and uses them for providing solutions to specific problems.
Interested in learning more about artificial intelligence and machine learning? Then, be sure to enroll in HCL Guvi’s IIT-M Pravartak certified Artificial Intelligence & Machine Learning Course.
Intermediate-Level Deep Learning Interview Questions
- Can you name and explain a few hyperparameters used for training a neural network?
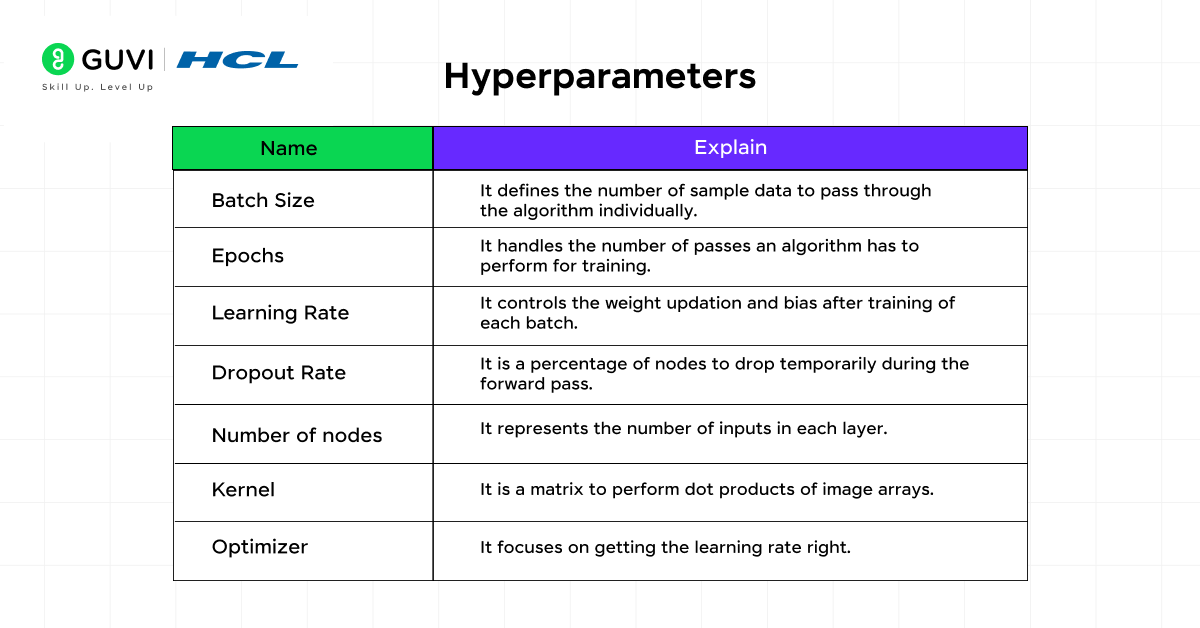
Hyperparameters are the set of parameters in the model which affect the performance of the model, but it is not learned from the data, and they can be changed manually.
- Batch Size: It defines the number of sample data to pass through the algorithm individually.
- Epochs: It handles the number of passes an algorithm has to perform for training.
- Learning Rate: It controls the weight updation and bias after training of each batch.
- Dropout Rate: It is the percentage of nodes to drop temporarily during the forward pass.
- Number of nodes: It represents the number of inputs in each layer.
- Kernel: It is a matrix to perform dot products of image arrays.
- Optimizer: It focuses on getting the learning rate right.
- What is the use of activation functions? Give me its types.
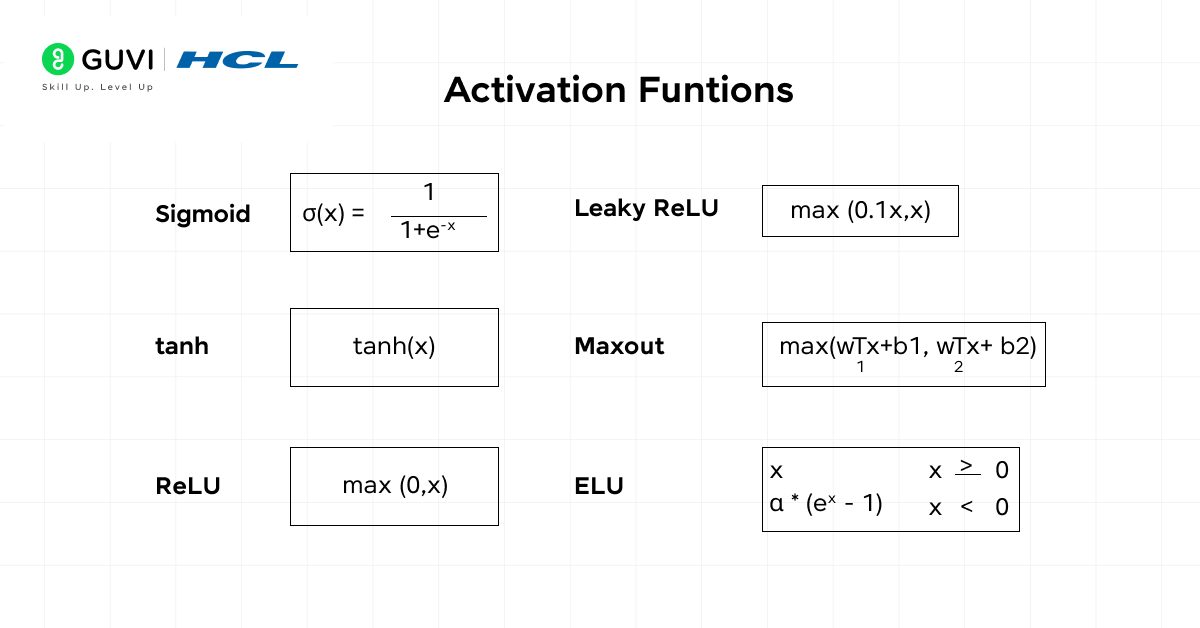
Activation functions play a crucial role in neural networks by introducing non-linearity to the data to find and learn complex patterns. It occurs at the neuron level during the processing of mapping the input into an output value. Without activation functions, neural networks will behave like a linear regression model. Some of the types of activation functions are:
- ReLU: It is the simplest and most common function.
- Sigmoid: It is used in binary classification because the values range between 0 and 1.
- Tanh: It is similar to sigmoid, but the output values range between -1 and 1.
- Leaky ReLU: It is a variant of ReLU that allows small negative values as outputs.
- Softmax: It converts all the logics into probabilities and is used in multi-classification problems.
13. Describe the process of generating text using a transformer-based language model.
Transformer-based language models such as GPT generate text autoregressively by predicting one token at a time based on the tokens that came before it. The process includes:
- Tokenization: The input prompt is split into tokens and converted into numerical token IDs.
- Embedding: Each token is mapped to a dense vector representation. Positional information is also added so the model can understand token order.
- Self-Attention: The model calculates attention scores between tokens using Query, Key, and Value representations. This helps it determine which earlier tokens are most relevant to the current context.
- Transformer Processing: The representations pass through multiple attention and feed-forward layers to build contextual token representations.
- Next-Token Prediction: The final hidden representation is converted into logits over the vocabulary.
- Decoding: A decoding strategy such as greedy decoding, temperature sampling, top-k, or top-p sampling selects the next token.
- Autoregressive Generation: The selected token is appended to the sequence and passed back into the model. This process repeats until an end token, stopping condition, or maximum token limit is reached.
14. What is computer vision, and why is it important?
Computer vision is a branch of artificial intelligence that enables machines to extract, process, and interpret information from visual data such as images and videos.
Deep learning models can identify objects, classify images, detect faces, segment scenes, track movement, and extract patterns from pixels.
Computer vision is important because it allows machines to automate visual tasks that normally require human observation. Common applications include:
- Object detection in autonomous vehicles
- Medical image analysis
- Facial recognition
- Manufacturing defect detection
- Surveillance systems
- OCR and document processing
- Image-based retail and inventory systems
15. Can you explain the concept of feature extraction in computer vision?
Feature extraction is the process of identifying useful visual patterns from raw image pixels.
In traditional computer vision, features such as edges, corners, textures, or shapes may be manually designed. In deep learning, CNNs learn these features automatically during training.
Early convolutional layers generally learn simple patterns such as:
- Edges
- Lines
- Corners
- Basic textures
Deeper layers combine these low-level features into more complex representations such as:
- Shapes
- Object parts
- Faces
- Vehicles
- Semantic regions
These extracted features are then used by later layers for tasks such as classification, detection, or segmentation.
16. Why should we use batch normalization?
Batch normalization normalizes the activations of a layer across a mini-batch and then applies learnable scale and shift parameters.
It helps make training more stable by keeping activation distributions within manageable ranges.
The major benefits include:
- Faster convergence: It can allow the model to train efficiently with larger learning rates.
- More stable gradients: It reduces sensitivity to parameter initialization and unstable activations.
- Reduced internal variation: It helps control changes in intermediate activation distributions during training.
- Regularization effect: Mini-batch statistics introduce some noise that can sometimes improve generalization.
- Easier optimization: It can make deep networks easier to train.
During inference, batch normalization typically uses running estimates of mean and variance collected during training.
17. What is a GPU and why is it required?
A GPU, or Graphics Processing Unit, is a processor designed to execute many numerical operations in parallel.
Deep learning models rely heavily on operations such as:
- Matrix multiplication
- Tensor operations
- Convolutions
- Attention calculations
- Gradient computation
A GPU contains thousands of processing cores that can perform these operations simultaneously. This makes it significantly faster than a CPU for large-scale neural network training.
GPUs are especially useful when working with:
- Large datasets
- Deep CNNs
- Transformers
- High-resolution images
- Large batch sizes
- Distributed training
GPUs are not always mandatory for small models, but they can reduce training time substantially for computationally intensive deep learning workloads.
18. What are the different layers in ANN?
An Artificial Neural Network generally contains three broad layer categories:
- Input Layer: Receives input features and passes them into the network.
- Hidden Layers: Transform the input through weighted operations, activation functions, and specialized processing.
- Output Layer: Produces the final prediction based on the task.
Common layer types include:
- Dense Layer: Connects each input neuron to each output neuron and applies weighted sums and activation functions.
- Convolutional Layer: Uses learnable filters to extract spatial patterns from images or structured grids.
- Recurrent Layer: Maintains hidden state across sequential time steps.
- Pooling Layer: Reduces spatial dimensions in CNNs.
- Dropout Layer: Randomly disables activations during training to reduce overfitting.
- Batch Normalization Layer: Normalizes intermediate activations and stabilizes training.
- Embedding Layer: Converts discrete tokens or categories into dense vector representations.
- Attention Layer: Learns relationships between different elements in a sequence.
The exact combination of layers depends on the data type and problem being solved.
19. What is forward and backward propagation?
| Forward Propagation | Backward Propagation |
|---|---|
| Input data moves from the input layer through hidden layers to the output layer. | The error signal moves backward from the output layer through earlier layers. |
| Each layer applies weights, biases, and activation functions. | Gradients are calculated using the chain rule. |
| The network generates predictions during this stage. | The gradients show how much each parameter contributed to the loss. |
| The loss function compares predictions with actual target values. | An optimizer uses the gradients to update weights and biases. |
| Used during both training and inference. | Used only during model training. |
Forward propagation computes the prediction, while backward propagation determines how the model parameters should change to reduce prediction error.
20. How are the number of hidden layers and neurons per hidden layer selected?
There is no universal formula for selecting the exact number of hidden layers or neurons. The architecture is usually chosen through experimentation based on the complexity of the problem and the available data.
Key factors include:
- Problem complexity: Simple tabular problems may require only a few layers, while vision or language tasks may require much deeper architectures.
- Dataset size: Larger models generally require more training data to avoid overfitting.
- Input dimensionality: High-dimensional inputs may require greater model capacity.
- Bias and variance: Too few neurons may cause underfitting, while too many can increase overfitting.
- Training and validation curves: These help determine whether additional capacity improves generalization.
- Compute resources: More layers and neurons increase training time, memory use, and inference cost.
- Hyperparameter tuning: Grid search, random search, Bayesian optimization, or tools such as Optuna can help compare different architectures.
Advanced Deep Learning Interview Questions
- Define epoch, iteration, and batches.
Epoch: It handles the amount of data that is being sent to the model for training at a time.
Iteration: It defines the number of iterations required to train the whole training dataset.
Batches: It is a subset of the training data that is processed in one go.
The relationship between Epoch, iteration, and batch size is given as:
Epoch = Number of iterations * Batch Size
Number of iterations = (Total number of sample data) / Batch Size
- What is fine-tuning in Deep learning?
Fine-tuning is a transfer learning technique where an existing pre-trained model (that is already trained on a large dataset) is further trained on a smaller, task-specific dataset. Instead of training the model entirely from scratch, fine-tuning just updates the model’s weights and other hyperparameters according to the required tasks.
- What is LSTM, and how does it work?
LSTM (Long Short-Term Memory) is a type of RNN that is designed to learn long-term dependencies in sequential data. An LSTM cell contains three gates: the Forget gate, input gate, and output gate. The forget gate decides what information needs to be stored and what needs to be discarded from the cell. The input gate selects which new information needs to be added, and the output gate determines the output from the current cell.
- What is GAN?
GAN (Generative Adversarial Network) is a type of deep learning model that combines two neural network models, such as a generator and discriminator, to compete against each other to generate new data. The generator model creates new data, where the discriminator model tries to distinguish between real and generated data, making the generator create real-like data. It is used to generate images, music, and text.
- What are the key components of a transformer model?
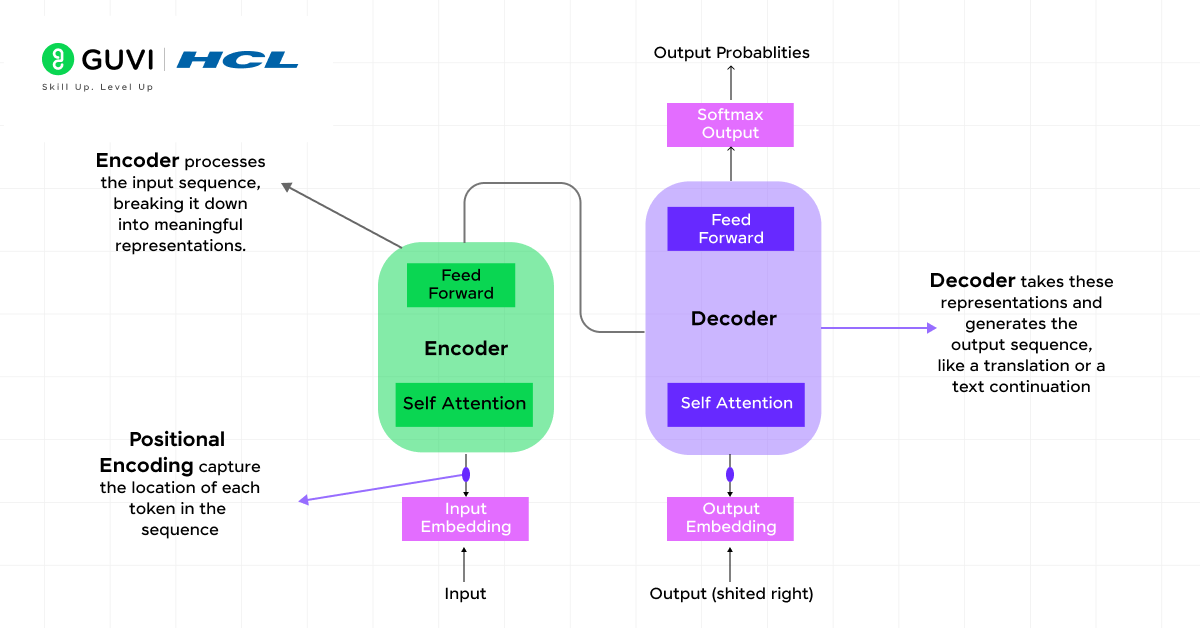
The key components of a transformer model include
- Self-attention mechanism: It helps the model focus on relevant parts of the input query.
- Encoder-decoder network: The encoder helps in analyzing the input sequence and creates a context vector, which helps the decoder to construct the output sequence.
- Multi-head attention: It allows the model to attend to different parts of a sequence from multiple perspectives.
- Positional encoding: It adds information in order of tokens to structure the output.
- What are some challenges or ethical considerations associated with LLMs?
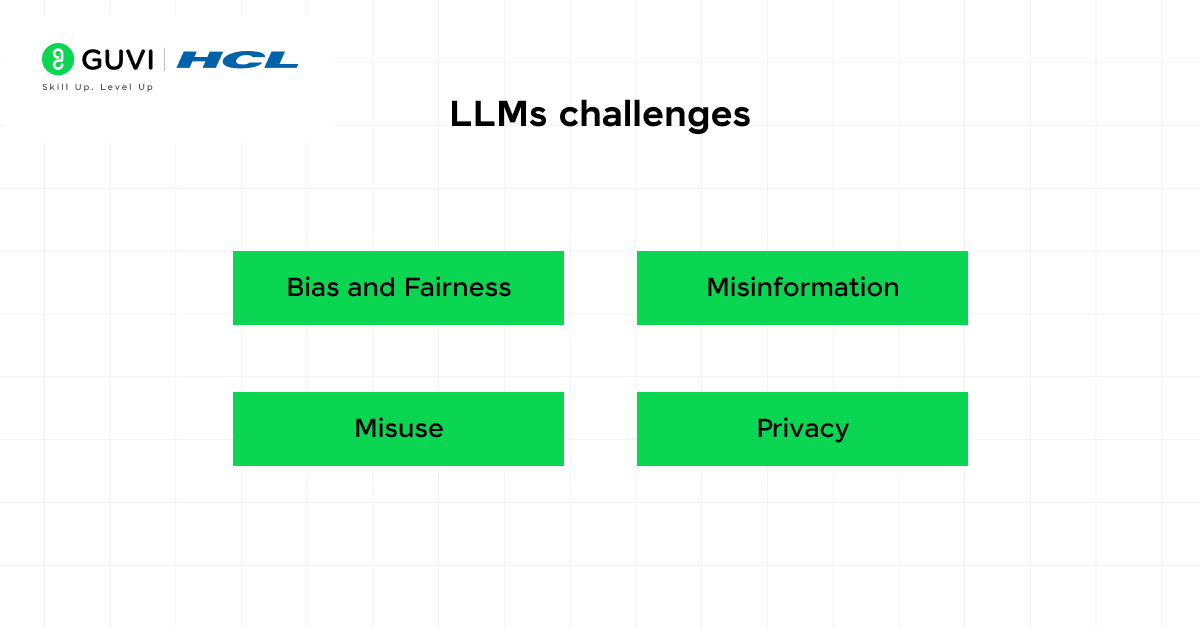
- Bias and Fairness: LLMs may inherit bias against gender or racial groups present in the training data.
- Misinformation: It may have the possibility to generate false or misleading content.
- Misuse: It may be misused for malicious purposes such as generating spam, deepfakes, or misinformation.
- Privacy: It may unintentionally memorize and output private information from training data.
- What do you know about dropouts?
Dropout is a regularization technique used to avoid overfitting of the model during the training period. With the help of the dropout technique, at each stage of training, a random set of neurons is dropped. This forces the network to learn redundant representations to improve robustness.

- What is bias and variance in deep learning models? How can you achieve a balance between the two?
Bias is an error that occurs due to overassumptions present in the model (underfitting).
Variance refers to the error from sensitivity to small fluctuations in training data (overfitting).
To achieve balance between bias and variance, we can use cross-validation techniques, regularization techniques that prevent overfitting and by using complex models to reduce bias if underfitting occurs.
- The input image has been transformed into a 28 x 28 matrix and a 7 x 7 kernel with a stride of 1. What will the convoluted matrix’s size be?
Output size formula is given as:
Where, N => input size, F => filter/kernel size, S => Stride
Given data:
N = 28
F = 7
S = 1
Apply the above formula,
The convolution is applied in both the horizontal and vertical directions, the output matrix size is = 22 x 22.
30. What is transfer learning?
Training a model from scratch for a specific task would require a huge amount of data, and it is also a tedious process. Transfer learning allows us to leverage the knowledge from a pretrained model on a large dataset and provide a new dataset on top of it to tune it for a specific task in a short period and at low cost.
Scenario-Based Interview Questions
1. You are training a neural network and notice that training accuracy keeps increasing, but validation accuracy starts dropping. What would you do?
This indicates overfitting. I would first compare the training and validation loss curves to confirm whether the gap consistently widens after a certain epoch. Then, I would check for data leakage, class imbalance, and distribution differences before changing the model.
If the data pipeline is correct, I would try dropout, L2 regularization, early stopping, data augmentation, or reducing model capacity. I would also save the best-performing checkpoint rather than using the final training epoch.
Key insight: Overfitting is not always caused by a model being too large. Poor train-validation splitting, duplicate samples, or limited data diversity can create the same pattern.
2. You are building an image classification model, but you only have a small labeled dataset. How would you approach the problem?
I would use transfer learning rather than training a CNN from scratch. I would start with a pretrained model, freeze most backbone layers, replace the classification head, and train only the new layers first.
Then, I would gradually unfreeze selected layers and fine-tune them using a lower learning rate. Data augmentation such as rotation, cropping, scaling, and brightness variation can further improve generalization.
Key insight: The closer the pretrained model’s original data domain is to the new task, the more useful its learned features are likely to be.
3. Your CNN performs well on training images but fails when users upload images under different lighting conditions. How would you improve it?
I would first confirm that lighting variation is the real source of failure by analyzing misclassified production samples. Then, I would introduce augmentations such as brightness changes, contrast adjustment, color jitter, gamma correction, and exposure variation.
I would also ensure that preprocessing during inference exactly matches training preprocessing.
Key insight: Robustness problems often come from a mismatch between training data and real-world data rather than from the CNN architecture itself.
4. You are training a deep learning model, but the loss fluctuates heavily and does not converge. What would you check first?
I would start with the learning rate because an excessively high value can cause unstable parameter updates. Then, I would inspect input normalization, optimizer configuration, batch size, weight initialization, and gradient magnitude.
If gradients are exploding, gradient clipping may help. I could also test a learning-rate scheduler or switch optimizers.
Key insight: A low loss that oscillates slightly can be normal, but large unpredictable jumps usually indicate unstable optimization or poor data scaling.
5. You are building a sentiment analysis model, but it gives different predictions for sentences that mean almost the same thing. What could be wrong?
The model may not be capturing semantic context effectively. I would inspect the embeddings and training examples to see whether the model has enough paraphrased and contextually similar sentences.
Using contextual embeddings from pretrained Transformer models can improve semantic understanding. Fine-tuning on domain-specific data can further improve consistency.
Key insight: Similar wording does not always mean identical intent. Before correcting the model, I would verify that the supposedly equivalent examples truly belong to the same label.
6. Your LSTM performs well on short sequences but loses important information in very long sequences. What would you try?
I would first check whether truncation, padding, or sequence preprocessing is already removing useful information.
If the issue is genuinely long-range dependency learning, I would consider adding attention or moving to a Transformer-based architecture. Hierarchical sequence processing may also help when inputs are extremely long.
Key insight: Replacing an LSTM with a Transformer is not automatically better. Sequence length, latency, dataset size, and memory requirements should also influence the decision.
7. You have trained a highly accurate classification model, but one important minority class is rarely detected. What would you do?
I would stop relying on accuracy and inspect the confusion matrix, recall, precision, F1-score, and class-wise metrics.
Then, I could test class weighting, oversampling, focal loss, threshold adjustment, or collecting more minority-class examples.
Key insight: Threshold tuning can sometimes improve minority-class recall without retraining the model, making it a useful first experiment.
8. Your model worked well during development but performs poorly after deployment. How would you investigate the issue?
I would compare production inputs with training and validation data to detect data drift, concept drift, or preprocessing differences.
I would also check whether features are missing, encoded differently, delayed, or corrupted in production.
Key insight: A production failure is not always a model failure. Data pipelines, feature engineering, API transformations, or version mismatches can break otherwise accurate models.
9. You are working on a real-time application, but your deep learning model is too slow for production. How would you optimize it?
I would first profile the system to identify whether the bottleneck is preprocessing, model inference, memory transfer, batching, or hardware utilization.
Depending on the result, I could apply quantization, pruning, distillation, mixed precision, optimized runtimes, batching, or architecture simplification.
Key insight: Optimization should target the actual bottleneck. Shrinking the model may have little effect if preprocessing or network latency dominates response time.
10. You have access to a large pretrained model, but your company has limited computing resources. Would you train it from scratch?
No. I would use transfer learning or fine-tuning because training from scratch would require significantly more data and compute.
Depending on the model, I could also use parameter-efficient fine-tuning techniques instead of updating all weights.
Key insight: Full fine-tuning is not always necessary. Updating a smaller subset of parameters can reduce memory and compute costs while preserving strong performance.
11. Your validation loss suddenly becomes NaN during training. How would you debug it?
I would inspect the data for NaN, infinite values, extreme outliers, and preprocessing errors.
Then, I would check the learning rate, loss calculation, gradient magnitude, numerical precision, and activation ranges.
Key insight: NaN errors often originate earlier in the pipeline than where they first appear. Logging intermediate activations and gradients can help locate the exact failure point.
12. You are comparing two deep learning models. One has slightly higher accuracy but takes three times longer to make predictions. Which one would you choose?
I would compare them using deployment requirements rather than accuracy alone.
For a real-time system, latency and throughput may matter more. For an offline diagnostic system, the more accurate model may justify additional computation.
Key insight: Model selection is a business and engineering trade-off. Accuracy, latency, memory, cost, interpretability, and failure risk should be evaluated together.
13. You are building a medical-image model where missing a positive case is more serious than generating a false alarm. Which metric would you prioritize?
I would prioritize recall because false negatives carry greater risk in this scenario.
However, I would also monitor precision because extremely low precision can overwhelm clinicians with false positives.
Key insight: The operating threshold should reflect the real cost of false positives and false negatives rather than relying only on the model’s default threshold.
14. Your Transformer model gives strong results, but training requires too much GPU memory. What would you change?
I would first reduce batch size or sequence length.
If more optimization is needed, I could use gradient accumulation, mixed precision, gradient checkpointing, smaller architectures, or more memory-efficient attention implementations.
Key insight: Sequence length can have a major effect on memory usage in attention-based models, so reducing unnecessary tokens can provide substantial savings.
15. Your manager asks you to improve a deep learning model immediately. Would you start by adding more layers?
No. I would first diagnose whether the limitation comes from data quality, model capacity, training configuration, class imbalance, labeling issues, or evaluation design.
I would inspect learning curves, error categories, metrics, feature distributions, and misclassified examples before modifying the architecture.
Key insight: Increasing complexity without diagnosis can increase cost and worsen overfitting without fixing the underlying issue.
16. Your model has excellent offline metrics, but users say its predictions are not useful. What would you investigate?
I would check whether the evaluation metric actually reflects the business objective.
For example, optimizing overall accuracy may not help if users care mainly about correctly identifying rare high-risk cases.
I would also examine how predictions are consumed in the real workflow.
Key insight: A technically strong model can still fail if the optimization target does not match the product or business goal.
17. Your model’s performance varies significantly between different user groups. What would you do?
I would evaluate performance separately across meaningful subgroups and compare metrics such as precision, recall, false-positive rate, and false-negative rate.
Then, I would investigate whether the training dataset underrepresents certain groups or contains systematic differences.
Key insight: Aggregate metrics can hide poor subgroup performance, so segmented evaluation is essential for understanding real-world reliability.
18. You improve model accuracy after adding more features, but inference becomes slower and more expensive. How would you decide whether to keep them?
I would run an ablation study to measure how much each feature contributes to performance.
If a costly feature provides only a marginal improvement, removing it may produce a better production trade-off.
Key insight: More features do not automatically mean a better system. Feature value should be measured against latency, cost, availability, and reliability.
19. Your model performs well today, but performance gradually declines over several months. What could be happening?
The underlying data distribution may be changing over time.
I would investigate data drift, concept drift, seasonal effects, new user behavior, and changes in upstream systems.
Key insight: Model monitoring should track both prediction quality and input distributions so degradation can be detected before it becomes severe.
20. You have several models with similar validation scores. How would you choose the final one?
I would compare them on additional factors such as inference latency, robustness, calibration, memory usage, interpretability, stability across folds, and deployment complexity.
I would also test them on challenging edge cases.
Key insight: When headline metrics are close, operational reliability and consistency often become more important than tiny accuracy differences.
💡 Did You Know?
- Some interviewers test your knowledge by giving a pre-trained model and asking how you would fine-tune it for a completely different task.
- Certain activation functions like Swish and GELU are gaining popularity in interviews for high-performance models over traditional ReLU.
- Transfer learning can drastically reduce training time, letting models achieve state-of-the-art results with only a fraction of the data.
How to Prepare for a Deep Learning Interview
A strong deep learning interview preparation strategy combines theory with practical implementation.
Do not stop at learning what CNN, LSTM, or Transformer stands for. Be prepared to explain:
- Why a specific architecture suits a particular dataset
- What happens during forward and backward propagation
- How loss functions and optimizers interact
- Why a model may overfit or fail to converge
- How evaluation metrics should change with the problem
- How to fine-tune pretrained models
- How to reduce inference cost
- How to diagnose failures using training and validation behavior
Interviewers may also ask you to write small pieces of Python code, calculate convolution output dimensions, interpret learning curves, or suggest changes to an existing model architecture.
What Deep Learning Topics Should Freshers Prioritize?
Freshers should first build a strong understanding of:
- ANN architecture
- Weights and biases
- Activation functions
- Forward and backward propagation
- Loss functions
- Gradient descent
- CNN fundamentals
- RNN and LSTM basics
- Overfitting and regularization
- Model evaluation
What Should Experienced Candidates Prepare Differently?
Experienced candidates are more likely to receive questions about decisions rather than definitions.
They should be prepared to discuss:
- Architecture selection
- Model trade-offs
- Production constraints
- Training instability
- Experiment design
- Data leakage
- Domain shift
- Latency and throughput
- Fine-tuning strategies
- Quantization and distillation
- Deployment limitations
- Monitoring model performance after deployment
What Do Interviewers Look for in Deep Learning Candidates?
Interviewers usually look beyond theoretical definitions. They want to see whether a candidate can connect deep learning concepts with practical model decisions.
A strong candidate should be able to:
- Explain why a particular architecture fits a problem
- Justify the choice of loss function and evaluation metrics
- Diagnose overfitting, unstable training, and poor generalization
- Compare alternative models based on accuracy, latency, and compute cost
- Explain how preprocessing affects model performance
- Handle class imbalance, data drift, and domain shift
- Discuss deployment constraints such as GPU memory and inference speed
- Explain previous projects using clear technical reasoning
How Should You Answer Deep Learning Scenario Questions in an Interview?
A good scenario-based answer should follow a structured diagnostic approach instead of jumping directly to a solution.
Start by identifying the likely problem. Then explain how you would verify it using metrics, learning curves, logs, or error analysis. After confirming the cause, suggest one or more technical solutions and explain why they are suitable.
A useful answering framework is:
- Identify the issue: Determine whether the problem involves data, training, architecture, or deployment.
- Validate the assumption: Check metrics, distributions, gradients, predictions, or system logs.
- Suggest solutions: Recommend techniques that directly address the identified problem.
- Explain trade-offs: Mention effects on accuracy, latency, memory, cost, or complexity.
- Measure the result: Explain how you would verify that the change actually improved the model.
This approach shows that you can troubleshoot deep learning systems systematically rather than relying on memorized fixes.
Conclusion
Deep learning interviews require both conceptual understanding and the ability to reason through model behavior. Fundamentals such as neural networks, activation functions, loss functions, backpropagation, CNNs, RNNs, and regularization provide the foundation. Intermediate concepts such as transfer learning, fine-tuning, optimization, and model evaluation show whether you can train models effectively.
Advanced interviews go further into Transformers, attention, architecture selection, domain shift, computational efficiency, and real-world troubleshooting. These questions test whether you can connect model theory with practical engineering decisions.
Use these 50 Deep Learning interview questions progressively. Master the beginner concepts first, strengthen your understanding through intermediate architecture and training questions, and then practise advanced scenarios where there may be several possible solutions. That approach will help you explain not only what a deep learning technique does, but also when, why, and how to use it.
FAQs
1. How should I prepare for a deep learning interview?
Start with core concepts such as neural networks, activation functions, loss functions, backpropagation, CNNs, RNNs, LSTMs, and Transformers. Then revise model evaluation, regularization, transfer learning, and optimization. Practise explaining each concept in simple terms and prepare examples from your own projects.
2. What is the best way to answer deep learning interview questions?
Use a structured approach. First define the concept briefly, then explain how it works, where it is used, and mention one practical example. For scenario-based questions, identify the issue, explain how you would verify it, and then suggest the most relevant solution.
3. What are some quick tips to perform better in a deep learning interview?
Focus on understanding instead of memorizing answers. Revise common architectures, know important metrics, practise explaining model trade-offs, and review your past projects thoroughly. If you do not know an answer, explain how you would approach or investigate the problem instead of guessing.
4. How can I handle scenario-based deep learning questions confidently?
Break the scenario into four parts: identify the likely problem, check the evidence, suggest technical solutions, and explain trade-offs. For example, if a model is overfitting, first confirm it through training and validation curves before suggesting dropout, regularization, or early stopping.
5. What mistakes should I avoid in a deep learning interview?
Avoid giving only textbook definitions, using accuracy as the only evaluation metric, suggesting complex models without justification, and ignoring data quality or deployment constraints. Also avoid claiming a technique will always work. Strong answers explain when and why a method is suitable.
Success Stories

About the Author
Vaishali
I'm a seasoned writer with four years of experience across technical, non-technical, and just about every genre or niche you can imagine. Adaptable and curious, I enjoy exploring new topics and making information engaging and easy to understand. Fueled by a steady stream of tea, I approach each project with creativity, reliability, and genuine enthusiasm for storytelling.
View all posts by Vaishali
Connect with me @

Did you enjoy this article?
Comments








It's very helpfull to my interviews