


Data Science Articles
Will Moving From Team Lead to Data Analyst Reduce Salary or Seniority?
Will Switching From Operations Manager to Data Science Increase Salary?
Get In Touch For Details! Request More Information

What is Data Mining? A Beginner’s Guide
Oct 01, 2026 9 Min Read 18059 Views
(Last Updated)
Every business collects data, but raw data becomes valuable only when useful patterns can be extracted from it. Data mining combines statistics, machine learning, and database techniques to identify relationships, anomalies, customer behavior, trends, and predictive signals hidden inside large datasets.
From fraud detection and recommendation systems to predictive maintenance and customer segmentation, data mining supports decisions across finance, healthcare, retail, manufacturing, education, and government. This guide explains how data mining works, the major techniques and algorithms involved, its step-by-step process, real-world applications, challenges, and emerging trends shaping the field.
Table of contents
- Quick Answer
- What is Data Mining?
- What is Data Mining? A Beginner's Guide
- Techniques and Methods
- Process of Data Mining
- Applications of Data Mining
- Challenges and Considerations
- Future Trends in Data Mining
- a) Automated Machine Learning (AutoML)
- b) Edge Computing and IoT Analytics
- c) Explainable AI (XAI)
- d) Federated Learning
- e) Graph Mining and Network Analysis
- f) Quantum Computing for Data Mining
- g) Reinforcement Learning in Data Mining
- h) Privacy-Preserving Data Mining
- i) Integration of Structured and Unstructured Data
- j) Ethical AI and Responsible Data Mining
- How Do You Choose the Right Data Mining Technique?
- What Skills and Tools Are Needed for Data Mining?
- How Do You Evaluate Whether a Data Mining Project Is Successful?
- Conclusion
- FAQs
- What is data mining in simple terms?
- What are the main techniques used in data mining?
- What is the difference between data mining and machine learning?
- Where is data mining used in real life?
- What skills are required to learn data mining?
Quick Answer
Data mining extracts useful patterns, relationships, and predictions from large datasets using statistical and machine learning techniques.
- Classification: Assigns data to predefined categories.
- Clustering: Groups similar records without predefined labels.
- Association Rules: Finds relationships between items or events.
- Regression: Predicts continuous numerical outcomes.
- Anomaly Detection: Identifies unusual or suspicious patterns.
- Dimensionality Reduction: Reduces features while preserving useful information.
What is Data Mining?
Data mining is the process of discovering patterns, trends, and useful information from large datasets. It involves using various techniques and algorithms to extract knowledge that can be used for decision-making, prediction, and problem-solving. Key aspects of data mining include:
- Pattern recognition: Identifying recurring structures or relationships within data.
- Classification: Categorizing data into predefined groups or classes.
- Clustering: Grouping similar data points together without predefined categories.
- Association rule learning: Discovering relationships between variables in large databases.
- Anomaly detection: Identifying unusual or rare events in datasets.
- Predictive modeling: Using historical data to forecast future trends or outcomes.
- Feature selection: Identifying the most relevant variables for analysis.
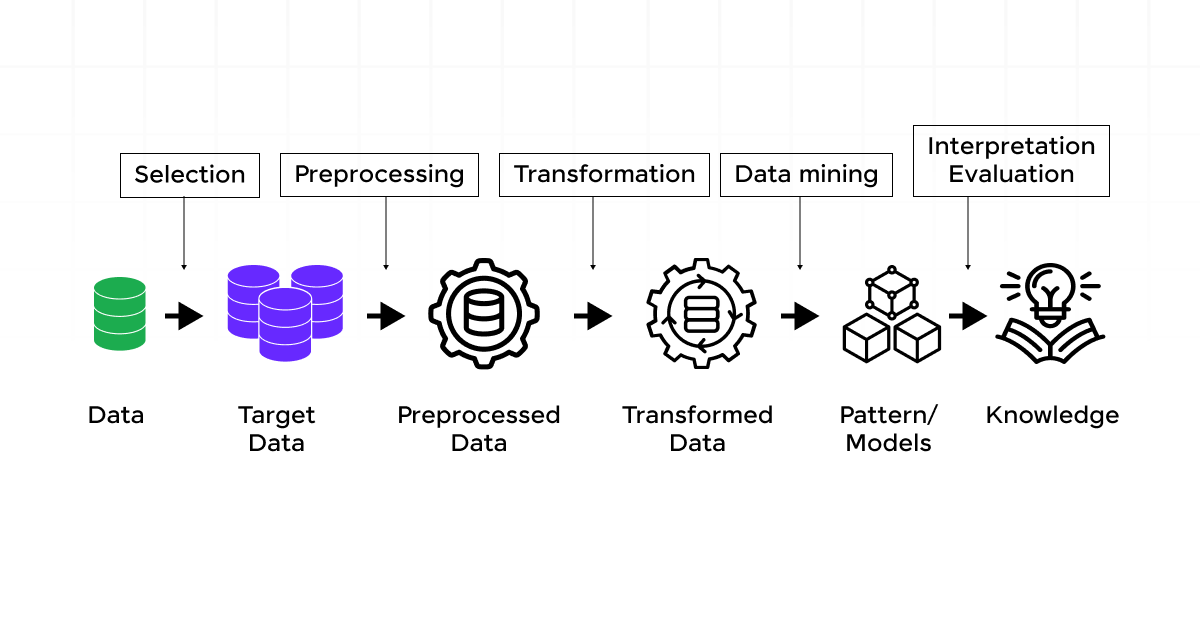
Data mining applies techniques from statistics, machine learning, and database systems to analyze large volumes of structured and unstructured data. It’s used across various industries, including finance, healthcare, marketing, and scientific research, to gain insights and support data-driven decision-making.
Now that we’ve covered what data mining is, let’s explore the beginner’s guide for 2026, exploring the key steps, techniques, and tools.
What is Data Mining? A Beginner’s Guide
Let’s explore the fundamentals of data mining, its techniques and methods, the process involved, its applications, challenges, and future trends.
Techniques and Methods
Data mining uses various techniques and methods to extract meaningful information from datasets. Here are some of the most common and powerful approaches:
a) Classification
Classification is a supervised learning technique that categorizes data into predefined classes or groups. It’s widely used in various applications, such as spam email detection, customer segmentation, and medical diagnosis. Popular classification algorithms include:
- Decision Trees: These create a tree-like model of decisions based on feature values.
- Random Forests: An ensemble method that combines multiple decision trees for improved accuracy.
- Support Vector Machines (SVM): These find the optimal hyperplane to separate different classes in high-dimensional space.
- Naive Bayes: A probabilistic classifier based on Bayes’ theorem.
- Neural Networks: Deep learning models that can learn complex patterns in data.
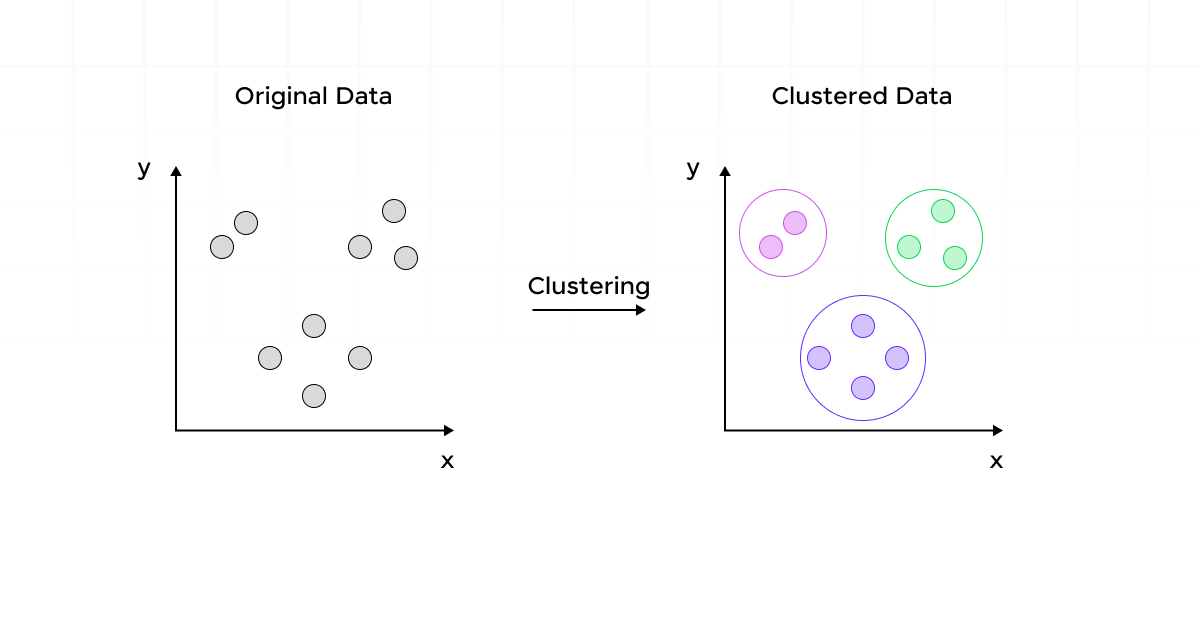
b) Clustering
Clustering is an unsupervised learning technique that groups similar data points together without predefined categories. It’s useful for customer segmentation, anomaly detection, and pattern recognition. Common clustering algorithms include:
- K-Means: Partitions data into K clusters based on the nearest mean.
- Hierarchical Clustering: Creates a tree of clusters, either by agglomerative (bottom-up) or divisive (top-down) approaches.
- DBSCAN (Density-Based Spatial Clustering of Applications with Noise): Groups together points that are closely packed together in areas of high density.
c) Association Rule Learning
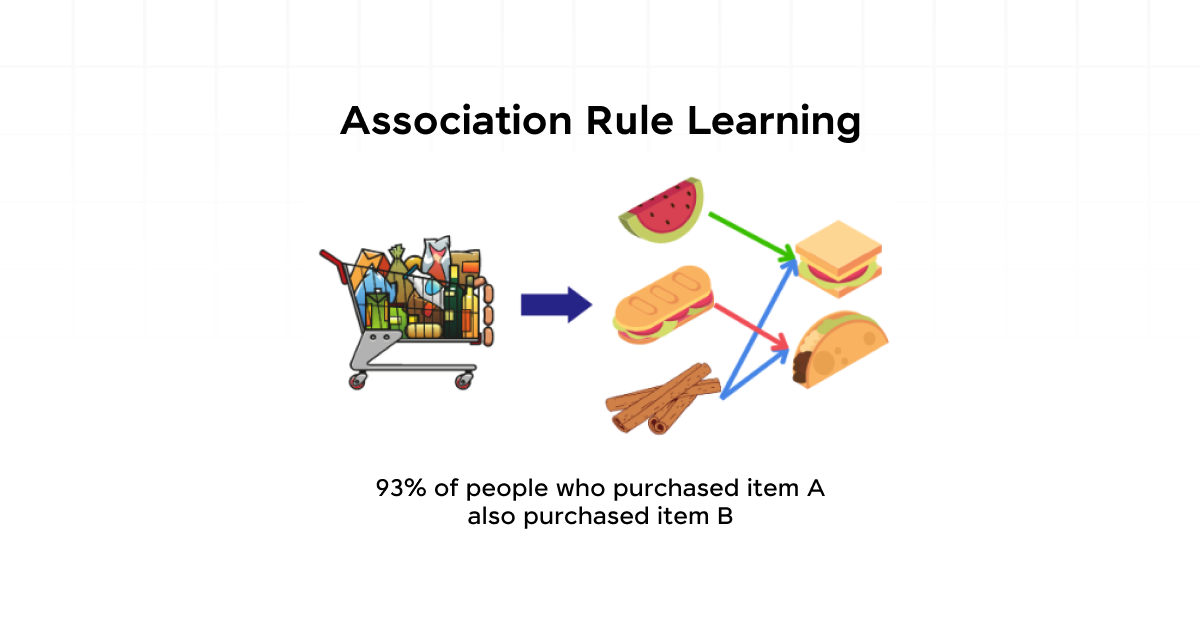
This technique identifies relationships between variables in large databases. It’s commonly used in market basket analysis to understand purchasing patterns. Popular algorithms include:
- Apriori Algorithm: Identifies frequent item sets and generates association rules.
- FP-Growth (Frequent Pattern Growth): An efficient method for mining frequent item sets without candidate generation.
d) Regression Analysis
Regression is used to predict continuous values based on input variables. It’s essential for forecasting and understanding relationships between variables. Common regression techniques include:
- Linear Regression: Models the relationship between variables using a linear equation.
- Polynomial Regression: Fits a nonlinear relationship using polynomial functions.
- Logistic Regression: Despite its name, it’s used for binary classification problems.
e) Anomaly Detection
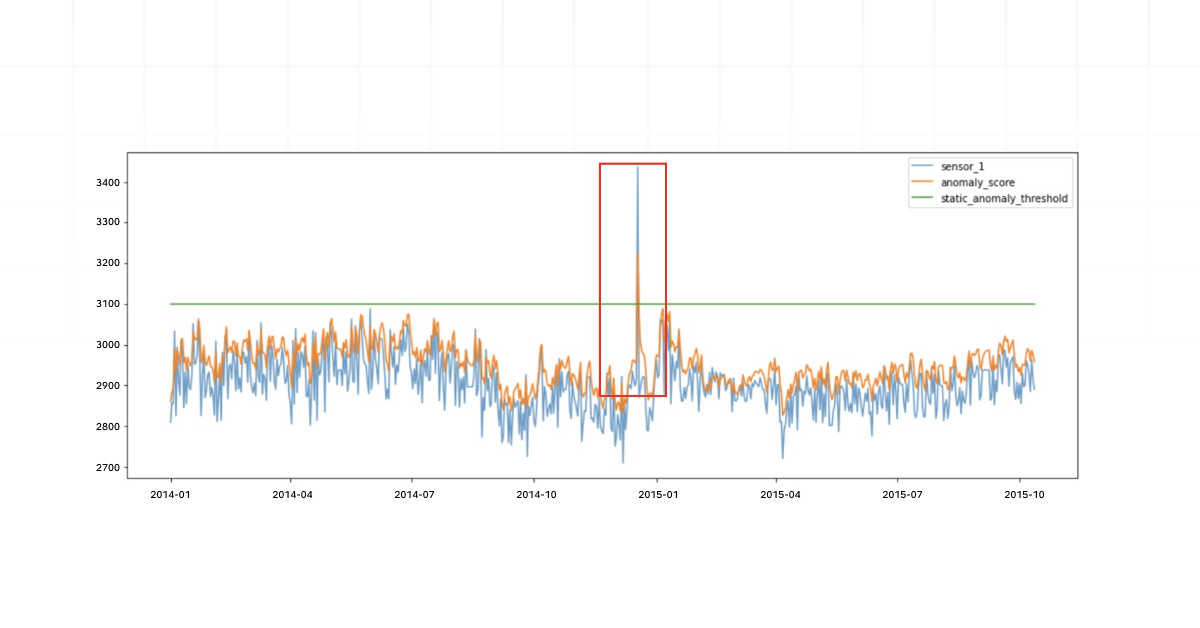
This technique identifies rare items, events, or observations that differ significantly from the majority of the data. It’s important for fraud detection, system health monitoring, and medical diagnosis. Methods include:
- Isolation Forest: Isolates anomalies by randomly selecting a feature and then randomly selecting a split value.
- One-Class SVM: Learns a decision boundary that encompasses the normal instances.
- Autoencoders: Neural networks that can detect anomalies by comparing reconstruction errors.
f) Dimensionality Reduction
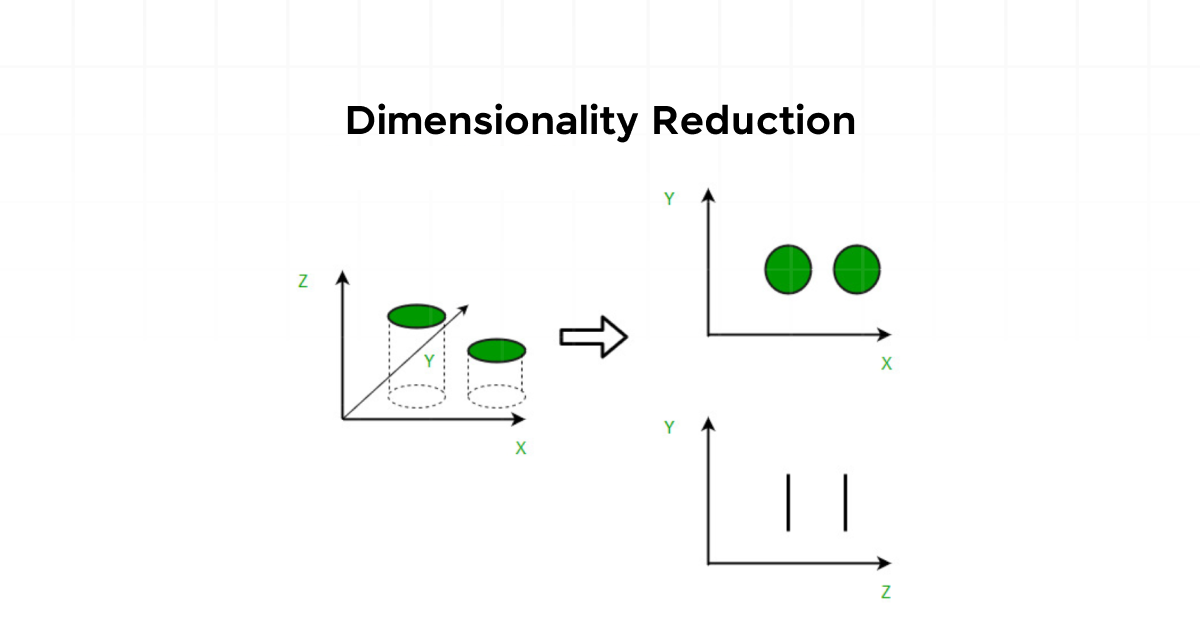
These techniques reduce the number of features in a dataset while retaining most of the important information. They’re useful for visualization and improving model performance. Common methods include:
- Principal Component Analysis (PCA): Transforms the data into a new coordinate system where the variables are uncorrelated.
- t-SNE (t-Distributed Stochastic Neighbor Embedding): Visualizes high-dimensional data in two or three dimensions.
- Autoencoders: Can be used to learn compressed representations of data.
Process of Data Mining
The data mining process typically follows a structured approach to ensure thorough analysis and meaningful results. Here’s a breakdown of the key steps:
a) Problem Definition
The first step is to clearly define the business problem or question that data mining will address. This involves understanding the objectives, scope, and expected outcomes of the analysis.
b) Data Collection
Gathering relevant data from various sources is important. This may involve accessing databases, web scraping, or collecting data through surveys or sensors. Ensure that the data collected is comprehensive and representative of the problem at hand.
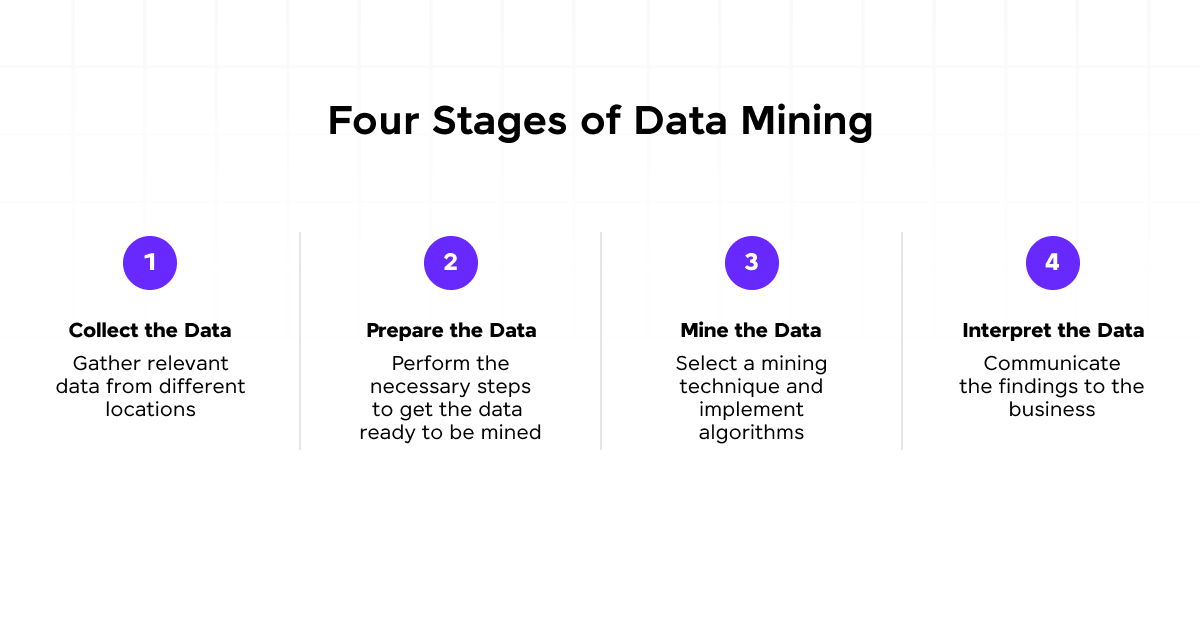
c) Data Preprocessing
Raw data often contains inconsistencies, missing values, and noise. Preprocessing involves:
- Data cleaning: Handling missing values, removing duplicates, and correcting errors.
- Data integration: Combining data from multiple sources.
- Data transformation: Normalizing or scaling data to ensure consistency.
- Data reduction: Selecting relevant features or using dimensionality reduction techniques.
d) Exploratory Data Analysis (EDA)
Before applying complex algorithms, it’s essential to understand the data’s characteristics. EDA involves:
- Visualizing data distributions and relationships.
- Identifying patterns, trends, and outliers.
- Generating hypotheses for further investigation.
Also Read: Data Science vs Data Analytics | Best Career Choice in 2026
e) Model Selection and Training
Based on the problem and data characteristics, select appropriate data mining techniques. This step involves:
- Choosing suitable algorithms.
- Splitting the data into training and testing sets.
- Training the model on the training data.
- Tuning hyperparameters to optimize performance.
f) Model Evaluation
Assess the model’s performance using various metrics, depending on the problem type:
- Classification: Accuracy, precision, recall, F1-score, ROC curve.
- Regression: Mean Squared Error (MSE), R-squared, Mean Absolute Error (MAE).
- Clustering: Silhouette score, Calinski-Harabasz index.
g) Knowledge Interpretation and Presentation
Transform the model’s output into actionable insights. This involves:
- Interpreting the results in the context of the business problem.
- Visualizing the findings for easy understanding.
- Preparing reports or dashboards to communicate results to stakeholders.
h) Deployment and Monitoring
Implement the model in a production environment and continuously monitor its performance. This may involve:
- Integrating the model with existing systems.
- Setting up automated data pipelines.
- Regularly retraining the model with new data.
- Monitoring for concept drift or changes in data distribution.
Applications of Data Mining
Data mining has found applications across various industries, revolutionizing decision-making processes and uncovering valuable insights. Here are some key areas where data mining is making a significant impact:
a) Business and Marketing
- Customer Segmentation: Grouping customers based on behavior, preferences, and demographics to tailor marketing strategies.
- Market Basket Analysis: Identifying products frequently purchased together to optimize store layouts and promotional offers.
- Churn Prediction: Predicting which customers are likely to leave and developing retention strategies.
- Sentiment Analysis: Analyzing customer feedback and social media data to gauge product reception and brand perception.
b) Finance and Banking
- Credit Scoring: Assessing the creditworthiness of loan applicants based on historical data.
- Fraud Detection: Identifying unusual patterns in transactions to prevent financial fraud.
- Risk Management: Analyzing market trends and customer behavior to mitigate financial risks.
- Stock Market Prediction: Using historical data and news sentiment to forecast market trends.
c) Healthcare and Medicine
- Disease Prediction: Analyzing patient data to predict the likelihood of developing certain conditions.
- Drug Discovery: Identifying potential drug candidates by analyzing molecular structures and biological interactions.
- Treatment Optimization: Recommending personalized treatment plans based on patient characteristics and historical outcomes.
- Medical Image Analysis: Detecting anomalies in X-rays, MRIs, and other medical imaging data.
d) E-commerce and Retail
- Recommendation Systems: Suggesting products to customers based on their browsing and purchase history.
- Inventory Management: Predicting demand and optimizing stock levels across different locations.
- Price Optimization: Dynamically adjusting prices based on demand, competition, and other factors.
- Customer Lifetime Value Prediction: Estimating the long-term value of customers to prioritize retention efforts.
e) Manufacturing and Supply Chain
- Predictive Maintenance: Forecasting equipment failures to schedule maintenance and reduce downtime.
- Quality Control: Identifying factors that contribute to product defects.
- Supply Chain Optimization: Analyzing historical data to improve inventory management and logistics.
f) Education
- Student Performance Prediction: Identifying at-risk students and factors influencing academic success.
- Personalized Learning: Tailoring educational content based on individual student’s learning patterns.
- Course Recommendation: Suggesting courses to students based on their interests and career goals.
g) Government and Public Sector
- Fraud Detection: Identifying potential cases of tax evasion or benefit fraud.
- Crime Prevention: Analyzing crime patterns to optimize law enforcement resource allocation.
- Urban Planning: Using demographic and geospatial data to improve city infrastructure and services.
Challenges and Considerations
While data mining offers tremendous potential, it also comes with several challenges and ethical considerations that organizations must address:
a) Data Quality and Consistency
- Ensuring data accuracy, completeness, and consistency across various sources.
- Handling missing values and outliers without introducing bias.
- Maintaining data quality over time as new data is collected.
b) Privacy and Security
- Protecting sensitive personal information and ensuring compliance with data protection regulations (e.g., GDPR, CCPA).
- Implementing robust security measures to prevent data breaches.
- Balancing data utility with privacy preservation through techniques like anonymization and differential privacy.
c) Ethical Considerations
- Avoiding bias and discrimination in data mining models, especially in sensitive areas like hiring or lending.
- Ensuring transparency and explainability of model decisions, particularly in high-stakes applications.
- Considering the societal impact of data mining applications and potential unintended consequences.
d) Scalability and Performance
- Handling increasingly large and complex datasets efficiently.
- Optimizing algorithms and infrastructure to process data in real-time or near-real-time.
- Balancing model complexity with computational resources and time constraints.
e) Interpretability vs. Performance
- Striking a balance between model accuracy and interpretability, especially in regulated industries.
- Developing techniques to explain complex models like deep neural networks.
- Communicating model insights effectively to non-technical stakeholders.
f) Data Integration
- Combining data from diverse sources with different formats and structures.
- Resolving conflicts and inconsistencies when merging data from multiple systems.
- Ensuring data lineage and traceability throughout the integration process.
g) Skill Gap and Training
- Addressing the shortage of skilled data scientists and analysts.
- Providing ongoing training to keep up with rapidly evolving techniques and data science tools.
- Fostering collaboration between domain experts and data scientists for effective problem-solving.
Future Trends in Data Mining
As data volumes grow and analytics moves closer to real-time decision-making, data mining is increasingly integrating with automation, distributed computing, privacy engineering, graph analytics, and multimodal AI. The following technologies are shaping how future data mining systems collect, process, model, and govern information.
a) Automated Machine Learning (AutoML)
AutoML is moving beyond basic model selection toward automating larger parts of the data mining pipeline.
Key developments include:
- Automated Feature Engineering: Generates and selects useful variables from raw datasets.
- Model Selection: Compares multiple algorithms against defined performance metrics.
- Hyperparameter Optimization: Uses techniques such as Bayesian optimization or successive halving to tune model parameters.
- Pipeline Automation: Automates preprocessing, training, validation, and model comparison.
- Model Monitoring: Tracks drift, degradation, and retraining requirements after deployment.
This reduces repetitive experimentation while allowing data scientists to focus more on problem definition, data quality, and model interpretation.

b) Edge Computing and IoT Analytics
Data mining is increasingly moving from centralized cloud platforms to edge devices, where data can be processed closer to its source.
This is particularly important when applications require:
- Low Latency: Decisions must happen within milliseconds.
- Reduced Bandwidth: Raw sensor data does not need to be continuously transmitted to the cloud.
- Offline Operation: Devices can continue processing when connectivity is limited.
- Real-Time Anomaly Detection: Equipment failures or security events can be detected immediately.
- Local Data Processing: Sensitive information can remain on the device.
Edge mining is becoming increasingly relevant in industrial IoT, autonomous systems, healthcare monitoring, smart infrastructure, and connected manufacturing.
c) Explainable AI (XAI)
As data mining models become more complex, organizations need mechanisms to understand why a model produced a specific prediction or classification.
Explainable AI techniques may include:
- Feature Importance: Identifying variables that contribute most to predictions.
- SHAP Values: Measuring how individual features influence specific model outputs.
- LIME: Building simpler local models around individual predictions.
- Partial Dependence Analysis: Showing how changes in a feature affect predicted outcomes.
- Counterfactual Explanations: Identifying what would need to change for a different prediction.
XAI becomes especially important in finance, healthcare, insurance, hiring, and other high-impact domains where decisions need to be reviewed, justified, or audited.
d) Federated Learning
Federated learning enables machine learning models to learn from distributed data without requiring all raw information to be collected in one central repository.
A typical workflow involves:
- Sending a global model to participating devices or organizations.
- Training the model locally on each participant’s private dataset.
- Sending model updates rather than raw records to a coordinating server.
- Aggregating those updates into an improved global model.
This architecture can reduce centralized data exposure and is useful in healthcare, mobile devices, financial institutions, and cross-organization analytics.
However, federated learning still requires controls against risks such as model poisoning, information leakage, unreliable participants, and communication overhead.
Also Read: Data Science vs. Machine Learning: What Every Elite Coder Needs to Know
e) Graph Mining and Network Analysis
Traditional tables are not always ideal for representing highly connected data. Graph mining models entities as nodes and their relationships as edges, making it easier to analyze complex networks.
Important techniques include:
- Community Detection: Identifying tightly connected groups.
- Centrality Analysis: Finding influential or important nodes.
- Link Prediction: Predicting relationships that may form in the future.
- Graph Embeddings: Converting graph structures into numerical representations.
- Graph Neural Networks: Learning directly from interconnected data.
Applications include fraud-ring detection, recommendation systems, social networks, cybersecurity, supply chains, knowledge graphs, and biological networks.
f) Quantum Computing for Data Mining
Quantum computing remains an emerging research area, but it is being explored for computationally difficult data mining tasks involving optimization, search, and high-dimensional data.
Potential areas include:
- Quantum Optimization: Exploring difficult combinatorial search spaces.
- Quantum Clustering: Investigating alternative approaches to grouping complex datasets.
- Feature Selection: Searching large combinations of candidate variables.
- Similarity Search: Exploring quantum approaches for comparing high-dimensional data.
- Hybrid Quantum-Classical Models: Combining conventional machine learning pipelines with quantum subroutines.
Its practical impact on mainstream data mining is still developing, and current approaches remain constrained by hardware scale, noise, algorithm maturity, and integration complexity.
g) Reinforcement Learning in Data Mining
Reinforcement learning extends data mining from passive pattern discovery to systems that continuously learn which actions produce better outcomes.
An RL system typically learns through:
- State: Current condition of the environment.
- Action: Decision taken by the system.
- Reward: Feedback indicating whether the action was beneficial.
- Policy: Strategy used to select future actions.
This makes reinforcement learning useful for dynamic pricing, recommendation systems, resource allocation, adaptive experimentation, robotics, and personalized customer experiences where decisions must continuously adapt to new feedback.
h) Privacy-Preserving Data Mining
Organizations increasingly need to extract insights from sensitive datasets without unnecessarily exposing individual records.
Important techniques include:
- Differential Privacy: Adds controlled statistical noise to reduce the ability to identify individuals.
- Homomorphic Encryption: Enables certain computations on encrypted data.
- Secure Multi-Party Computation: Allows multiple organizations to jointly compute results without revealing their private inputs.
- Federated Analytics: Computes aggregated insights while data remains distributed.
- Data Masking and Tokenization: Replaces sensitive values with protected representations.
Privacy-preserving data mining is especially relevant to healthcare, banking, insurance, telecommunications, and government datasets.
i) Integration of Structured and Unstructured Data
Future data mining systems increasingly need to analyze structured tables alongside text, images, audio, video, documents, and event streams.
Modern pipelines may combine:
- Transaction records from relational databases
- Customer-support conversations
- PDFs and business documents
- Product images
- Call transcripts
- Sensor streams
- Clickstream and event data
Techniques such as embeddings, vector databases, multimodal models, entity extraction, and knowledge graphs can connect these data types into richer analytical representations.
This makes it possible to uncover relationships that would remain hidden if structured and unstructured data were analyzed separately.
j) Ethical AI and Responsible Data Mining
As data mining increasingly influences automated decisions, organizations need stronger controls over how models are built, evaluated, and monitored.
Responsible data mining increasingly focuses on:
- Bias Detection: Measuring whether outcomes disproportionately affect specific groups.
- Data Lineage: Tracking where data originated and how it was transformed.
- Model Governance: Documenting ownership, purpose, validation, and approval.
- Explainability: Providing understandable reasons for model decisions.
- Auditability: Maintaining evidence of model development and decision processes.
- Drift Monitoring: Detecting changes in data or model behavior after deployment.
- Human Oversight: Keeping appropriate review around high-impact automated decisions.
Organizations will increasingly need to evaluate both the performance and governance of data mining tools so that automated insights remain accurate, traceable, secure, and appropriate for their intended use.
Kickstart your Data Science journey by enrolling in HCL GUVI’s Data Science Course where you will master technologies like MongoDB, Tableau, PowerBI, Pandas, etc., and explore some interesting real-world data science examples. Alternatively, if you would like to explore Python through a Self-paced course, try HCL GUVI’s Python certification course.
How Do You Choose the Right Data Mining Technique?
The right data mining technique depends on the business question, type of target variable, available labels, and expected output.
| Goal | Suitable Technique | Example |
|---|---|---|
| Predict a category | Classification | Spam vs legitimate email |
| Discover natural groups | Clustering | Customer segmentation |
| Find item relationships | Association Rules | Market basket analysis |
| Predict a number | Regression | Sales forecasting |
| Detect unusual behavior | Anomaly Detection | Credit card fraud |
| Reduce many features | Dimensionality Reduction | High-dimensional visualization |
A supervised method such as classification or regression works when labeled historical data is available. Unsupervised techniques such as clustering are more appropriate when the goal is to discover hidden structures without predefined outcomes.
What Skills and Tools Are Needed for Data Mining?
Effective data mining requires more than knowing one algorithm. Practitioners need to work across data preparation, analysis, modeling, evaluation, and communication.
Key skills include:
- Python: Data manipulation, automation, and model development.
- SQL: Extracting and transforming data stored in relational databases.
- Pandas and NumPy: Cleaning and manipulating structured datasets.
- Statistics: Understanding distributions, correlations, sampling, and model uncertainty.
- Machine Learning: Selecting, training, and evaluating predictive models.
- Data Visualization: Communicating patterns using Tableau, Power BI, or Python libraries.
- Database Knowledge: Working with relational, NoSQL, and large-scale data systems.
- Business Understanding: Connecting model outputs to practical decisions and measurable outcomes.
Strong data mining work combines technical modeling with the ability to determine whether the discovered pattern is actually useful for the underlying problem.
How Do You Evaluate Whether a Data Mining Project Is Successful?
A technically accurate model is not automatically a successful data mining project. Evaluation should consider both model performance and business value.
For classification tasks, teams may measure precision, recall, F1-score, ROC-AUC, or accuracy. Regression projects commonly use metrics such as MAE, MSE, RMSE, or R-squared, while clustering can be evaluated using measures such as silhouette score.
Business evaluation should also ask:
- Did the model improve the intended decision?
- Are predictions reliable on unseen data?
- Does the model remain accurate as data changes?
- Is the result understandable enough for stakeholders?
- Does implementation reduce cost, risk, or manual effort?
- Can the model operate within required latency and infrastructure limits?
A strong data mining solution therefore balances statistical performance, interpretability, scalability, and measurable business impact.
Conclusion
Data mining turns large, complex datasets into patterns that organizations can use for prediction, segmentation, risk detection, optimization, and strategic decision-making. Its value comes not from one algorithm, but from combining appropriate techniques with clean data, meaningful evaluation, and clear business objectives.
As data sources become larger and more diverse, data mining is increasingly intersecting with machine learning, AutoML, edge analytics, graph analysis, privacy-preserving methods, and explainable AI. Building strong foundations in Python, SQL, statistics, databases, and model evaluation gives learners the skills needed to work effectively with these evolving approaches.
For learners who want to build these capabilities practically, HCL GUVI’s Data Science Course can help strengthen skills across tools such as MongoDB, Tableau, Power BI, Pandas, and other technologies used throughout modern data workflows.
FAQs
1. What is data mining in simple terms?
Data mining is the process of analyzing large datasets to discover useful patterns, relationships, trends, anomalies, and predictive signals. It combines techniques from statistics, machine learning, and database systems to support better decision-making.
2. What are the main techniques used in data mining?
The major data mining techniques include classification, clustering, association rule learning, regression, anomaly detection, and dimensionality reduction. Each technique solves a different type of analytical problem, from predicting outcomes to discovering hidden groups or unusual behavior.
3. What is the difference between data mining and machine learning?
Data mining focuses on discovering useful patterns and knowledge from datasets, while machine learning focuses more specifically on building models that learn from data to make predictions or decisions. In practice, data mining often uses machine learning algorithms as part of the broader analysis process.
4. Where is data mining used in real life?
Data mining is used in finance, healthcare, retail, e-commerce, manufacturing, education, and government. Common applications include fraud detection, customer segmentation, recommendation systems, predictive maintenance, credit scoring, disease prediction, and demand forecasting.
5. What skills are required to learn data mining?
Useful data mining skills include Python, SQL, statistics, machine learning, data preprocessing, database knowledge, visualization, and model evaluation. Learners should also understand how to clean data, select suitable algorithms, interpret results, and communicate insights clearly.
Success Stories

About the Author
Vaishali
I'm a seasoned writer with four years of experience across technical, non-technical, and just about every genre or niche you can imagine. Adaptable and curious, I enjoy exploring new topics and making information engaging and easy to understand. Fueled by a steady stream of tea, I approach each project with creativity, reliability, and genuine enthusiasm for storytelling.
View all posts by Vaishali
Connect with me @







Did you enjoy this article?