


Interview Articles
InfyTQ Interview Experience 2026: Process, Questions, Preparation & Tips
Deloitte NLA Interview Experience 2026: Rounds, Questions and Preparation - Best Guide
Capgemini Exceller Interview Questions 2026: Coding, Technical, HR, and AI Prep - Best Guide
Wipro Elite NTH Interview Experience 2026: What Candidates Say
Get In Touch For Details! Request More Information
Top 40 Data Science Interview Questions
Oct 05, 2026 5 Min Read 14658 Views
(Last Updated)
Preparing for a data science interview can be challenging, especially when you are unsure what topics interviewers may focus on. Most interviews cover Python, SQL, statistics, machine learning, data cleaning, and practical problem-solving.
Whether you are a fresher or an experienced professional, preparation should go beyond memorizing definitions. Interviewers often want to know how you apply your knowledge to real-world data problems.
This list covers 40 commonly asked data science interview questions, from basic concepts to experienced-level scenarios, so you can revise important topics before your interview.
Table of contents
- TL;DR
- Steps to Prepare for an Interview
- Brush Up Your Basic Skills
- Understand the Job Description
- Attend Mock Interviews
- Top 40 Data Science Interview Questions With Answers
- Basic Data Science Interview Questions
- Machine Learning and Statistics Questions
- Programming and Tools-Based Questions
- Experienced-Level Data Science Interview Questions
- Your model's accuracy suddenly drops overnight. What would you investigate?
- Explain a machine learning model to a 5-year-old.
- Your dataset has 98% Class A and 2% Class B. The model has 98% accuracy. Why could this be misleading?
- You can choose only one metric for a binary classification problem. Which would you choose?
- Your manager asks you to use deep learning. How would you decide whether it is appropriate?
- Your model has high variance. What would you do?
- How would you reduce model training time by 10×?
- Your clustering algorithm produces meaningless clusters. What could be wrong?
- How would you explain feature importance to a non-technical person?
- If you could ask only one question before modeling a dataset, what would you ask?
- Start Your Learning Journey with HCL GUVI.
- Conclusion
- FAQs
- What topics are commonly asked in a data science interview?
- Are data science interviews different for experienced candidates?
- How should I prepare for a data science interview?
- Is Python important for data science interviews?
- What should I do if I don't know an interview answer?
TL;DR
- Data science interviews commonly cover Python, SQL, statistics, machine learning, data analysis, and model evaluation.
- Revise important concepts such as supervised vs. unsupervised learning, feature engineering, overfitting, evaluation metrics, and probability.
- Practice Python and SQL coding questions along with data cleaning, EDA, and machine learning problems.
- Experienced candidates should prepare for real-world scenarios involving model performance, data drift, imbalanced datasets, and business requirements.
- Mock interviews can help you practice technical explanations, identify knowledge gaps, and improve interview confidence.
Steps to Prepare for an Interview
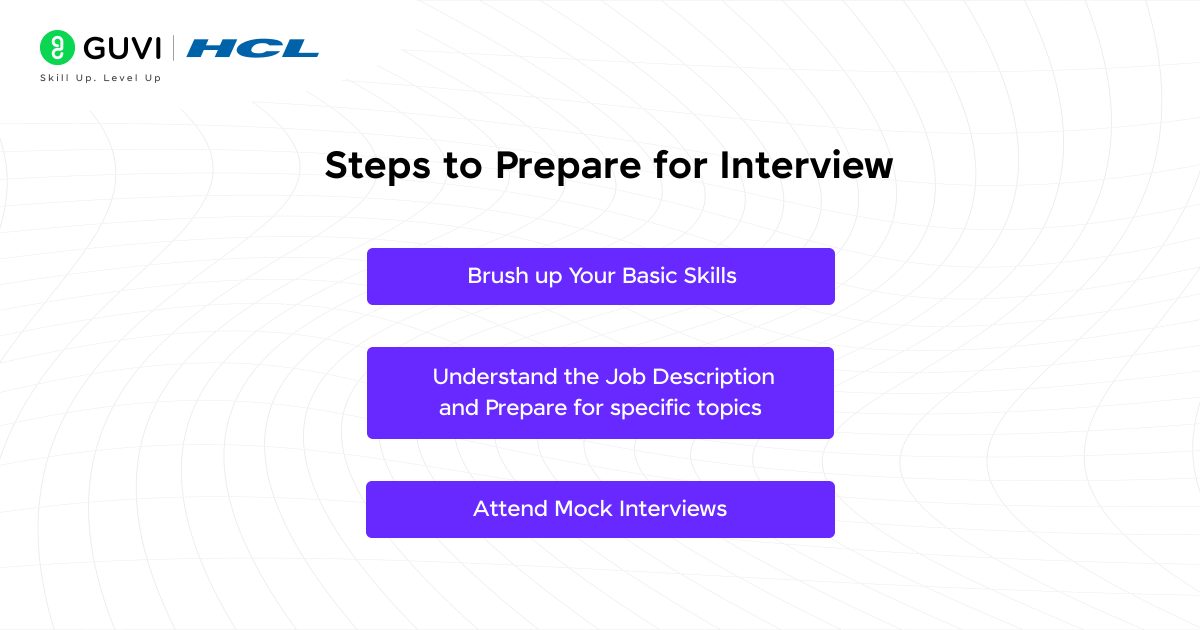
1. Brush Up Your Basic Skills
The first step is to revise the fundamentals required for a data science role:
- Python: Variables, functions, classes, objects, and basic OOP concepts.
- Mathematics: Linear algebra, calculus, and probability.
- Statistics: Hypothesis testing, regression, distributions, and statistical measures.
- Data Analysis: Data cleaning, exploration, processing, and visualization using NumPy, Pandas, and Scikit-learn.
- Machine Learning Algorithms: Supervised learning, unsupervised learning, classification, regression, clustering, and recommendation systems.
- Evaluation Metrics: Accuracy, precision, recall, F1-score, confusion matrix, MAE, RMSE, and MSE.
2. Understand the Job Description
Read the job description carefully before the interview. Identify the tools, technologies, and responsibilities mentioned by the company.
If the role requires SQL, Python, NLP, MongoDB, cloud platforms, or specific machine learning frameworks, spend additional time revising those topics
3. Attend Mock Interviews
Mock interviews can help you become more comfortable explaining technical concepts and solving problems under pressure.
Practice with a friend, mentor, or interview platform. Focus on explaining your reasoning instead of only giving the final answer.
Prepare for data science roles with HCL GUVI’s Data Science Course. Build practical skills in Python, statistics, machine learning, and data analysis through hands-on projects and industry-focused learning.
Top 40 Data Science Interview Questions With Answers
Basic Data Science Interview Questions
1. What is Data Science?
Data science is the process of using data, statistics, mathematics, programming, and machine learning to extract useful insights and solve real-world problems.
2. What are the steps involved in the data science lifecycle?
The main steps include:
- Define the problem
- Collect data
- Clean and preprocess data
- Perform exploratory data analysis
- Engineer features
- Build the model
- Evaluate the model
- Deploy the model
3. What is the difference between supervised and unsupervised learning?
Supervised learning uses labeled data to learn a relationship between inputs and outputs. Classification and regression are common examples.
Unsupervised learning works with unlabeled data and identifies patterns or groups. Clustering and dimensionality reduction are common examples.
4. What is the difference between overfitting and underfitting?
Overfitting occurs when a model learns the training data too closely and performs poorly on unseen data.
Underfitting occurs when a model is too simple to capture important patterns in the data.
5. What is A/B testing in data science?
A/B testing is a statistical method used to compare two versions of a product, webpage, application, or feature to determine which performs better.
6. How do you handle missing data?
Common approaches include:
- Removing rows or columns
- Filling missing values with mean or median
- Using forward or backward filling
- Using model-based imputation when appropriate
7. What is the Curse of Dimensionality?
The Curse of Dimensionality occurs when increasing the number of features makes data increasingly sparse and can make machine learning models harder to train effectively.
8. What are bias and variance?
Bias is error caused by overly simple assumptions, while variance occurs when a model is too sensitive to changes in the training data.
A good model aims to balance both.
9. What is feature engineering?
Feature engineering involves creating, transforming, or selecting features from existing data to improve a machine learning model’s performance.
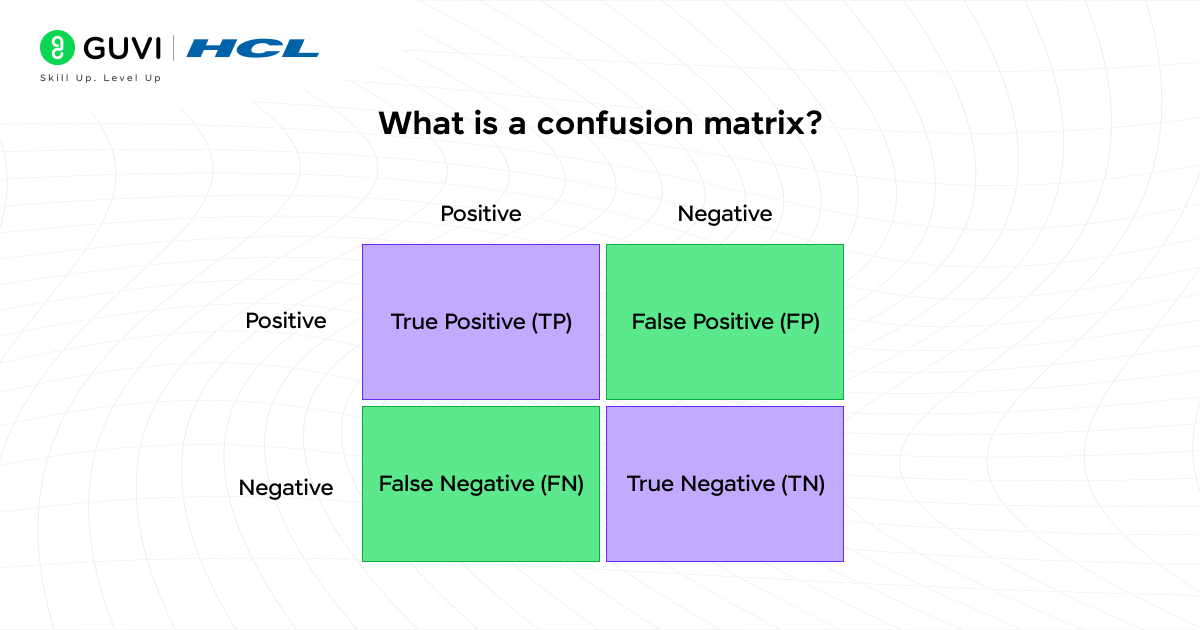
10. What is a confusion matrix?
A confusion matrix evaluates a classification model using:
- True Positive
- True Negative
- False Positive
- False Negative
It helps calculate metrics such as precision, recall, and F1-score.
10. What is a confusion matrix?
Machine Learning and Statistics Questions
11. How does Random Forest work?
Random forest combines multiple decision trees. Each tree is trained using different samples and features, and their predictions are combined to produce the final result.
12. What are ensemble methods?
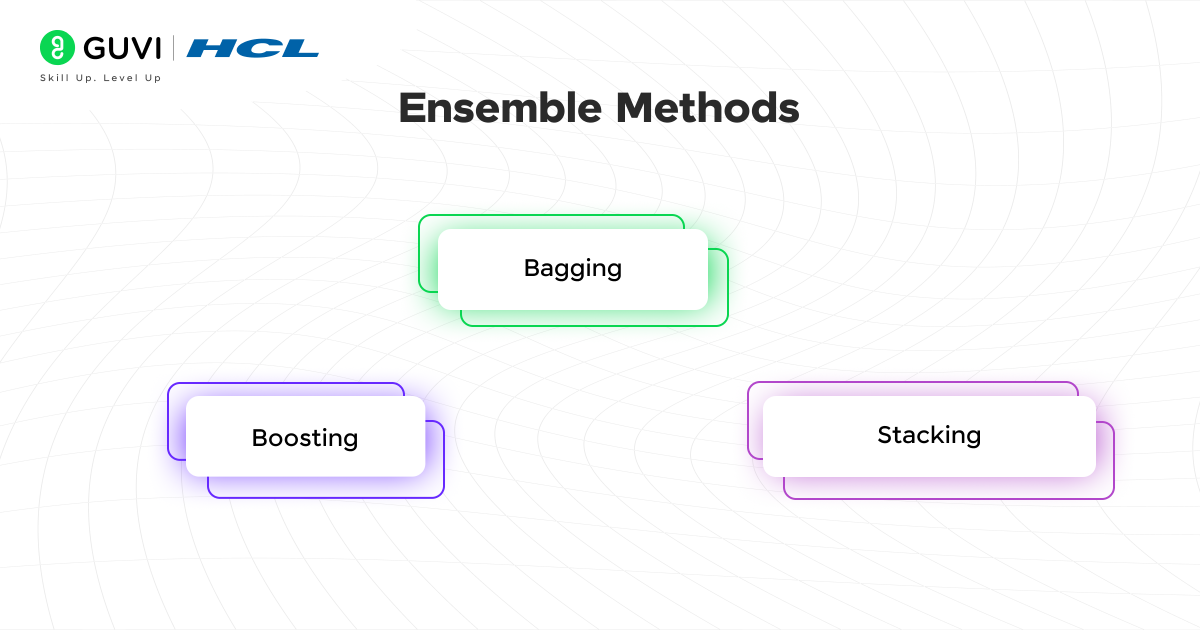
Ensemble methods combine multiple models to improve predictions.
Common approaches include:
- Bagging
- Boosting
- Stacking
13. What is time series analysis?
Time series analysis studies data collected at specific time intervals and can be used to identify patterns and forecast future values.
14. What is the difference between K-Means and KNN?
K-Means is an unsupervised clustering algorithm.
K-Nearest Neighbors (KNN) is generally used for supervised classification or regression.
15. What is a neural network?
A neural network is a machine learning model made up of interconnected nodes arranged in layers. It can learn complex patterns from data.
16. What is Naive Bayes?
Naive Bayes is a probabilistic classification algorithm based on Bayes’ theorem. It is commonly used for text classification and spam detection.
17. What is a Z-score?
A Z-score indicates how many standard deviations a value is away from the mean of a distribution. It can also help identify potential outliers.
18. What is a Decision Tree?
A Decision Tree uses a tree-like structure of conditions to make predictions. Each internal node represents a decision, while the branches represent possible outcomes.
19. What is Support Vector Machine?
SVM is a supervised learning algorithm that finds a decision boundary that separates classes. It can be used for classification and regression.
20. What is a p-value?
A p-value helps determine the strength of evidence against a null hypothesis. A smaller p-value can indicate stronger evidence against the null hypothesis.
Programming and Tools-Based Questions
21. What is the difference between SQL and NoSQL databases?
| Feature | SQL | NoSQL |
| Structure | Structured tables | Flexible formats |
| Schema | Usually predefined | Generally flexible |
| Examples | MySQL, PostgreSQL | MongoDB, Cassandra |
| Querying | SQL | Varies by database |
22. Write a Python program to calculate mean, median, and mode.
from collections import Counter

numbers = [1, 2, 2, 3, 4]

mean = sum(numbers) / len(numbers)

sorted_numbers = sorted(numbers)

n = len(numbers)

if n % 2 == 0:

    median = (sorted_numbers[n//2 - 1] + sorted_numbers[n//2]) / 2

else:

    median = sorted_numbers[n//2]

mode = Counter(numbers).most_common(1)[0][0]

print(mean, median, mode)
23. How do you split data into training and testing sets?
You can use train_test_split() from Scikit-learn.
from sklearn.model_selection import train_test_split

X_train, X_test, y_train, y_test = train_test_split(

    X, y, test_size=0.2, random_state=42

)
24. How would you detect outliers?
Outliers can be detected using:

- Box plots
- Scatter plots
- Z-score
- Interquartile Range (IQR)
25. What are the main steps in Exploratory Data Analysis?
The main steps include:
- Data collection
- Data cleaning
- Data transformation
- Descriptive statistics
- Data visualization
- Hypothesis testing
26. How can you merge two DataFrames in Python?
Pandas provides the merge() function to combine DataFrames using common columns or indexes.
merged_df = pd.merge(df1, df2, on="key", how="inner")27. How can you handle missing data in Pandas?
You can use:
- isna() or isnull() to identify missing values
- dropna() to remove missing values
- fillna() to replace missing values
28. What is the difference between R and Python?
R is particularly strong for statistical analysis and visualization. Python is a general-purpose programming language widely used for data analysis, machine learning, automation, and application development.
29. What is an ROC Curve?
An ROC curve shows the relationship between the true positive rate and false positive rate at different classification thresholds. It helps evaluate classification models.
30. How do you find the most frequent element in a Python list?
from collections import Counter

numbers = [1, 2, 3, 1, 2, 1]

result = Counter(numbers).most_common(1)[0][0]

print(result)Experienced-Level Data Science Interview Questions
Experienced candidates are often asked practical questions that test their ability to troubleshoot models, make technical decisions, and connect data science work with business requirements.
31. Your model’s accuracy suddenly drops overnight. What would you investigate?
I would first check:
- Data drift: Whether the incoming data distribution has changed.
- Feature pipeline: Whether a feature stopped updating or changed format.
- Concept drift: Whether the relationship between the features and target has changed.
32. Explain a machine learning model to a 5-year-old.
A machine learning model is like a friend who learns from your past choices. If you regularly choose chocolate ice cream, your friend may predict that you will choose chocolate again.
33. Your dataset has 98% Class A and 2% Class B. The model has 98% accuracy. Why could this be misleading?
The model could simply predict Class A every time and still achieve 98% accuracy.
For an imbalanced dataset, metrics such as precision, recall, F1-score, and ROC-AUC can provide more useful information.
34. You can choose only one metric for a binary classification problem. Which would you choose?
F1-score can be useful when both precision and recall matter, particularly with imbalanced classes. However, the appropriate metric ultimately depends on the business problem and the cost of different types of errors.
35. Your manager asks you to use deep learning. How would you decide whether it is appropriate?
I would consider:
- Amount of available data
- Problem complexity
- Model performance requirements
- Computing resources
- Latency requirements
- Explainability requirements
A simpler model may be more appropriate if it performs sufficiently well.
36. Your model has high variance. What would you do?
High variance usually indicates overfitting. Possible solutions include regularization, reducing model complexity, collecting more data, selecting useful features, and using cross-validation.
37. How would you reduce model training time by 10×?
Possible approaches include:
- Feature selection
- Reducing dataset size during experimentation
- Using faster models
- GPU or distributed training
- Better hyperparameter optimization
- Caching preprocessing steps
38. Your clustering algorithm produces meaningless clusters. What could be wrong?
Possible reasons include incorrect cluster count, poor feature scaling, an unsuitable distance metric, or data that does not naturally contain meaningful clusters.
39. How would you explain feature importance to a non-technical person?
Feature importance shows which inputs have the strongest influence on a model’s predictions. It can be compared to ingredients in a recipe: some ingredients have a much greater effect on the final result than others.
40. If you could ask only one question before modeling a dataset, what would you ask?
I would ask:
“What business question are we trying to answer?”
This helps determine the target, required data, evaluation metric, and appropriate modeling approach.
Start Your Learning Journey with HCL GUVI.
Prepare for data science roles with HCL GUVI’s Data Science Course. Build practical skills in Python, statistics, machine learning, and data analysis through hands-on projects and industry-focused learning.
Conclusion
Preparing for a data science interview requires more than memorizing definitions. You should be comfortable with Python, SQL, statistics, machine learning, data analysis, and practical problem-solving.
If you are a fresher, focus on building strong fundamentals and explaining your projects clearly. If you are an experienced professional, spend more time on real-world scenarios, model troubleshooting, business problems, and technical decision-making.
Practice regularly, attend mock interviews, and review the job description before every interview. This will help you approach technical questions with greater confidence.
FAQs
1. What topics are commonly asked in a data science interview?
Python, SQL, statistics, machine learning, data cleaning, feature engineering, model evaluation, and practical problem-solving are common topics.
2. Are data science interviews different for experienced candidates?
Yes. Experienced candidates may face more scenario-based questions involving model performance, business problems, deployment, data quality, and troubleshooting.
3. How should I prepare for a data science interview?
Start with Python, SQL, statistics, and machine learning fundamentals. Then practice coding problems, case studies, projects, and mock interviews.
4. Is Python important for data science interviews?
Yes. Python is commonly used for data analysis, machine learning, data processing, and coding assessments.
5. What should I do if I don’t know an interview answer?
Stay calm and explain what you know. If you are unsure, clarify your assumptions and describe how you would approach finding the answer instead of guessing.
Success Stories

About the Author
Jebasta
I translate the language of data into stories that anyone can understand. As a writer with a data science background, I simplify analytics, AI, and decision-making so beginners and enthusiasts can confidently explore the world of data.
View all posts by Jebasta
Connect with me @






Did you enjoy this article?