


Data Science Articles
Hypothesis Testing: A Beginner's Guide for Data Scientists
Pandas Advanced Techniques for Data Scientists
Data Warehouse vs. Data Lake vs. Lakehouse: What's the Difference?
SQL Window Functions: Practical Examples Every Analyst Needs
Get In Touch For Details! Request More Information

A Complete Data Scientist Roadmap for Beginners
Oct 05, 2026 6 Min Read 14917 Views
(Last Updated)
Do you want to pursue a career in data science? If so, you’ve probably been confused by the sheer amount of information out there. Choosing to become a data scientist is easy, but figuring out exactly how to get there is the hard part.
A data scientist roadmap is a structured, step-by-step path covering programming, statistics, machine learning, and tools that takes you to job-ready skills. The right path looks different depending on whether you’re a student, a fresh graduate, or already working elsewhere.
This guide gives you that roadmap, broken down by where you’re actually starting from, plus a complete skills checklist you can download and follow step by step.
Table of contents
- TL;DR Summary
- Want the Full Program Behind This Roadmap?
- What Does a Data Scientist Do?
- Roles and Responsibilities Covered in This Data Scientist Roadmap
- Your Data Scientist Roadmap, by Starting Point
- If You're a Student Following This Data Scientist Roadmap
- Following the Data Scientist Roadmap After Graduation
- A Data Scientist Roadmap for IT Professionals
- A Data Scientist Roadmap for Non-IT Professionals
- The Core Data Scientist Roadmap Skills
- Programming Language
- Maths and Statistics
- Machine Learning and Natural Language Processing
- Data Collection and Cleaning
- Key Tools for Data Science
- Git and GitHub
- Average Salaries After Completing a Data Scientist Roadmap in India
- How to Build a Portfolio Alongside Your Data Scientist Roadmap
- Conclusion
- FAQs
- What are the key skills required to become a data scientist?
- How long does it take to become a data scientist?
- Do I need a degree to become a data scientist?
- Which tools and languages should I learn first as a beginner?
- How can I gain practical experience as a beginner in data science?
TL;DR Summary
- What it is: a complete, persona-based roadmap to becoming a data scientist, tailored to your actual starting point
- Core skills to build: programming (Python or R), SQL, statistics, machine learning, and key tools like Pandas, Scikit-learn, and Tableau
- Timeline: 6 months to 2 years depending on your background, dedication, and chosen path
- The shortcut most guides miss: your starting point changes what you should learn first, students, career-switchers, and working IT professionals all need different sequences
- Want it structured and mentor-led? download the full IIT Madras Data Science program brochure and syllabus to see this roadmap taught step by step
Want the Full Program Behind This Roadmap?
Everything covered in this guide, programming, statistics, machine learning, and tools, maps directly onto HCL GUVI’s IIT Madras-certified Data Science program.
Download the complete course brochure and syllabus (PDF) to see the full module-by-module curriculum, instructor profiles, industry projects, and placement support, everything you’d need to turn this roadmap into a structured, mentor-led learning path instead of a self-guided one.
What Does a Data Scientist Do?
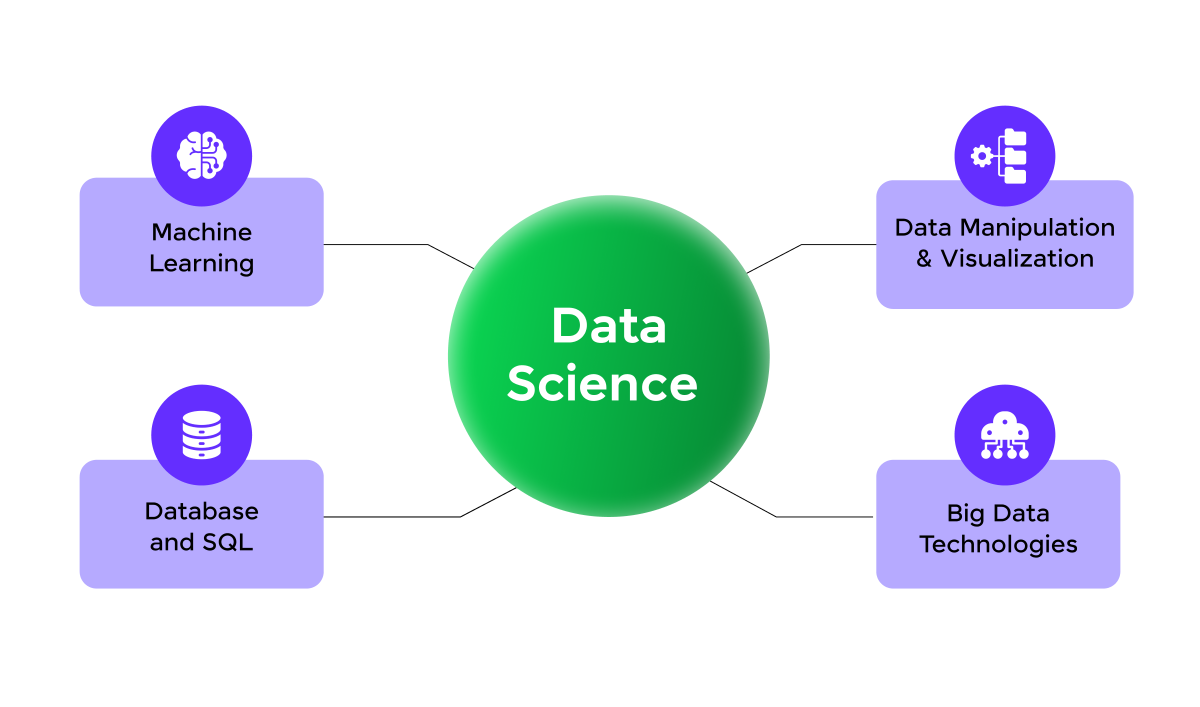
A data scientist is a skilled professional who leverages expertise in statistics, mathematics, computer science, and domain knowledge to extract meaningful insights from large and complex datasets.
Data scientists also design and deploy data-driven applications and predictive models to address real-world problems across industries, contributing directly to business growth and decision-making.
- Data scientist jobs are projected to grow by 34% from 2024 to 2034, far higher than the 3% average growth projected for all occupations.
- Around 23,400 data scientist job openings are expected each year in the United States throughout the decade.
Roles and Responsibilities Covered in This Data Scientist Roadmap
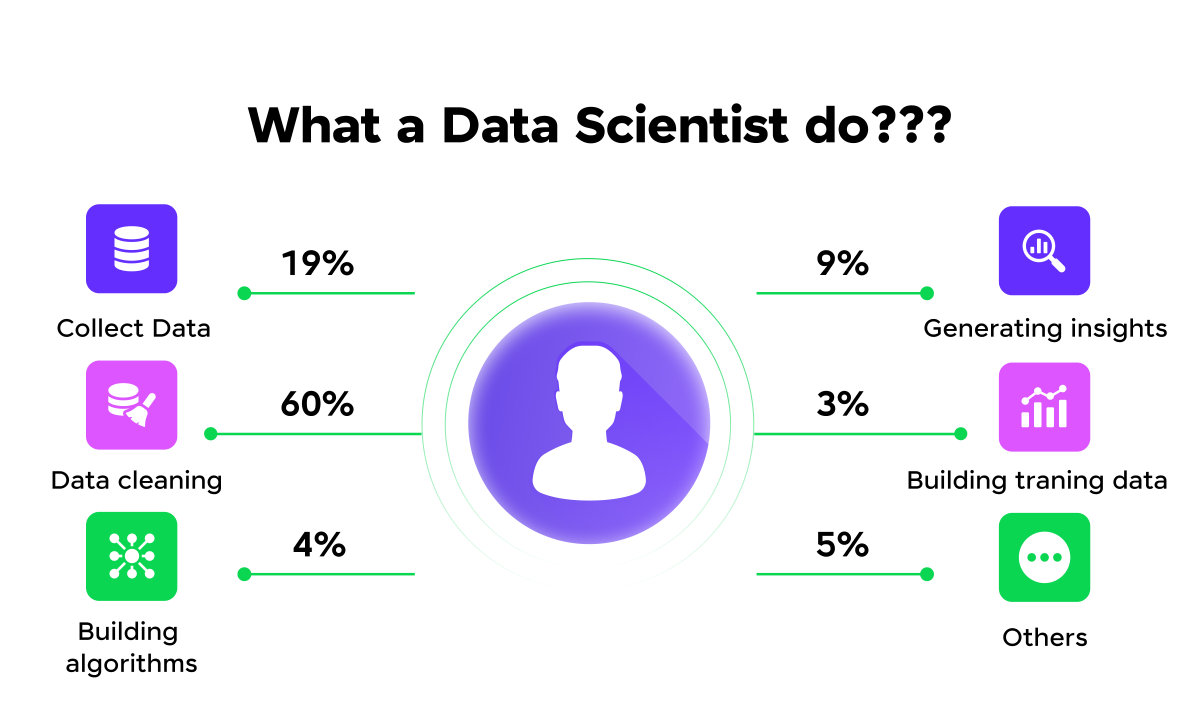
- Data Collection: gathering relevant data from various sources, including databases, APIs, and web scraping.
- Data Cleaning: removing noise, handling missing values, and ensuring data quality.
- Data Preparation: transforming and structuring data so it’s ready for analysis and model building.
- Model Development: designing machine learning algorithms to solve specific business problems.
- Data Analysis: applying statistical techniques to identify patterns, trends, and correlations.
- Data Visualization: creating dashboards and visuals that present insights clearly.
- Model Evaluation: validating models using techniques like cross-validation and A/B testing.
- Collaboration: working with data engineers, analysts, and business stakeholders to align with business goals.
- Continuous Learning: staying current with advancements in data science, ML, and AI.
Your Data Scientist Roadmap, by Starting Point
Not everyone following this data scientist roadmap is starting from the same place, and treating a student, a career-switcher, and a working IT professional the same way wastes time for all three. Here’s how the path differs by where you’re starting.
If You’re a Student Following This Data Scientist Roadmap
You likely have the most runway and the fewest existing commitments, so use it to build depth, not just speed.
- Months 1-3: Python or R fundamentals, SQL basics, and core statistics (descriptive stats, probability, hypothesis testing)
- Months 4-8: machine learning fundamentals (supervised and unsupervised learning), plus 2-3 solid portfolio projects
- Months 9-12+: specialize in an area like NLP or computer vision, build a stronger GitHub presence, and pursue internships
Your advantage in this data scientist roadmap: time. Use it to build genuine depth in statistics and math, areas that are harder to backfill later in a career.
Following the Data Scientist Roadmap After Graduation
Speed to employability matters more here than depth in any one area.
- Months 1-2: Python, SQL, and statistics basics, compressed and focused, skip anything not directly useful for entry-level roles
- Months 3-5: core machine learning plus 3-4 portfolio-ready projects that mirror real business problems
- Month 6: resume, LinkedIn, mock interviews, and active applications, in parallel with your learning, not after it
Your advantage: flexibility. Since you can study full-time, compress this data scientist roadmap into 6 months and move straight into applications.
A Data Scientist Roadmap for IT Professionals
You already have programming logic, SQL, Git, and debugging experience. Don’t re-learn what you already know.
- Month 1: statistics and probability, genuinely the biggest gap for most IT professionals, plus Python’s data libraries (NumPy, Pandas)
- Months 2-4: machine learning fundamentals and your first few projects, leaning on your existing GitHub habits
- Months 5-6: specialization, portfolio polish, and interview prep, while exploring internal mobility at your current company first
Your advantage: your existing technical background moves you through this data scientist roadmap’s material noticeably faster than someone starting from zero.
A Data Scientist Roadmap for Non-IT Professionals
You’re starting further back on the technical side, but your domain expertise is a genuine asset once you reach it.
- Months 1-3: programming fundamentals from scratch (Python is the easiest entry point), then SQL and basic statistics
- Months 4-9: core machine learning, with projects deliberately chosen in your current industry, this is where your domain knowledge becomes a real differentiator
- Months 10-12+: portfolio building and a career transition plan, possibly starting with a data analyst role as a stepping stone into data science
Your advantage on this data scientist roadmap: domain expertise. A data scientist who already understands healthcare, finance, or retail deeply is more valuable in that industry than a generalist.
The Core Data Scientist Roadmap Skills
Regardless of your starting point, these are the actual skills every path above eventually converges on.
1. Programming Language
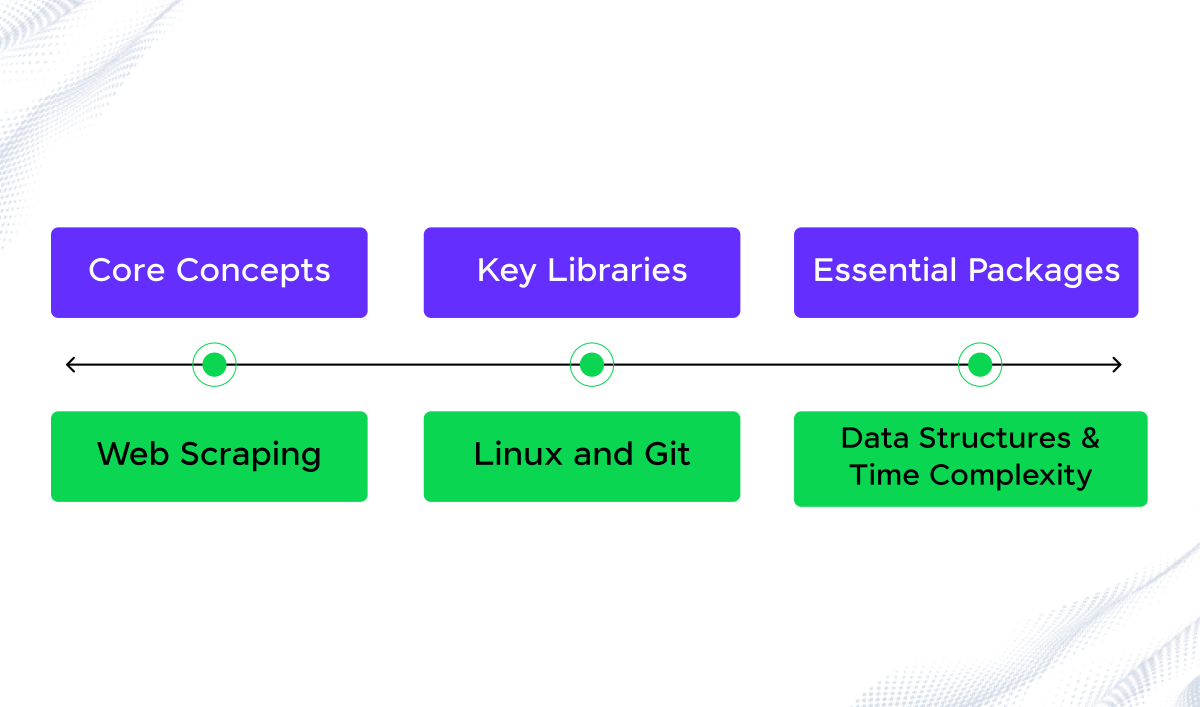
Every data scientist roadmap starts here: a solid grasp of programming concepts, especially data structures and algorithms, is essential. Python and R are the most popular choices, though Java, Scala, and C++ play a role in performance-critical scenarios.
Python is the go-to language for most data science work. You’ll need:
- Core Concepts: lists, sets, tuples, dictionaries, and function definitions
- Key Libraries: NumPy for numerical computation, Pandas for data manipulation, Matplotlib and Seaborn for visualization
R is another powerful option in the data science toolkit, particularly for statistical analysis:
- Core Concepts: vectors, lists, data frames, matrices, and arrays
- Essential Packages: dplyr for data manipulation, ggplot2 for visualization, Shiny for interactive web apps
Understanding databases matters too. SQL is essential for querying relational databases, while familiarity with MongoDB helps with non-relational data. Round this out with data structures and time complexity, web scraping, and basic Linux and Git proficiency.
2. Maths and Statistics
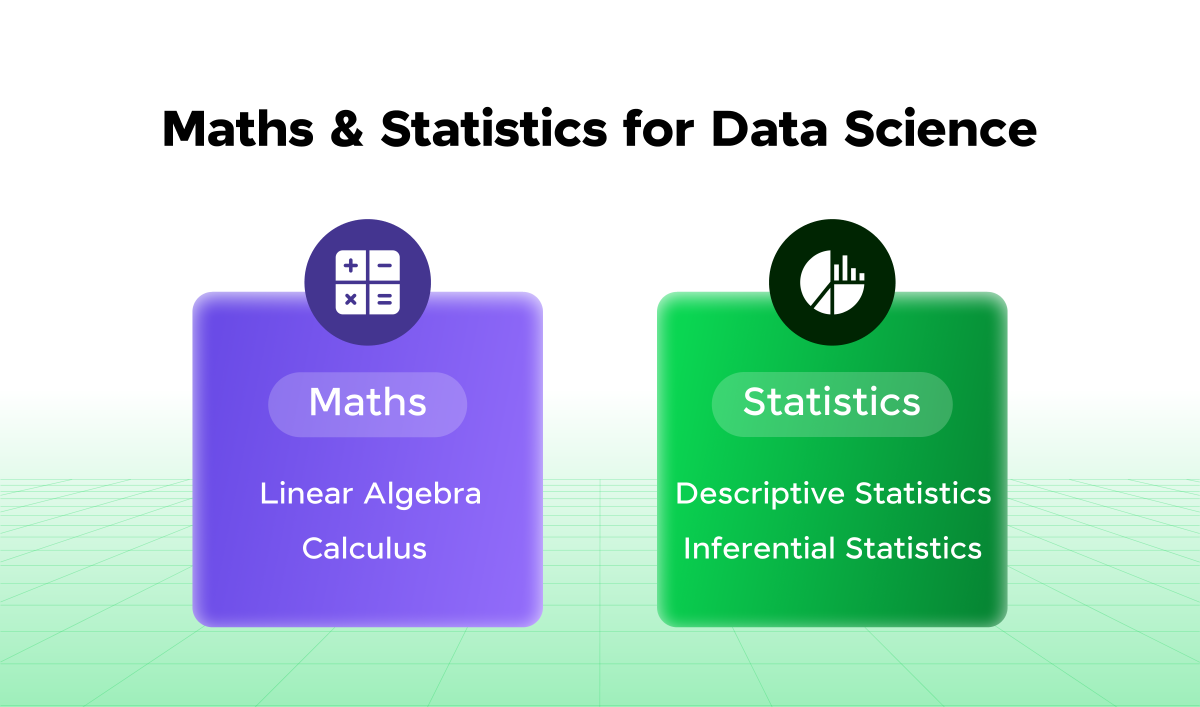
- Linear Algebra: vector spaces, matrices, eigenvalues, and eigenvectors
- Calculus: differentiation, integration, and partial derivatives for understanding model training
- Probability Theory: distributions, random variables, and Bayes’ theorem
- Descriptive Statistics: mean, median, mode, variance, standard deviation
- Inferential Statistics: hypothesis testing, confidence intervals, and p-values
- Regression Analysis: linear and logistic regression for modeling relationships
- Optimization Techniques: gradient descent and related algorithms
- Hypothesis Testing: t-tests, chi-square tests, and ANOVA
3. Machine Learning and Natural Language Processing
Machine Learning:
- Supervised Learning: Learn algorithms like linear regression, decision trees, and support vector machines for tasks like classification and regression.
- Unsupervised Learning: Explore clustering techniques such as k-means and hierarchical clustering, and dimensionality reduction methods like PCA (Principal Component Analysis).
- Neural Networks: Understand the architecture and functioning of neural networks, including feedforward networks, convolutional networks (CNNs), and recurrent networks (RNNs).
- Model Evaluation: Master techniques such as cross-validation, confusion matrices, ROC curves, and precision-recall metrics to evaluate model performance.
- Ensemble Methods: Study methods like Random Forest, Gradient Boosting, and Bagging, which combine multiple models to improve predictive accuracy.
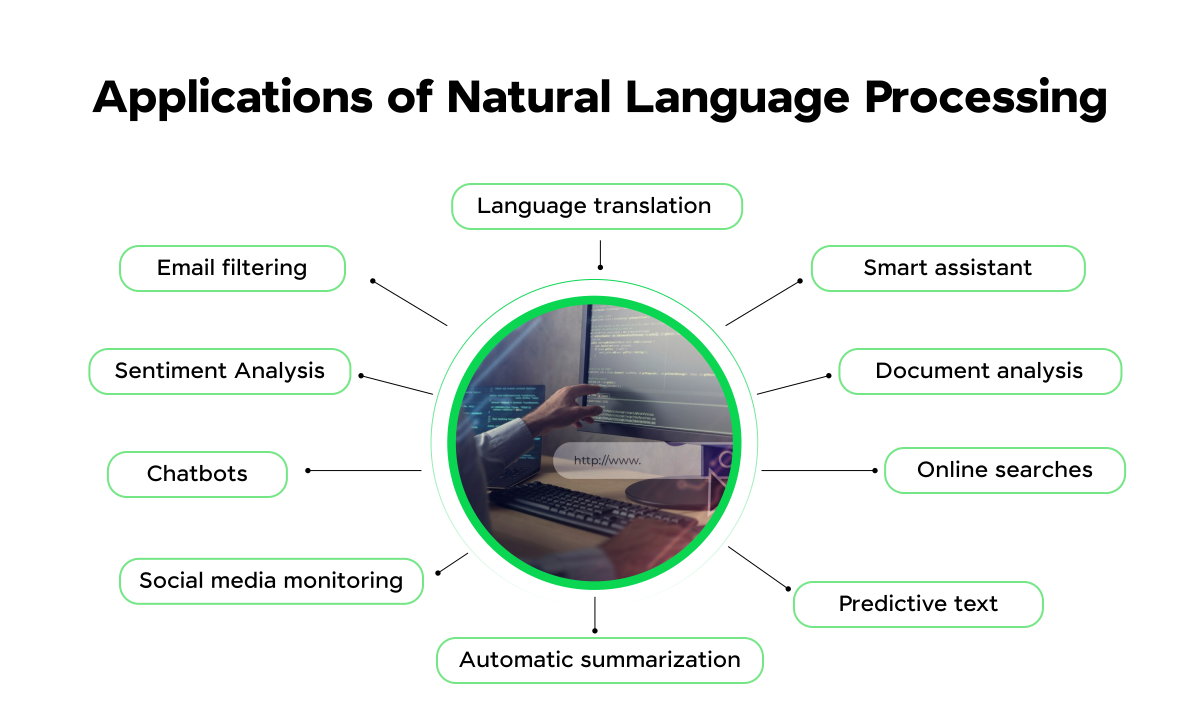
Natural Language Processing (NLP):
- Tokenization: Break down text into words, sentences, or subwords, which form the basic units for analysis in NLP tasks.
- Part-of-Speech Tagging: Assign grammatical categories (nouns, verbs, adjectives) to words in a sentence, aiding in syntactic analysis and understanding context.
- Sentiment Analysis: Detect and categorize opinions expressed in text, identifying sentiment as positive, negative, or neutral.
- Named Entity Recognition (NER): Identify and classify entities such as names, organizations, locations, and dates within text data.
- Text Classification: Apply machine learning algorithms to categorize text into predefined categories, useful in tasks like spam detection and topic identification.
- Language Models: Understand models like BERT, GPT, and LSTM that predict the likelihood of a sequence of words, enabling tasks like translation, summarization, and text generation.
- Word Embeddings: Explore techniques like Word2Vec, GloVe, and TF-IDF to represent words in vector space, capturing semantic meaning and relationships between words.
- Text Preprocessing: Learn techniques such as stemming, lemmatization, and stop-word removal to clean and normalize text data for analysis.

4. Data Collection and Cleaning
Data collection and cleaning are critical stages in the data science process. Data collection involves gathering relevant data from various sources, such as databases, APIs, web scraping, or sensor networks.
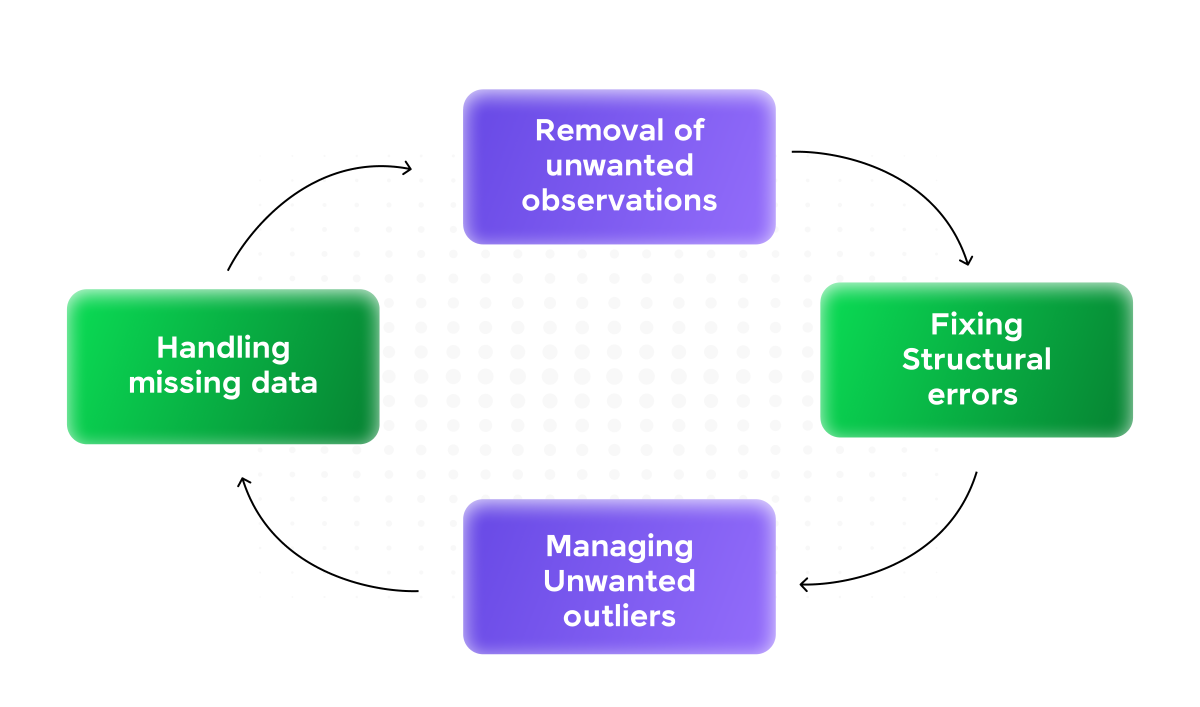
It is essential to ensure data quality, reliability, and completeness during this phase. Once collected, the data often requires cleaning to address issues like missing values, duplicates, inconsistencies, and outliers, which can adversely affect analysis and modeling.
Data cleaning techniques involve imputing missing values, resolving inconsistencies, and handling outliers to create a clean, reliable dataset.
Proper data collection and cleaning lay the foundation for accurate analysis and modeling, ensuring that the insights drawn from the data are valid and trustworthy.
5. Key Tools for Data Science
Data science relies on a variety of tools that facilitate data manipulation, analysis, visualization, and modeling. Here are some key tools commonly used in data science:
- Jupyter Notebooks: Interactive web-based environments that allow data scientists to create and share documents containing code, visualizations, and explanatory text. They are widely used for data exploration and prototyping.
- SQL (Structured Query Language): A language for managing and querying relational databases. SQL is essential for data retrieval and data manipulation tasks.
- Apache Hadoop: An open-source framework for distributed storage and processing of large datasets. It is used for handling big data.
- Apache Spark: Another open-source distributed computing system that provides fast and scalable data processing, machine learning, and graph processing capabilities.
- Tableau: A data visualization tool that enables users to create interactive and visually appealing dashboards and reports.
- Scikit-learn: A machine learning library for Python, providing various algorithms for classification, regression, clustering, and more.
- Excel: Widely used for basic data analysis and visualization due to its accessibility and familiarity.
- Git: Version control system used for tracking changes in code and collaborating with others in data science projects.
- Amazon Web Services (AWS), Microsoft Azure, Google Cloud Platform (GCP): Cloud computing platforms that offer various services for data storage, processing, and machine learning.
- NLTK (Natural Language Toolkit): A Python library for natural language processing tasks.
6. Git and GitHub
This step in the data scientist roadmap is easy to underrate: Git and GitHub provide version control and collaboration capabilities that are genuinely central to how data science work gets done in teams.
Git is a distributed version control system that tracks changes in your code and project files over time. It lets you review and revert to previous versions, and enables multiple team members to branch off, work independently, and merge changes back without conflicts.
Features of Git:
- Version Control: tracks file changes over time, with the ability to revert
- Branching and Merging: work on features independently, then merge back
- Distributed System: every developer holds a complete project history
- Staging Area: control exactly which changes go into a commit
- Commit History: a transparent, detailed log of all changes
GitHub is a web-based hosting service built on Git, and functions as a social platform for sharing work and collaborating on open-source projects. Public repositories let you showcase projects and build your portfolio, while pull requests and issues make remote collaboration straightforward.
Features of GitHub:
- Repository Hosting: cloud storage for Git repositories
- Pull Requests: code review and discussion before merging
- Issues and Project Management: tracking bugs and feature requests
- GitHub Actions: automating CI/CD, testing, and deployment
- Collaboration Tools: wikis, discussions, and code reviews
Ready to turn this data scientist roadmap into real skills? Kickstart your journey by enrolling in HCL GUVI’s Data Science Course where you’ll master technologies like MongoDB, Tableau, Power BI, and Pandas, and build real-life projects.
Alternatively, if you’d like to explore Python through a self-paced course, try HCL GUVI’s Python certification course.
Average Salaries After Completing a Data Scientist Roadmap in India
Data science remains one of the most sought-after careers in India, with competitive salaries reflecting strong demand for skilled professionals.
| Experience Level | Average Annual Salary (INR) |
|---|---|
| Entry-Level (0-2 years) | ₹4,00,000 – ₹8,00,000 |
| Mid-Level (2-5 years) | ₹8,00,000 – ₹15,00,000 |
| Senior-Level (5-10 years) | ₹15,00,000 – ₹25,00,000 |
| Lead/Manager (10+ years) | ₹25,00,000 – ₹50,00,000+ |
How to Build a Portfolio Alongside Your Data Scientist Roadmap
Learning data science skills matters, but recruiters also want proof you can apply them to real problems. A strong portfolio shows practical ability, project thinking, and problem-solving confidence.
- End-to-End Projects: build projects that start with raw data and end with clear insights, predictions, or dashboards, showing you understand the complete workflow.
- Problem Statement: explain the business or real-world problem clearly before anyone sees your code.
- Clean Code and Documentation: readable code, comments, and a short README make your work easy to review.
- Visual Insights: charts, graphs, and dashboards that explain your results clearly.
- GitHub and LinkedIn Presence: upload projects and share key learnings to build a professional data science profile.
Conclusion
Starting a career by following a data scientist roadmap may feel overwhelming at first, but the right data scientist roadmap, matched to where you’re actually starting from, makes the journey far easier to follow. You don’t need to master everything at once.
Follow this data scientist roadmap in the sequence that fits your situation, starting with programming, statistics, data handling, and machine learning, then build projects that prove your skills in real-world scenarios.
Data science rewards consistent practice and curiosity, the more you work with real datasets and explain your insights clearly, the more confident you become.
If you’d rather follow this roadmap through a structured, mentor-led program instead of self-study, download the full course brochure and syllabus to see exactly how it’s taught.
FAQs
What are the key skills required to become a data scientist?
Essential skills include programming (Python/R), statistics, data wrangling, machine learning, and data visualization.
How long does it take to become a data scientist?
It typically takes 6 months to 2 years, depending on prior knowledge, dedication, and the learning path chosen.
Do I need a degree to become a data scientist?
While a degree in a related field helps, it’s not mandatory. Practical skills and project experience often hold more value.
Which tools and languages should I learn first as a beginner?
Start with Python or R for programming, SQL for databases, and tools like Jupyter Notebooks, TensorFlow, and Tableau.
How can I gain practical experience as a beginner in data science?
Engage in personal projects, participate in Kaggle competitions, and complete internships or freelance work.
Success Stories

About the Author
Jebasta
I translate the language of data into stories that anyone can understand. As a writer with a data science background, I simplify analytics, AI, and decision-making so beginners and enthusiasts can confidently explore the world of data.
View all posts by Jebasta
Connect with me @

Did you enjoy this article?
Comments








It's really good
Any recommendations to data science online course