



Building an End-to-End Data Science Project in R
Building an End-to-End Data Science Project
Preparing and Cleaning the Student Performance Dataset
This project uses the clean file from Project 2, so run 02_intermediate_project.R first. Save your code as 03_advanced_project.R.
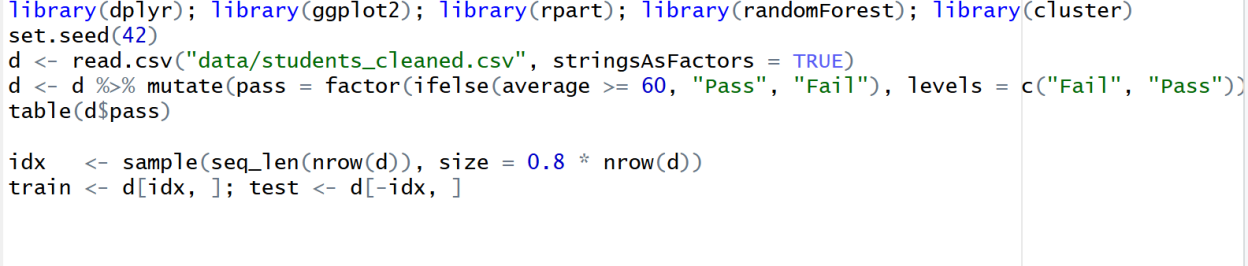
The code loads the data, creates a Pass or Fail label from the average mark using a threshold of 60, and splits the students into training and test sets.
Keep the test set untouched until the end, so the final score is honest.
Performing Exploratory Data Analysis and Predictive Modeling
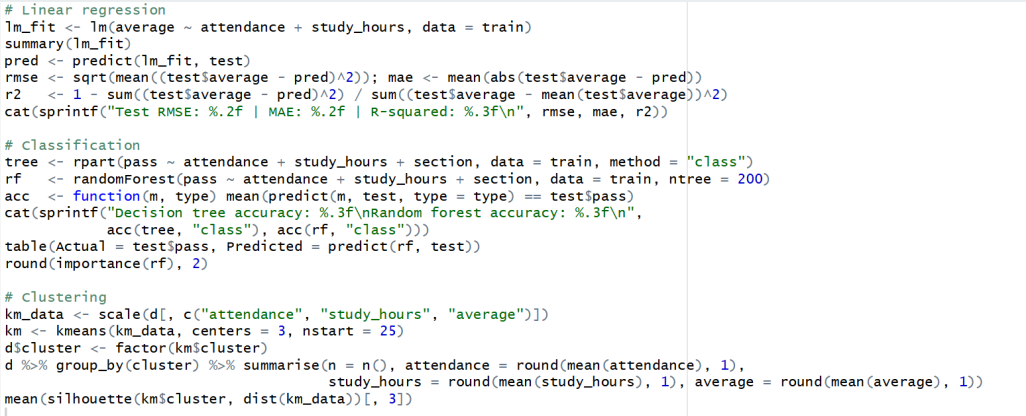
Now build the models:
- Linear regression to predict the average mark.
- Decision tree to predict Pass or Fail.
- Random forest to predict Pass or Fail.
- K-means clustering to find student groups.
We compare more than one model because one model alone can give a false sense of confidence.
Presenting Final Results Through Visualizations and a Project Report
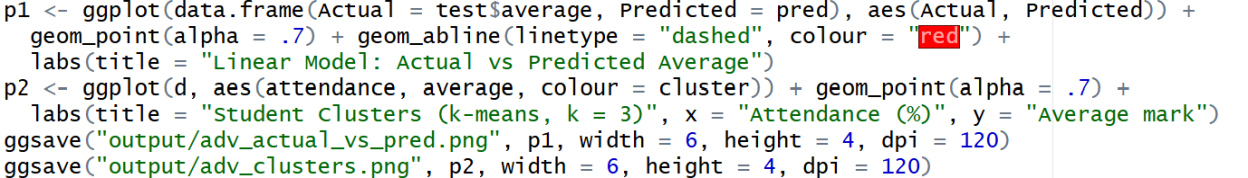
The last part draws two charts and saves them. Then use report.Rmd, shown earlier, to share the results.
Share the scripts, data, and charts so anyone can repeat your work.
Main Results from the Project
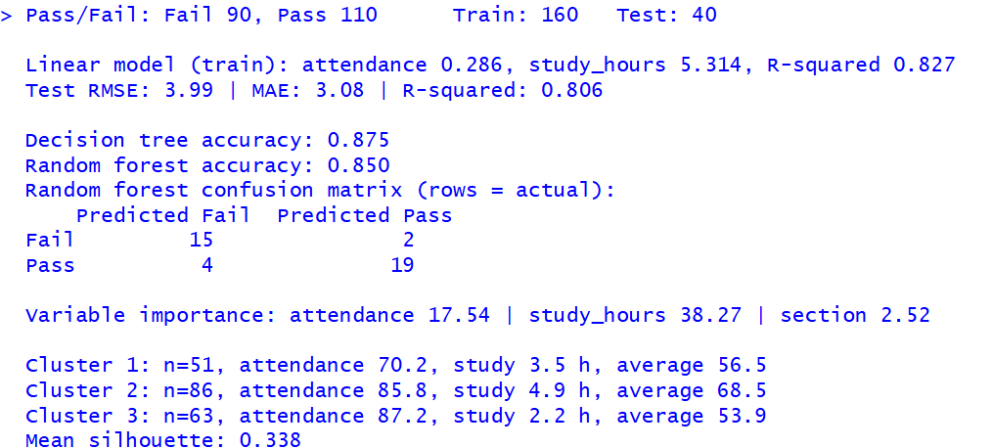
- Model performance: On unseen students, the linear regression model achieved an R-squared of 0.806, explaining about 81% of the variation in marks in the test set. The RMSE was 3.99 marks, while the MAE was 3.08 marks.
- Study hours and variable importance: Each additional study hour was associated with about 5.3 additional marks in the fitted regression model, holding attendance constant. The random forest ranked study hours as the most important variable and section as the least important.
- Model comparison: The decision tree achieved 87.5% accuracy, while the random forest achieved 85% accuracy. This difference represents just one student out of the 40 in the test set, so cross-validation would help provide a more reliable comparison.
- Student clusters: Cluster 2 had the highest average study time (4.9 hours) and marks (68.5). Cluster 3 had the highest average attendance (87.2%) but the lowest average marks (53.9). The mean silhouette score of 0.338 suggests that the clusters are only moderately separated and overlap to some extent.
Note: These results come from synthetic practice data, in which study hours were designed to be a major driver of marks. They demonstrate how to interpret model outputs, but they should not be treated as conclusions about real students.
The complete project files for this tutorial are available on GitHub. The repository includes the R scripts, datasets, visualizations, and report files used throughout the Beginner, Intermediate, and Advanced levels.
GitHub Repository: https://github.com/hariniavanthikaaaaaa747/r-for-data-science
To run the projects, download the files, extract the project folder, and open it in RStudio. Follow the accompanying Screenshot and Run Guide for the complete instructions.
Summary
You can now transform data with advanced dplyr tools, build and test prediction models, and group data with clustering. You can write clean, safe functions and share results through R Markdown and Shiny.
You have also finished a full data science project from start to end. Keep practising on real public datasets to grow further.
What's Next? Continue Your Data Science Journey
Congratulations on completing the R for Data Science course!
You've come a long way, from learning R basics to building your own data science project. Keep practising with real datasets and exploring new techniques to sharpen your skills.
Ready to take the next step? Explore HCL GUVI's Data Science Course to learn more and gain hands-on project experience.
Keep practising with public datasets, experiment with different models, and build projects that showcase your skills. Every project you complete brings you one step closer to becoming a confident data science practitioner.
Keep learning, keep building, and keep growing!
R for Data Science
Harini A
Recommended Handbooks

C++ Handbook

Python Basics Handbook

Javascript Handbook

Building a Random Joke Generator Using ReactJS

Build a Character Counter in React JS

Build Your QR Code Generator using React JS

Build a Birthday Reminder App using React JS

Building BMI Calculator Using ReactJS

Building Random Password Generator using ReactJS

Temperature Converter Project in React

Building a To-Do List App Using ReactJS

Building a Weather App Project Using ReactJS

Building a Quiz App in ReactJS

Building a GenZ Carousel App in React

ReactJS Projects Handbook

Computer Networks Tutorial

Operating System Tutorial

DBMS and SQL Tutorial

Java Tutorial

C Language Tutorial

PHP Tutorial

Android Tutorial

Linux Guide Tutorial

Data Structures and Algorithms Tutorial

Computer Architecture

HTML 5 References Tutorial

Docker Tutorial

GIT (Using Github) Tutorial

Go Language Tutorial

GIT Guide

CSS Tutorial

Advanced Data Structures

Spring Framework Tutorial

Spring Boot Tutorial

Kotlin Tutorial

Apache Cordova Tutorial

Python Tutorial

SASS-SCSS Tutorial

MongoDB Tutorial

Numpy Tutorial

PL-SQL Tutorial

Python Built-in Functions Tutorial

Pandas Tutorial

Elasticsearch Tutorial

Matplotlib Tutorial

Web Scraping Tutorial

Networking with Python

Tkinter Tutorial

Java Programs Tutorial

Java Examples Tutorial

Servlet Tutorial

JSP Tutorial

Java Type Conversion Tutorial

Java 8 Tutorial

Java 9 Tutorial

Java 10 Tutorial

Java 11 Tutorial

Java Util Library Tutorial

Building a Contact Us Form in ReactJS

Building a Age Calculator App Using ReactJS

Movie Recommendation System Project Using Content-Based Filtering

Recipe Finder App using ReactJS

Sales Data Analysis Project for Beginners Using Data Science

Student Performance Analysis Project for Beginners Using Data Science

Word Counter Tool Using ReactJS

Customer Churn Prediction Project Using Classification Techniques

Basic Expense Tracker App using ReactJS

Simple Binary to Decimal Converter in React

Real-Time Unit Converter in React

House Price Prediction Using Machine Learning (XGBoost)

Weather Data Analysis and Visualization Using Python

Expandable Accordion Component using React

OTP Verification Component using React

Cricket Data Analysis Using Python

Credit Card Fraud Detection for Beginners using Data Science

Deep learning Tutorial

Software Development Life Cycle Tutorial

Stock Price Prediction for Beginners using Data Science

Apache Kafka Tutorial

Angular Tutorial

Django Tutorial

Computer Programming Tutorial

Tensorflow Tutorial

Java OOPs Concepts Tutorial

Building an Image Classification System Using CNN

News Recommendation System Using Machine Learning

Fake Review Detection System using Machine Learning

Product Feedback App Using Full Stack Development - Customer Review and Rating System

Job Portal with Applicant Tracking System Using Full Stack Development

(FalCon Store) A Modern React-Based E-Commerce App UI with Admin Dashboard

Student Management System using Python (Beginner-Friendly Project Guide)

HTML Tutorial - From Basics to Implementation

Machine Learning Tutorial

ReactJS Tutorial

Hibernate Tutorial

Data Analysis with Python Handbook

Probability and Statistics for Data Science

Artificial Intelligence Tutorial

Power BI Tutorial

SQL for Data Science








