

Data Engineering Articles
Apache Iceberg Tutorial: A Practical Guide for Data Engineers
12 Important Data Architect Roles and Responsibilities
Get In Touch For Details! Request More Information
How Long it Would Take to Learn Data Engineering in 2026?
Oct 01, 2026 7 Min Read 15896 Views
(Last Updated)
How long does it take to learn data engineering from scratch? For most learners, the answer is 3 to 9 months of structured learning and consistent hands-on practice, depending on prior technical knowledge, weekly study hours, and the level of job readiness required.
Data engineering is not one skill. It combines programming, SQL, databases, data modelling, ETL and ELT pipelines, cloud platforms, distributed processing, orchestration, testing, and increasingly modern transformation and streaming tools.
Someone who already knows Python and SQL can progress much faster than someone starting without programming experience. Similarly, studying 30 to 40 hours every week creates a very different timeline from studying 10 hours alongside a full-time job.
This guide breaks the learning journey into 3-month, 6-month, and 9-month data engineering roadmaps. It also explains the skills to prioritise in 2026, projects to build, common learning mistakes, and how to determine when someone is ready to apply for entry-level data engineering roles.
Table of contents
- Quick Answer
- What Does a Data Engineer Actually Need to Learn in 2026?
- SQL and Relational Databases
- Python for Data Engineering
- Data Modelling
- ETL and ELT Pipelines
- Data Storage and File Formats
- Distributed Data Processing
- Workflow Orchestration
- Cloud Data Engineering
- Modern Transformation Tools
- Streaming Fundamentals
- How Long Does It Take to Learn Data Engineering?
- Becoming a Data Engineer in 3 Months: 30 to 40 Hours a Week
- Month 1: SQL, Python, and Data Foundations
- Month 2: Data Pipelines, Storage, and Spark
- Month 3: Orchestration, Cloud, and Portfolio Project
- Becoming a Data Engineer in 6 Months: 15 to 20 Hours a Week
- Months 1 and 2: Programming, SQL, and Databases
- Months 3 and 4: Data Engineering Systems
- Months 5 and 6: Cloud, Modern Stack, and Portfolio
- Becoming a Data Engineer in 9 Months: 10 to 15 Hours a Week
- Months 1 to 3: Strong Foundations
- Months 4 to 6: Core Data Engineering
- Months 7 to 8: Production-Oriented Skills
- Month 9: Portfolio and Interview Preparation
- What Factors Affect How Long It Takes to Learn Data Engineering?
- Existing SQL Knowledge
- Programming Experience
- Cloud Experience
- Weekly Study Hours
- Hands-On Practice
- Which Data Engineering Tools Should Beginners Prioritise in 2026?
- Best Data Engineering Projects for Beginners
- API to Data Warehouse Pipeline
- E-commerce Analytics Pipeline
- Spark Batch Processing Pipeline
- Airflow-Orchestrated Pipeline
- Streaming Data Pipeline
- How to Know When You Are Job-Ready for Data Engineering
- Common Mistakes That Slow Down Data Engineering Learning
- Learning Too Many Tools at Once
- Skipping SQL
- Starting With Big Data Too Early
- Building Only Tutorial Projects
- Ignoring Testing and Data Quality
- Ignoring Failure Scenarios
- Should Beginners Learn Hadoop in 2026?
- Is Data Engineering Difficult to Learn?
- Conclusion
- FAQ
- Can I Learn Data Engineering in 3 Months?
- How Long Does It Take to Become Job-Ready as a Data Engineer?
- Can a Beginner Learn Data Engineering Without Coding Experience?
- Is Python or SQL More Important for Data Engineering?
- What Should I Learn First for Data Engineering?
- Do Data Engineers Need to Learn Cloud Computing?
Quick Answer
Learning data engineering typically takes 3 to 9 months, depending on existing skills, weekly study time, and the depth of practical experience required.
- 3 Months: Intensive route requiring roughly 30 to 40 hours of study each week.
- 6 Months: More balanced route requiring about 15 to 20 hours per week.
- 9 Months: Gradual route suitable for learners studying approximately 10 to 15 hours weekly.
- Core Skills: SQL, Python, databases, data modelling, ETL/ELT, cloud platforms, Spark, and workflow orchestration.
- Job Readiness: Requires hands-on pipelines, debugging experience, Git, cloud exposure, and portfolio projects rather than theoretical knowledge alone.
What Does a Data Engineer Actually Need to Learn in 2026?
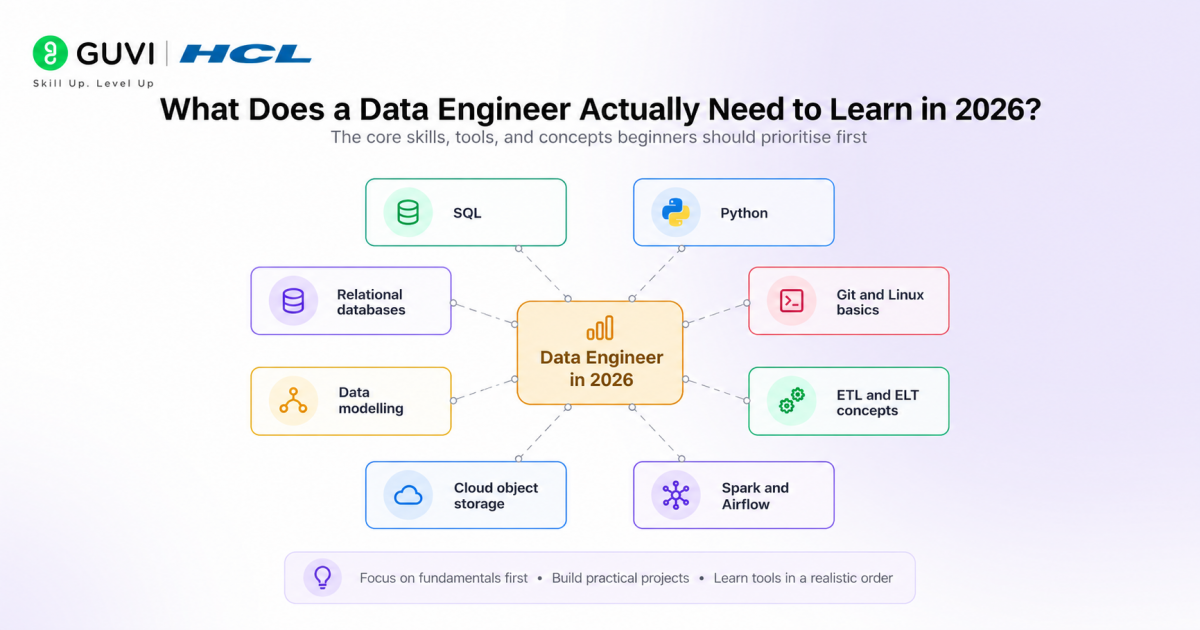
Before estimating the learning timeline, it is important to understand what a modern data engineer actually works with.
A beginner does not need to master every data technology available. The goal should be to understand the complete lifecycle of data and become comfortable with a focused stack.
1. SQL and Relational Databases
SQL remains one of the most important data engineering skills.
A learner should understand:
- SELECT, WHERE, GROUP BY, and JOIN operations
- Subqueries and Common Table Expressions
- Window functions
- Aggregations
- Indexes
- Transactions
- Query execution plans
- Query optimisation
- Normalisation and denormalisation
It is also useful to understand different types of databases, including relational databases such as PostgreSQL and MySQL and NoSQL systems such as MongoDB or Cassandra.
2. Python for Data Engineering
Python is commonly used for pipeline logic, data transformation, API integration, automation, testing, and Spark workloads.
Important topics include:
- Variables and data types
- Functions
- Lists, dictionaries, and sets
- File handling
- Exception handling
- Object-oriented programming basics
- APIs
- JSON processing
- Logging
- Testing
- Pandas
- PySpark
A beginner does not need advanced software engineering skills before starting pipelines. However, the code should gradually become modular, testable, and maintainable.
3. Data Modelling
Data engineers need to understand how information should be organised before it reaches analytics systems.
Important concepts include:
- Primary and foreign keys
- Normalisation
- Denormalisation
- Fact and dimension tables
- Star schemas
- Slowly Changing Dimensions
- Partitioning
- Data types
- Schema evolution
The database design principles behind these concepts directly affect query performance, data quality, and maintainability.
4. ETL and ELT Pipelines
A data pipeline typically moves information through stages such as:
Source → Ingestion → Storage → Transformation → Validation → Destination
Learners should understand both:
- ETL: Extract, transform, then load
- ELT: Extract, load, then transform
Modern cloud data platforms frequently use ELT because raw data can first be loaded into scalable storage or warehouses before transformations are applied.
5. Data Storage and File Formats
A data engineer should understand storage beyond traditional databases.
Useful concepts include:
- Object storage
- Data warehouses
- Data lakes
- Lakehouse architectures
- Partitioned datasets
- Columnar storage
Important data formats include:
- CSV
- JSON
- Parquet
- Avro
- ORC
Parquet is particularly important for analytical workloads because its columnar structure supports efficient storage and selective reading of columns.
6. Distributed Data Processing
When datasets become too large for efficient processing on one machine, distributed frameworks become important.
Apache Spark remains a major technology for distributed processing, SQL workloads, DataFrames, and streaming applications.
A beginner should understand:
- Spark DataFrames
- Transformations and actions
- Lazy evaluation
- Partitions
- Shuffles
- Joins
- Caching
- Spark SQL
- PySpark
- Basic performance tuning
Spark’s current ecosystem continues to include Python, SQL, DataFrames, and Structured Streaming capabilities.
7. Workflow Orchestration
Production pipelines rarely consist of one script.
Tools such as Apache Airflow coordinate tasks, dependencies, schedules, retries, and failures.
An Airflow workflow is represented as a Dag containing tasks and dependencies that determine execution order.
Important concepts include:
- Dags
- Tasks
- Dependencies
- Scheduling
- Retries
- Sensors
- Backfills
- Logging
- Failure handling
8. Cloud Data Engineering
A learner should become comfortable with at least one major cloud platform:
- AWS
- Microsoft Azure
- Google Cloud
The goal is not to memorise every service. Instead, understand how cloud platforms provide:
- Object storage
- Compute
- Databases
- Data warehouses
- Identity and access management
- Networking
- Monitoring
9. Modern Transformation Tools
SQL-based transformation has become an important part of modern data stacks.
dbt, for example, structures transformations as SQL models and supports workflows around testing, documentation, lineage, and deployment.
For beginners, dbt should usually come after SQL and data modelling, not before them.
10. Streaming Fundamentals
Streaming is not essential for every entry-level role, but it becomes useful for real-time architectures.
Apache Kafka is designed around event streaming, where systems continuously capture, store, process, and route streams of events.
Important beginner concepts include:
- Producers
- Consumers
- Topics
- Partitions
- Offsets
- Consumer groups
- Event-driven pipelines
How Long Does It Take to Learn Data Engineering?
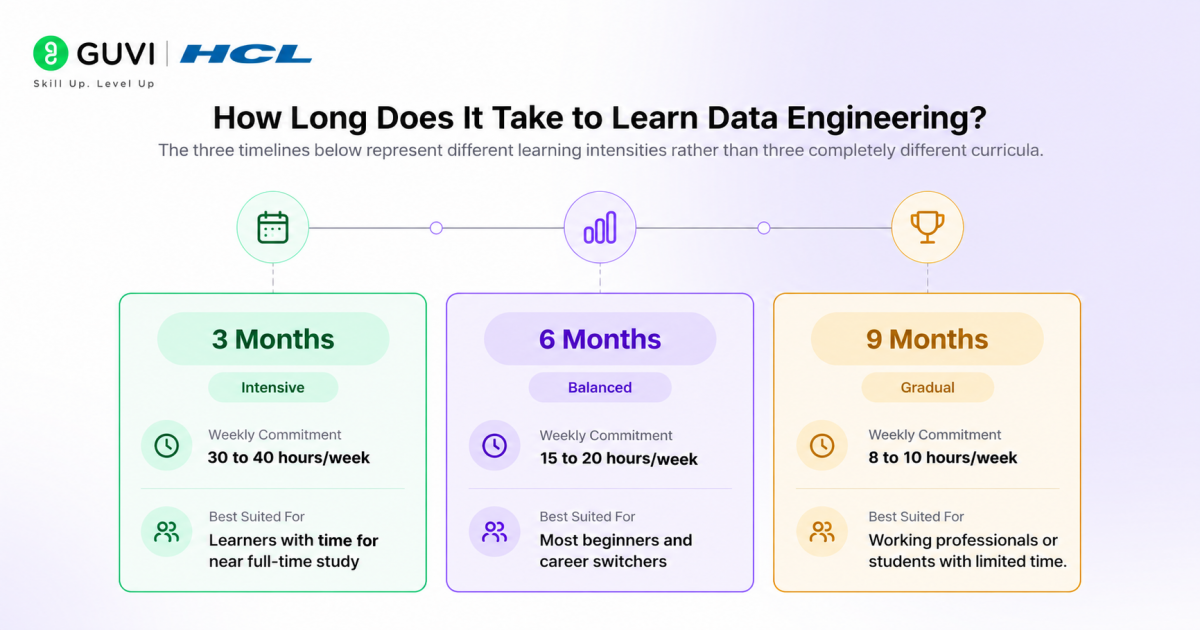
The three timelines below represent different learning intensities rather than three completely different curricula.
| Learning Path | Study Time | Approximate Weekly Commitment | Best Suited For |
| 3 Months | Intensive | 30 to 40 hours | Learners with time for near full-time study |
| 6 Months | Balanced | 15 to 20 hours | Most beginners and career switchers |
| 9 Months | Gradual | 10 to 15 hours | Working professionals and slower-paced learners |
The learning path should be measured by skills demonstrated, not only calendar months.
Becoming a Data Engineer in 3 Months: 30 to 40 Hours a Week
Learning data engineering in three months is an intensive path. It is most realistic for learners who can study almost every day or already have some programming, analytics, or database experience.
Month 1: SQL, Python, and Data Foundations
Weeks 1 to 2: Data Engineering Fundamentals
Learn:
- What data engineers do
- Data pipeline architecture
- ETL vs ELT
- Structured vs semi-structured data
- Batch vs streaming pipelines
- Data warehouses vs data lakes
Build a simple pipeline that reads a CSV file, cleans records, and writes the transformed output.
Weeks 3 to 4: SQL and Python
Focus heavily on:
- SQL joins
- Aggregations
- CTEs
- Window functions
- Python functions
- File processing
- APIs
- Pandas
- Error handling
Practice SQL every day because weak SQL can become a major bottleneck later.
Month 2: Data Pipelines, Storage, and Spark
Weeks 5 to 6: Databases and Data Modelling
Learn:
- PostgreSQL or MySQL
- Table design
- Primary and foreign keys
- Indexes
- Normalisation
- Dimensional modelling
- Fact and dimension tables
Build a small analytical schema from raw transaction data.
Weeks 7 to 8: Storage and Spark
Learn:
- Object storage concepts
- CSV, JSON, and Parquet
- PySpark DataFrames
- Transformations
- Joins
- Partitioning
- Spark SQL
Build a Spark pipeline that reads raw data, applies transformations, and writes partitioned Parquet files.
Month 3: Orchestration, Cloud, and Portfolio Project
Weeks 9 to 10: Airflow and Pipeline Orchestration
Learn:
- Dags
- Tasks
- Scheduling
- Dependencies
- Retries
- Logging
Convert an existing pipeline into a scheduled Airflow workflow.
Weeks 11 to 12: Cloud and End-to-End Project
Choose AWS, Azure, or Google Cloud.
Build one end-to-end project that includes:
Source → Ingestion → Cloud Storage → Transformation → Database/Warehouse → Orchestration → Data Quality Checks
By the end of three months, the learner should be able to explain not only how the pipeline works, but also why each component was selected.
Becoming a Data Engineer in 6 Months: 15 to 20 Hours a Week
A six-month path is more realistic for someone beginning from scratch while managing college, freelance work, or a full-time job.
It allows more time for repetition, debugging, and project development.
Months 1 and 2: Programming, SQL, and Databases
Focus on:
- Python fundamentals
- Data structures
- File processing
- APIs
- SQL fundamentals
- Advanced SQL
- PostgreSQL or MySQL
- Database design
- Git and GitHub
Projects during this phase can include:
- API-to-database ingestion
- CSV cleaning pipeline
- SQL analytics project
Months 3 and 4: Data Engineering Systems
Progress into:
- ETL and ELT
- Data modelling
- Object storage
- Parquet
- Spark
- PySpark
- Airflow
- Data quality testing
At this stage, learners should begin working with datasets that contain missing values, duplicates, schema inconsistencies, and late-arriving records rather than perfectly clean tutorial data.
Months 5 and 6: Cloud, Modern Stack, and Portfolio
Select one cloud provider and learn enough to deploy a working data pipeline.
Then add:
- dbt fundamentals
- Docker basics
- Pipeline testing
- Logging
- Monitoring concepts
- CI/CD fundamentals
- Basic Kafka concepts if streaming is relevant
Build at least two substantial projects.
One should demonstrate batch data engineering.
Another can demonstrate either:
- Cloud data warehousing
- Streaming
- Spark processing
- Analytics engineering
The six-month route generally provides more time to understand why systems fail and how to debug them, which is an important part of real data engineering.
Becoming a Data Engineer in 9 Months: 10 to 15 Hours a Week
A nine-month roadmap suits learners who need a sustainable schedule and want deeper practice before applying for roles.
Months 1 to 3: Strong Foundations
Spend this phase mastering:
- Python
- SQL
- Relational databases
- Git
- Linux basics
- APIs
- File formats
- Database design
Instead of rushing into Spark, make sure complex SQL queries and Python data-processing scripts can be written independently.
Months 4 to 6: Core Data Engineering
Move into:
- ETL and ELT
- Data modelling
- Data warehouses
- Data lakes
- Parquet
- Spark
- Airflow
- Cloud storage
Build several smaller pipelines before attempting one large architecture.
Months 7 to 8: Production-Oriented Skills
Add:
- dbt
- Data quality checks
- Logging
- Monitoring
- Docker
- Testing
- CI/CD concepts
- Cost and performance awareness
Streaming with Kafka can be introduced if it matches the target role.
Month 9: Portfolio and Interview Preparation
Build or refine two to three projects that demonstrate different engineering problems.
For each project, document:
- Problem being solved
- Architecture
- Data source
- Storage layer
- Transformation logic
- Orchestration
- Data model
- Testing strategy
- Failure handling
- Deployment
- Trade-offs
The final month should also include SQL practice, Python exercises, data modelling questions, pipeline design discussions, and system-design fundamentals.

What Factors Affect How Long It Takes to Learn Data Engineering?
The same roadmap does not take the same amount of time for every learner.
1. Existing SQL Knowledge
Someone already comfortable with joins, CTEs, window functions, and query optimisation can move much faster.
2. Programming Experience
Previous Python, Java, or Scala experience reduces the time required for scripting and debugging.
3. Cloud Experience
Developers already familiar with cloud infrastructure have an advantage when learning storage, warehouses, permissions, and deployment.
4. Weekly Study Hours
Ten focused hours every week create a different learning pace from 35 hours.
Consistency matters more than occasional long study sessions.
5. Hands-On Practice
Watching tutorials can make concepts feel familiar without making them usable.
Building and debugging pipelines exposes learners to problems such as:
- Incorrect schemas
- Duplicate records
- Null values
- Broken API requests
- Failed tasks
- Slow joins
- Incorrect partitions
- Authentication errors
- Schema changes
Solving these problems is what develops practical engineering ability.
Which Data Engineering Tools Should Beginners Prioritise in 2026?
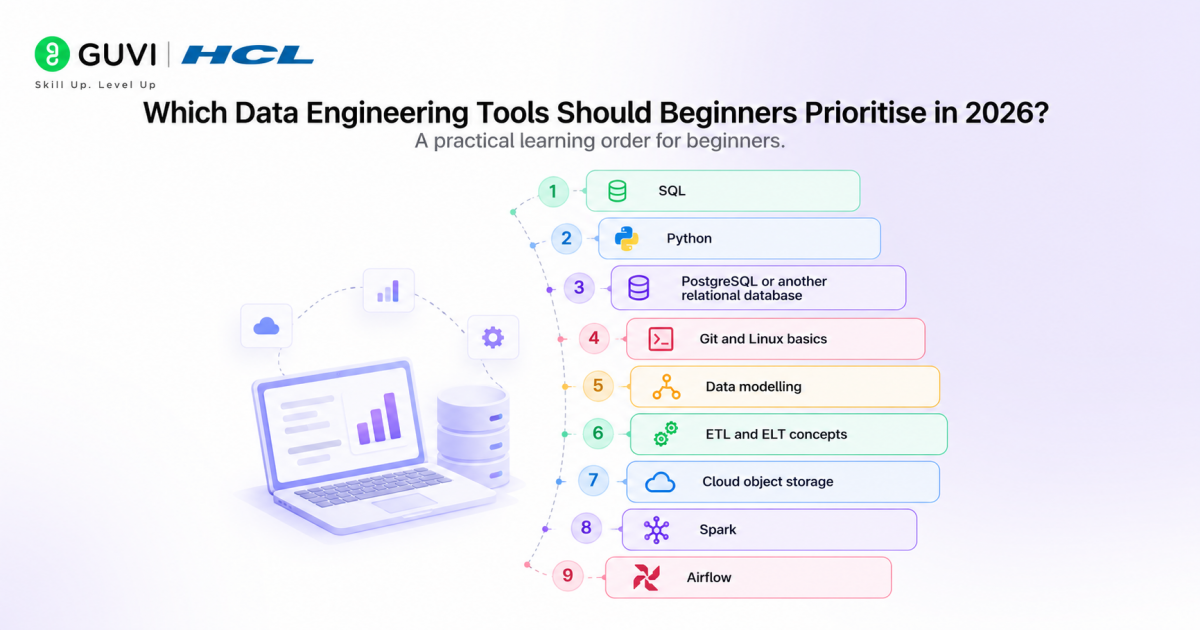
A common beginner mistake is trying to learn every technology mentioned in job descriptions.
A more effective order is:
- SQL
- Python
- PostgreSQL or another relational database
- Git and Linux basics
- Data modelling
- ETL and ELT concepts
- Cloud object storage
- Spark
- Airflow
- One cloud data warehouse or lakehouse platform
- dbt
- Kafka, if streaming is relevant
Technologies such as Hadoop, Hive, HBase, Cassandra, NiFi, Luigi, and Scala can still be relevant in specific environments. However, they should be learned when a target role or project requires them rather than treated as mandatory prerequisites for every beginner.
Best Data Engineering Projects for Beginners
Projects should demonstrate complete systems rather than isolated scripts.
1. API to Data Warehouse Pipeline
Create a pipeline that:
- Extracts data from an API
- Validates the response
- Stores raw JSON
- Transforms records
- Loads them into PostgreSQL or a warehouse
- Runs on a schedule
2. E-commerce Analytics Pipeline
Use order, customer, and product datasets.
Build:
- Raw ingestion
- Cleaned tables
- Fact and dimension models
- SQL transformations
- Data quality checks
- Analytical queries
3. Spark Batch Processing Pipeline
Process a larger dataset using PySpark.
Demonstrate:
- DataFrames
- Filtering
- Aggregation
- Joins
- Partitioning
- Parquet output
4. Airflow-Orchestrated Pipeline
Build an Airflow Dag with:
- Extract task
- Validation task
- Transformation task
- Load task
- Failure handling
- Retries
5. Streaming Data Pipeline
For a more advanced portfolio project:
Event Producer → Kafka → Stream Processing → Database or Warehouse
This demonstrates knowledge beyond traditional batch pipelines.
Learners looking for additional practical ideas can explore these cloud computing projects.
How to Know When You Are Job-Ready for Data Engineering
Finishing a roadmap does not automatically mean someone is job-ready.
A stronger test is whether the learner can complete these tasks independently:
- Write complex SQL using joins, CTEs, and window functions.
- Build Python scripts that consume APIs and process files.
- Design relational and analytical data models.
- Explain ETL and ELT architecture.
- Work with CSV, JSON, and Parquet.
- Build a Spark transformation pipeline.
- Schedule pipelines using Airflow.
- Use Git for version control.
- Deploy a basic pipeline on one cloud platform.
- Add validation, logging, and basic tests.
- Diagnose why a failed pipeline did not complete.
- Explain architecture decisions and trade-offs.
A learner who can demonstrate these abilities through working projects is much closer to interview readiness than someone who has completed several courses without building anything.
Common Mistakes That Slow Down Data Engineering Learning
1. Learning Too Many Tools at Once
Knowing five orchestration platforms superficially is less useful than understanding one properly.
Start with one stack and expand when the fundamentals are strong.
2. Skipping SQL
Data engineering is heavily dependent on querying and transforming structured data.
Strong SQL should be treated as a core engineering skill rather than an introductory topic to finish quickly.
3. Starting With Big Data Too Early
Spark becomes easier to understand after learners know databases, SQL, partitions, files, and basic data processing.
4. Building Only Tutorial Projects
Copying an existing pipeline does not demonstrate independent problem solving.
Change datasets, introduce failures, redesign schemas, and add new requirements.
5. Ignoring Testing and Data Quality
A pipeline that completes successfully can still produce incorrect data.
Learn to test:
- Null constraints
- Unique keys
- Row counts
- Schema expectations
- Referential integrity
- Accepted values
6. Ignoring Failure Scenarios
Real pipelines encounter API outages, missing files, duplicate events, schema changes, expired credentials, and unavailable databases.
Projects should demonstrate how these situations are handled.
Build your data engineering foundations with HCL GUVI’s Big Data Engineering Course. Learn Python, SQL, data warehousing, Hadoop, Apache Spark, data pipelines, and big data concepts through structured, self-paced training designed for aspiring data engineers.
Should Beginners Learn Hadoop in 2026?
Hadoop concepts remain useful for understanding the history and architecture of distributed data systems, and some organisations still operate Hadoop-based environments.
However, a beginner does not need to make Hadoop the centre of a modern data engineering roadmap.
For many learners, SQL, Python, cloud storage, Spark, orchestration, warehouses, and modern transformation workflows offer a more direct path toward current data engineering skills.
Hadoop, Hive, HBase, or related ecosystem tools can then be added when a specific employer or project requires them.
Is Data Engineering Difficult to Learn?
Data engineering has a broad learning curve because it combines software engineering, databases, distributed systems, cloud infrastructure, and data architecture.
The challenge is usually not understanding one individual tool.
The harder part is understanding how multiple components work together:
- Where does the data come from?
- How is it stored?
- How is it transformed?
- How is the pipeline scheduled?
- How is bad data detected?
- What happens when a task fails?
- How does the system scale?
Once learners begin thinking in terms of complete data flows rather than separate technologies, the subject becomes much easier to organise.
Conclusion
There is no universal answer to how long it takes to learn data engineering. A focused learner may build strong foundations in three intensive months, while six months provides a more balanced path and nine months gives beginners more time for deeper practice, portfolio development, and interview preparation.
The most important factor is not completing a fixed list of tools. A capable data engineer understands how data moves from source systems through ingestion, storage, transformation, orchestration, validation, and analytical destinations.
In 2026, a strong beginner roadmap should prioritise SQL, Python, databases, data modelling, cloud platforms, Spark, Airflow, modern transformation workflows, and practical projects. Consistent hands-on work with imperfect real-world data is what turns these individual skills into genuine data engineering ability.
FAQ
1. Can I Learn Data Engineering in 3 Months?
Yes, three months can be enough to build a strong foundation if the learner can dedicate around 30 to 40 focused hours each week. The priority should be SQL, Python, databases, data modelling, pipelines, Spark, orchestration, cloud fundamentals, and at least one complete portfolio project. Three months does not guarantee professional mastery or employment.
2. How Long Does It Take to Become Job-Ready as a Data Engineer?
For many beginners, approximately 6 to 9 months of consistent study and project work is a reasonable learning target. Someone with existing software development, SQL, cloud, or analytics experience may progress faster. Job readiness should ultimately be measured through practical skills rather than time alone.
3. Can a Beginner Learn Data Engineering Without Coding Experience?
Yes. A complete beginner can start with Python and SQL before moving into databases, data pipelines, Spark, Airflow, and cloud platforms. A longer 6- to 9-month roadmap usually provides more time to develop programming and debugging skills properly.
4. Is Python or SQL More Important for Data Engineering?
Both are important, but SQL is often used constantly for querying, transforming, validating, and modelling structured data. Python complements SQL by supporting automation, APIs, pipeline logic, testing, and distributed processing with PySpark.
5. What Should I Learn First for Data Engineering?
Start with SQL, Python, relational databases, Git, and basic Linux commands. Next, learn data modelling, ETL and ELT, storage formats, Spark, Airflow, and one cloud platform. Tools such as dbt and Kafka can be added after the core workflow is understood.
6. Do Data Engineers Need to Learn Cloud Computing?
Cloud skills are increasingly useful because modern data platforms commonly use cloud storage, managed databases, warehouses, distributed compute, and orchestration services. Beginners do not need to learn AWS, Azure, and Google Cloud simultaneously. Becoming comfortable with one platform is a better starting point.
Success Stories

About the Author
Vaishali
I'm a seasoned writer with four years of experience across technical, non-technical, and just about every genre or niche you can imagine. Adaptable and curious, I enjoy exploring new topics and making information engaging and easy to understand. Fueled by a steady stream of tea, I approach each project with creativity, reliability, and genuine enthusiasm for storytelling.
View all posts by Vaishali
Connect with me @






Did you enjoy this article?